

LLM benchmark results, 2026-08-03
Metric Key
Section titled “Metric Key”Quick reference for the columns in every table below.
| Metric | Range | Direction | What it means |
|---|---|---|---|
| F1 (accuracy) | 0 to 1 | higher is better | Combined score of precision and recall against the human-verified ground-truth ad spans. F1 = 0 means the model found nothing right; F1 = 1 means it found every ad with the correct boundaries. Uses IoU >= 0.5 (predicted span must overlap truth span by at least half) to count a match. |
| Cost / episode | USD | lower is better | Average dollars per episode at the current pricing snapshot. Recomputed from token counts so all rows compare at the same prices regardless of when the call ran. |
| F1 / $ | ratio | higher is better | F1 divided by cost-per-episode. Cheap accurate models score highest. Free-tier models are rank-listed separately because the ratio is undefined. |
| p50 / p95 latency | seconds | lower is better, with caveats | Median (p50) and tail (p95) wall-clock response time. Note: for models routed through OpenRouter (everything except claude-*), this includes OpenRouter’s queueing and upstream-provider latency, not just the model itself. Treat as a load/availability indicator, not a model-quality signal. |
| JSON compliance | 0 to 1 | higher is better | Fraction of responses that parsed as a clean JSON array matching the requested schema. 1.0 = always clean; lower = used object wrappers ({ads: [...]}), markdown fences, extra fields like sponsor, or required regex fallback to extract. |
| No-ad episode | PASS / FAIL | PASS desired | Negative-control test on ep-ai-cloud-essentials (which has no ads). PASS = zero predictions across all 15 windows. FAIL = the model false-positived on a non-ad segment, with the FP count shown. |
| F1 stdev | 0 to 1 | lower means more consistent | Standard deviation of F1 across the four ad-bearing episodes. High stdev = inconsistent across content types. |
| JSON mode | native / prompt-inject / mixed |
– | How the model received its JSON-output instruction. native = provider accepted response_format=json_object for at least 95% of calls; prompt-inject = provider rejected it and the runner fell back to instructing JSON in the prompt for at least 95% of calls; mixed = neither path crossed the threshold (sample mostly comes from intermittent provider rejections). Reads from json_format_used in calls.jsonl. Useful when picking a model whose provider may not support native JSON mode – a strong JSON compliance score from a prompt-inject model carries different weight than the same score from a native model. |
Glossary
Section titled “Glossary”- IoU (intersection over union): how much two time ranges overlap, expressed as
(overlap) / (union). 0 means no overlap, 1 means identical ranges. We use IoU >= 0.5 as the threshold for a predicted ad to count as matching a truth ad. - Trial: each (model, episode) pair runs 5 trials at temperature 0.0 to surface non-determinism. F1 numbers in tables are averaged across trials.
- Window: each episode is split into ~85-second sliding windows; the model judges each window independently. Per-window predictions are stitched together for episode-level scoring.
- Schema violations: number of times the response had at least one missing-required-field, wrong-type, or extra-key issue. Doesn’t tank F1, but signals brittleness.
- Extraction method: the route the parser took to recover the ad list.
json_array_directis the cleanest; method names withregex_*mean the JSON itself was malformed and we fell back to text matching.
Best Accuracy (F0.5 @ IoU >= 0.5)
Section titled “Best Accuracy (F0.5 @ IoU >= 0.5)”Models ranked by F0.5 (precision weighted 2x recall) against human-verified ground truth. MinusPod cuts the segments it flags, so cutting real content (a false positive) is worse than leaving an ad in (a false negative), and F0.5 penalizes it more. A model shares the tier above it unless it scores consistently lower across the same episodes (paired one-sided t-test, 95%); models that trade wins episode to episode share a tier, so order within a tier is not meaningful on this 12-episode corpus. Flags caveat a model without changing its rank. Cost includes free-tier models (shown at $0.00).
| Tier | Model | F0.5 | 95% CI | Precision | Recall | F1 | Cost / episode | p50 latency | JSON compliance | Flags |
|---|---|---|---|---|---|---|---|---|---|---|
| A | qwen/qwen3.6-plus |
0.829 | +/-0.096 | 0.853 | 0.807 | 0.807 | $1.1119 | 39.9s | 1.00 | |
| A | claude-haiku-4-5-20251001 |
0.804 | +/-0.134 | 0.786 | 0.919 | 0.837 | $1.2017 | 1.2s | 0.60 | (!) brittle JSON |
| A | qwen/qwen3.5-plus-02-15 |
0.801 | +/-0.087 | 0.814 | 0.820 | 0.794 | $1.2346 | 48.2s | 1.00 | |
| A | qwen/qwen3.6-flash |
0.788 | +/-0.085 | 0.783 | 0.848 | 0.802 | $0.5461 | 13.0s | 1.00 | (!) fails no-ad control |
| B | x-ai/grok-4.3 |
0.778 | +/-0.106 | 0.771 | 0.852 | 0.797 | $1.4987 | 3.9s | 1.00 | |
| B | claude-opus-4-8 |
0.770 | +/-0.104 | 0.779 | 0.795 | 0.767 | $7.8217 | 2.2s | 0.99 | |
| B | claude-sonnet-4-6 |
0.770 | +/-0.107 | 0.766 | 0.842 | 0.786 | $3.5376 | 1.4s | 0.96 | |
| B | openai/gpt-5.5 |
0.764 | +/-0.095 | 0.781 | 0.760 | 0.750 | $6.6806 | 6.4s | 0.87 | (!) brittle JSON (!) fails no-ad control |
| B | mistralai/mistral-medium-3.1 |
0.737 | +/-0.104 | 0.746 | 0.777 | 0.739 | $0.4380 | 0.9s | 1.00 | |
| B | google/gemini-3.5-flash |
0.737 | +/-0.126 | 0.742 | 0.769 | 0.738 | $3.5200 | 5.2s | 1.00 | |
| B | google/gemini-2.5-flash |
0.728 | +/-0.141 | 0.702 | 0.922 | 0.777 | $0.3435 | 1.0s | 1.00 | |
| B | google/gemini-3.1-flash-lite |
0.710 | +/-0.131 | 0.688 | 0.900 | 0.756 | $0.2762 | 0.8s | 0.96 | (!) fails no-ad control |
| C | qwen/qwen3.5-27b |
0.710 | +/-0.086 | 0.742 | 0.677 | 0.683 | $3.2163 | 68.7s | 0.85 | (!) brittle JSON |
| C | google/gemma-4-31b-it |
0.709 | +/-0.139 | 0.700 | 0.792 | 0.729 | $0.1291 | 2.2s | 0.85 | (!) brittle JSON (!) fails no-ad control |
| C | minimax/minimax-m3 |
0.706 | +/-0.110 | 0.703 | 0.778 | 0.720 | $0.4367 | 8.8s | 0.88 | (!) brittle JSON |
| C | google/gemini-2.5-pro |
0.704 | +/-0.111 | 0.697 | 0.809 | 0.726 | $3.8631 | 14.2s | 0.97 | (!) fails no-ad control |
| C | deepseek/deepseek-v4-flash |
0.695 | +/-0.088 | 0.682 | 0.818 | 0.725 | $0.1182 | 3.7s | 0.81 | (!) brittle JSON (!) fails no-ad control |
| C | openai/gpt-5.4 |
0.685 | +/-0.115 | 0.683 | 0.781 | 0.700 | $2.5345 | 1.8s | 0.81 | (!) brittle JSON (!) fails no-ad control |
| C | claude-opus-4-7 |
0.683 | +/-0.149 | 0.702 | 0.685 | 0.669 | $7.8054 | 2.2s | 1.00 | |
| C | openai/o3 |
0.682 | +/-0.181 | 0.787 | 0.516 | 0.595 | $3.0485 | 8.1s | 0.92 | |
| C | deepseek/deepseek-r1 |
0.677 | +/-0.125 | 0.668 | 0.789 | 0.702 | $1.1157 | 19.9s | 0.97 | (!) fails no-ad control |
| C | openai/gpt-oss-120b |
0.629 | +/-0.140 | 0.622 | 0.754 | 0.653 | $0.0643 | 3.0s | 0.70 | (!) brittle JSON (!) fails no-ad control |
| C | openai/gpt-5.4-mini |
0.629 | +/-0.129 | 0.623 | 0.750 | 0.651 | $0.7644 | 1.2s | 0.81 | (!) brittle JSON (!) fails no-ad control |
| C | nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.621 | +/-0.167 | 0.671 | 0.550 | 0.579 | $0.2159 | 24.2s | 0.71 | (!) brittle JSON |
| C | meta-llama/llama-4-scout |
0.585 | +/-0.120 | 0.599 | 0.641 | 0.591 | $0.0807 | 0.8s | 0.82 | (!) brittle JSON |
| D | google/gemini-2.5-flash-lite |
0.564 | +/-0.140 | 0.538 | 0.810 | 0.618 | $0.1104 | 0.9s | 0.97 | (!) fails no-ad control |
| D | mistralai/codestral-2508 |
0.556 | +/-0.136 | 0.554 | 0.691 | 0.577 | $0.3241 | 0.7s | 1.00 | |
| D | deepseek/deepseek-r1-0528 |
0.532 | +/-0.149 | 0.531 | 0.711 | 0.557 | $1.0181 | 16.5s | 0.88 | (!) brittle JSON (!) fails no-ad control |
| D | mistralai/mistral-large-2512 |
0.499 | +/-0.143 | 0.468 | 0.815 | 0.563 | $0.5599 | 2.6s | 1.00 | |
| D | qwen/qwen3-235b-a22b-2507 |
0.491 | +/-0.163 | 0.474 | 0.648 | 0.529 | $0.0735 | 2.3s | 0.79 | (!) brittle JSON (!) fails no-ad control |
| D | deepseek/deepseek-v4-pro |
0.490 | +/-0.157 | 0.577 | 0.379 | 0.424 | $0.6376 | 26.4s | 0.87 | (!) brittle JSON |
| E | deepseek/deepseek-v3.2 |
0.453 | +/-0.119 | 0.496 | 0.399 | 0.416 | $0.2328 | 2.7s | 0.88 | (!) brittle JSON (!) fails no-ad control |
| E | moonshotai/kimi-k2.6 |
0.452 | +/-0.191 | 0.505 | 0.433 | 0.422 | $2.2593 | 35.3s | 0.57 | (!) brittle JSON (!) fails no-ad control |
| E | meta-llama/llama-4-maverick |
0.450 | +/-0.194 | 0.443 | 0.540 | 0.470 | $0.1508 | 1.1s | 0.81 | (!) brittle JSON (!) fails no-ad control |
| E | cohere/command-a |
0.423 | +/-0.141 | 0.404 | 0.631 | 0.464 | $2.6688 | 3.8s | 0.71 | (!) brittle JSON (!) fails no-ad control |
| E | meta-llama/llama-3.3-70b-instruct |
0.417 | +/-0.173 | 0.452 | 0.393 | 0.395 | $0.1008 | 1.5s | 0.55 | (!) brittle JSON |
| F | nvidia/nemotron-nano-9b-v2 |
0.310 | +/-0.105 | 0.315 | 0.367 | 0.316 | $0.0813 | 12.0s | 0.92 | (!) fails no-ad control |
| F | qwen/qwen3-14b |
0.297 | +/-0.136 | 0.347 | 0.238 | 0.260 | $0.1261 | 20.9s | 0.28 | (!) brittle JSON (!) fails no-ad control |
| F | openai/gpt-3.5-turbo |
0.286 | +/-0.168 | 0.274 | 0.458 | 0.315 | $0.5091 | 1.3s | 0.71 | (!) brittle JSON (!) fails no-ad control |
| F | meta-llama/llama-3.1-8b-instruct |
0.258 | +/-0.130 | 0.268 | 0.261 | 0.251 | $0.0207 | 0.8s | 0.85 | (!) brittle JSON |
| F | deepseek/deepseek-r1-distill-llama-70b |
0.246 | +/-0.109 | 0.249 | 0.362 | 0.261 | $0.7331 | 2.0s | 0.74 | (!) brittle JSON (!) fails no-ad control |
| F | cohere/command-r-plus-08-2024 |
0.195 | +/-0.161 | 0.247 | 0.137 | 0.162 | $2.5787 | 1.0s | 0.98 | |
| F | microsoft/phi-4 |
0.191 | +/-0.142 | 0.236 | 0.132 | 0.157 | $0.0713 | 2.3s | 0.86 | (!) brittle JSON (!) fails no-ad control |
| G | openai/o4-mini |
0.112 | +/-0.060 | 0.183 | 0.049 | 0.075 | $1.8999 | 6.9s | 0.05 | (!) brittle JSON |
| H | qwen/qwen3-8b |
0.008 | +/-0.018 | 0.017 | 0.003 | 0.005 | $0.2578 | 59.4s | 0.01 | (!) brittle JSON |
| H | mistralai/mistral-7b-instruct-v0.1 |
0.000 | +/-0.000 | 0.000 | 0.000 | 0.000 | $0.0000 | 7.1s | 0.16 | (!) brittle JSON |
Best Value (F0.5 per dollar)
Section titled “Best Value (F0.5 per dollar)”Paid-tier only, ranked by F0.5 per dollar. Free-tier models are excluded here because F0.5 / 0 is undefined; they are ranked separately under Best Free-Tier below. No confidence tiers on this table – a point ratio does not group cleanly – but the reliability flags still apply.
| Rank | Model | F0.5/$ | F0.5 | F1 | Cost / episode | Flags |
|---|---|---|---|---|---|---|
| 1 | meta-llama/llama-3.1-8b-instruct |
12.42 | 0.258 | 0.251 | $0.0207 | (!) brittle JSON |
| 2 | openai/gpt-oss-120b |
9.77 | 0.629 | 0.653 | $0.0643 | (!) brittle JSON (!) fails no-ad control |
| 3 | meta-llama/llama-4-scout |
7.25 | 0.585 | 0.591 | $0.0807 | (!) brittle JSON |
| 4 | qwen/qwen3-235b-a22b-2507 |
6.69 | 0.491 | 0.529 | $0.0735 | (!) brittle JSON (!) fails no-ad control |
| 5 | deepseek/deepseek-v4-flash |
5.88 | 0.695 | 0.725 | $0.1182 | (!) brittle JSON (!) fails no-ad control |
| 6 | google/gemma-4-31b-it |
5.49 | 0.709 | 0.729 | $0.1291 | (!) brittle JSON (!) fails no-ad control |
| 7 | google/gemini-2.5-flash-lite |
5.11 | 0.564 | 0.618 | $0.1104 | (!) fails no-ad control |
| 8 | meta-llama/llama-3.3-70b-instruct |
4.14 | 0.417 | 0.395 | $0.1008 | (!) brittle JSON |
| 9 | nvidia/nemotron-nano-9b-v2 |
3.81 | 0.310 | 0.316 | $0.0813 | (!) fails no-ad control |
| 10 | meta-llama/llama-4-maverick |
2.98 | 0.450 | 0.470 | $0.1508 | (!) brittle JSON (!) fails no-ad control |
| 11 | nvidia/llama-3.3-nemotron-super-49b-v1.5 |
2.88 | 0.621 | 0.579 | $0.2159 | (!) brittle JSON |
| 12 | microsoft/phi-4 |
2.68 | 0.191 | 0.157 | $0.0713 | (!) brittle JSON (!) fails no-ad control |
| 13 | google/gemini-3.1-flash-lite |
2.57 | 0.710 | 0.756 | $0.2762 | (!) fails no-ad control |
| 14 | qwen/qwen3-14b |
2.35 | 0.297 | 0.260 | $0.1261 | (!) brittle JSON (!) fails no-ad control |
| 15 | google/gemini-2.5-flash |
2.12 | 0.728 | 0.777 | $0.3435 | |
| 16 | deepseek/deepseek-v3.2 |
1.94 | 0.453 | 0.416 | $0.2328 | (!) brittle JSON (!) fails no-ad control |
| 17 | mistralai/codestral-2508 |
1.72 | 0.556 | 0.577 | $0.3241 | |
| 18 | mistralai/mistral-medium-3.1 |
1.68 | 0.737 | 0.739 | $0.4380 | |
| 19 | minimax/minimax-m3 |
1.62 | 0.706 | 0.720 | $0.4367 | (!) brittle JSON |
| 20 | qwen/qwen3.6-flash |
1.44 | 0.788 | 0.802 | $0.5461 | (!) fails no-ad control |
| 21 | mistralai/mistral-large-2512 |
0.89 | 0.499 | 0.563 | $0.5599 | |
| 22 | openai/gpt-5.4-mini |
0.82 | 0.629 | 0.651 | $0.7644 | (!) brittle JSON (!) fails no-ad control |
| 23 | deepseek/deepseek-v4-pro |
0.77 | 0.490 | 0.424 | $0.6376 | (!) brittle JSON |
| 24 | qwen/qwen3.6-plus |
0.75 | 0.829 | 0.807 | $1.1119 | |
| 25 | claude-haiku-4-5-20251001 |
0.67 | 0.804 | 0.837 | $1.2017 | (!) brittle JSON |
| 26 | qwen/qwen3.5-plus-02-15 |
0.65 | 0.801 | 0.794 | $1.2346 | |
| 27 | deepseek/deepseek-r1 |
0.61 | 0.677 | 0.702 | $1.1157 | (!) fails no-ad control |
| 28 | openai/gpt-3.5-turbo |
0.56 | 0.286 | 0.315 | $0.5091 | (!) brittle JSON (!) fails no-ad control |
| 29 | deepseek/deepseek-r1-0528 |
0.52 | 0.532 | 0.557 | $1.0181 | (!) brittle JSON (!) fails no-ad control |
| 30 | x-ai/grok-4.3 |
0.52 | 0.778 | 0.797 | $1.4987 | |
| 31 | deepseek/deepseek-r1-distill-llama-70b |
0.34 | 0.246 | 0.261 | $0.7331 | (!) brittle JSON (!) fails no-ad control |
| 32 | openai/gpt-5.4 |
0.27 | 0.685 | 0.700 | $2.5345 | (!) brittle JSON (!) fails no-ad control |
| 33 | openai/o3 |
0.22 | 0.682 | 0.595 | $3.0485 | |
| 34 | qwen/qwen3.5-27b |
0.22 | 0.710 | 0.683 | $3.2163 | (!) brittle JSON |
| 35 | claude-sonnet-4-6 |
0.22 | 0.770 | 0.786 | $3.5376 | |
| 36 | google/gemini-3.5-flash |
0.21 | 0.737 | 0.738 | $3.5200 | |
| 37 | moonshotai/kimi-k2.6 |
0.20 | 0.452 | 0.422 | $2.2593 | (!) brittle JSON (!) fails no-ad control |
| 38 | google/gemini-2.5-pro |
0.18 | 0.704 | 0.726 | $3.8631 | (!) fails no-ad control |
| 39 | cohere/command-a |
0.16 | 0.423 | 0.464 | $2.6688 | (!) brittle JSON (!) fails no-ad control |
| 40 | openai/gpt-5.5 |
0.11 | 0.764 | 0.750 | $6.6806 | (!) brittle JSON (!) fails no-ad control |
| 41 | claude-opus-4-8 |
0.10 | 0.770 | 0.767 | $7.8217 | |
| 42 | claude-opus-4-7 |
0.09 | 0.683 | 0.669 | $7.8054 | |
| 43 | cohere/command-r-plus-08-2024 |
0.08 | 0.195 | 0.162 | $2.5787 | |
| 44 | openai/o4-mini |
0.06 | 0.112 | 0.075 | $1.8999 | (!) brittle JSON |
| 45 | qwen/qwen3-8b |
0.03 | 0.008 | 0.005 | $0.2578 | (!) brittle JSON |
Best Free-Tier (F0.5)
Section titled “Best Free-Tier (F0.5)”Models that came back at $0.00 cost, ranked by F0.5 with the same CI and flags as Best Accuracy. Tiers are computed within the free-tier set against its own leader, so a tier letter here is not comparable to the same letter in Best Accuracy. Free-tier eligibility on OpenRouter depends on the attribution headers wired into the benchmark (HTTP-Referer, X-Title); a model showing as free here may bill on your own deployment if those headers are missing.
| Tier | Model | F0.5 | 95% CI | Precision | Recall | F1 | p50 latency | JSON compliance | Flags |
|---|---|---|---|---|---|---|---|---|---|
| A | mistralai/mistral-7b-instruct-v0.1 |
0.000 | +/-0.000 | 0.000 | 0.000 | 0.000 | 7.1s | 0.16 | (!) brittle JSON |
Charts
Section titled “Charts”Cost vs F1 (Pareto)
Section titled “Cost vs F1 (Pareto)”Each model is one colored point. Lower-left is unhelpful (expensive, inaccurate). Upper-left is the sweet spot (accurate, cheap). The legend below the chart shows each model’s color next to its F1 and cost-per-episode.
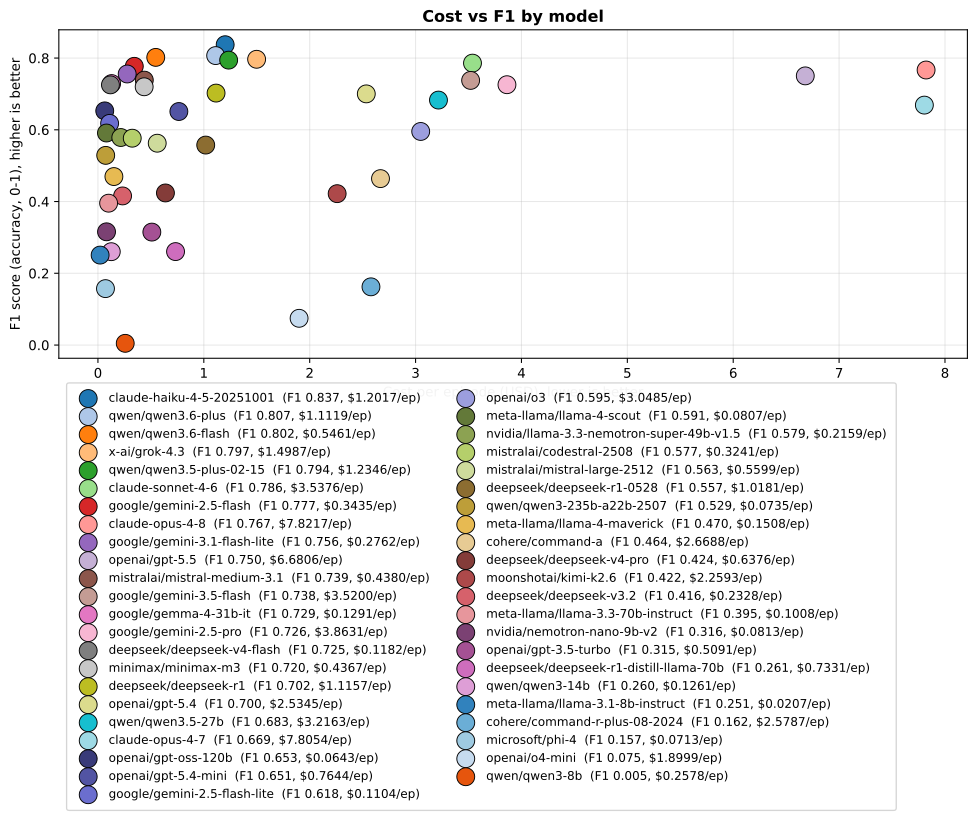
Source data: Best Accuracy, Best Value, Best Free-Tier
JSON schema compliance
Section titled “JSON schema compliance”Fraction of each model’s responses that parsed as a clean JSON array. 1.0 means every response came back exactly as requested; lower numbers mean the parser had to recover from markdown fences, object wrappers, or extra fields.
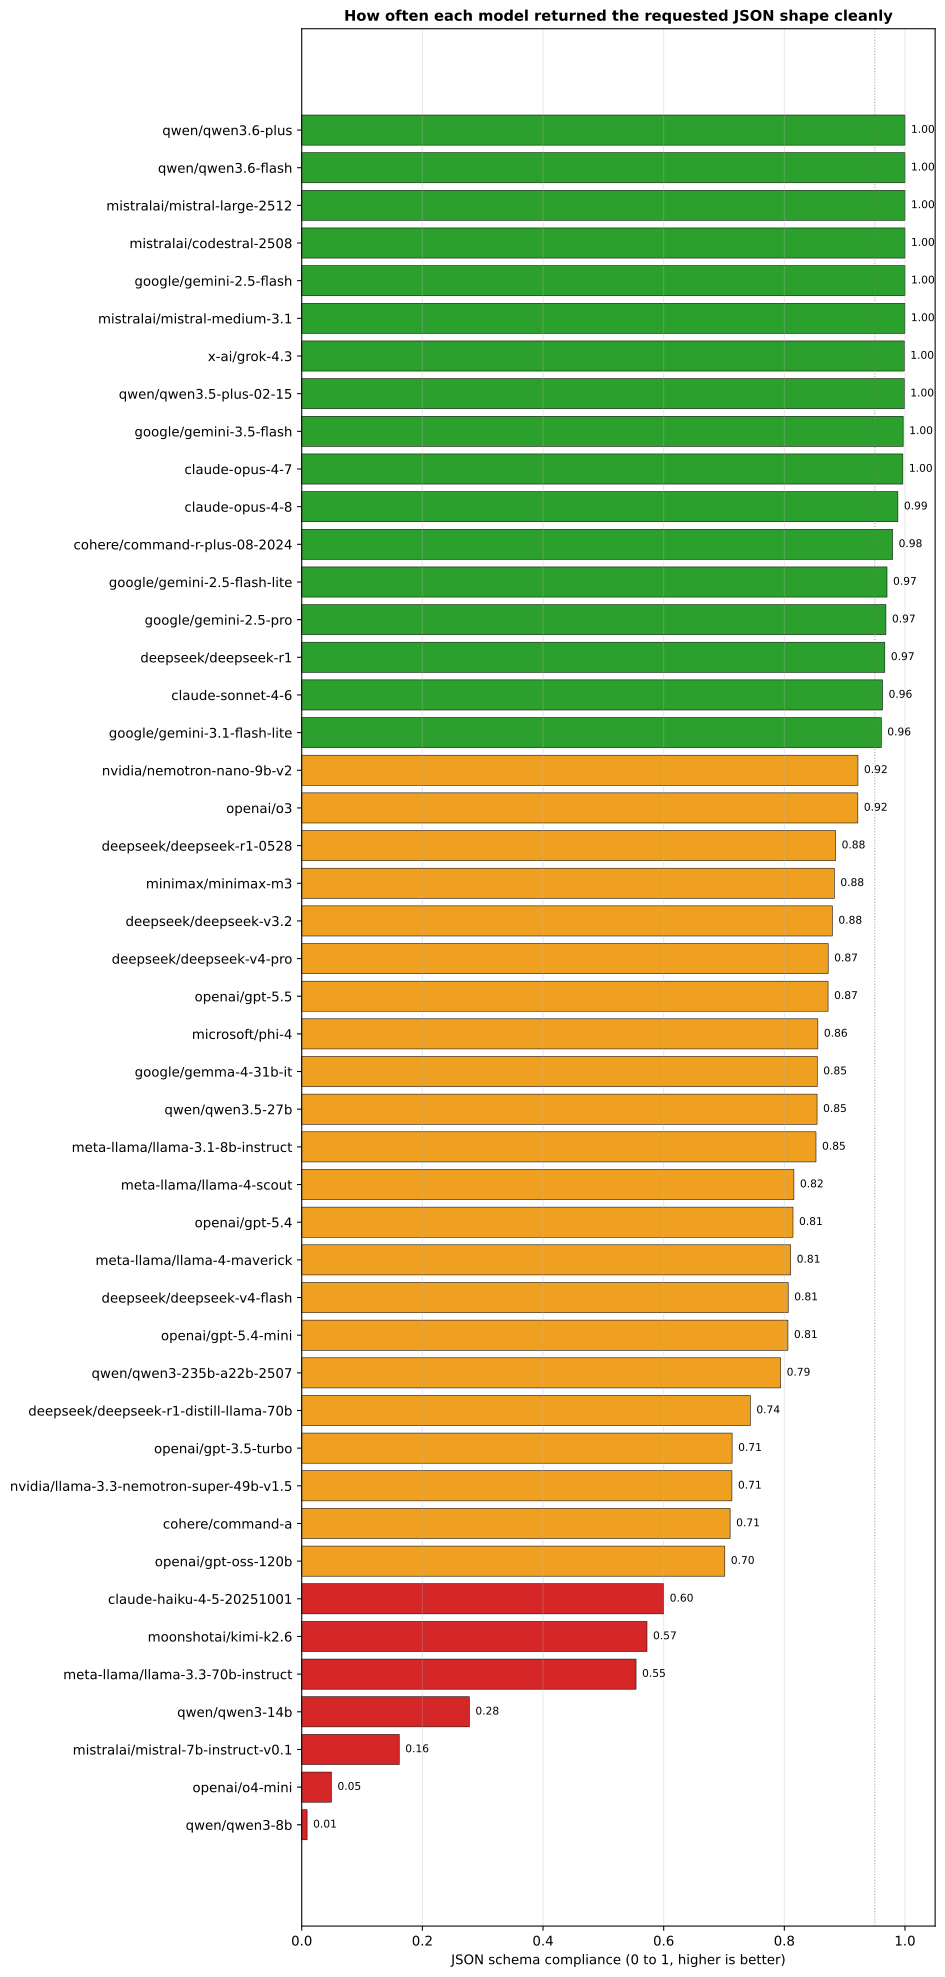
Source data: Per-Model Detail (JSON compliance field)
F1 by episode (heatmap)
Section titled “F1 by episode (heatmap)”F1 score for each (model, episode) pair. Greener is more accurate, redder is less. The no-ad episode is excluded. It has no F1 because it’s a PASS/FAIL negative control.
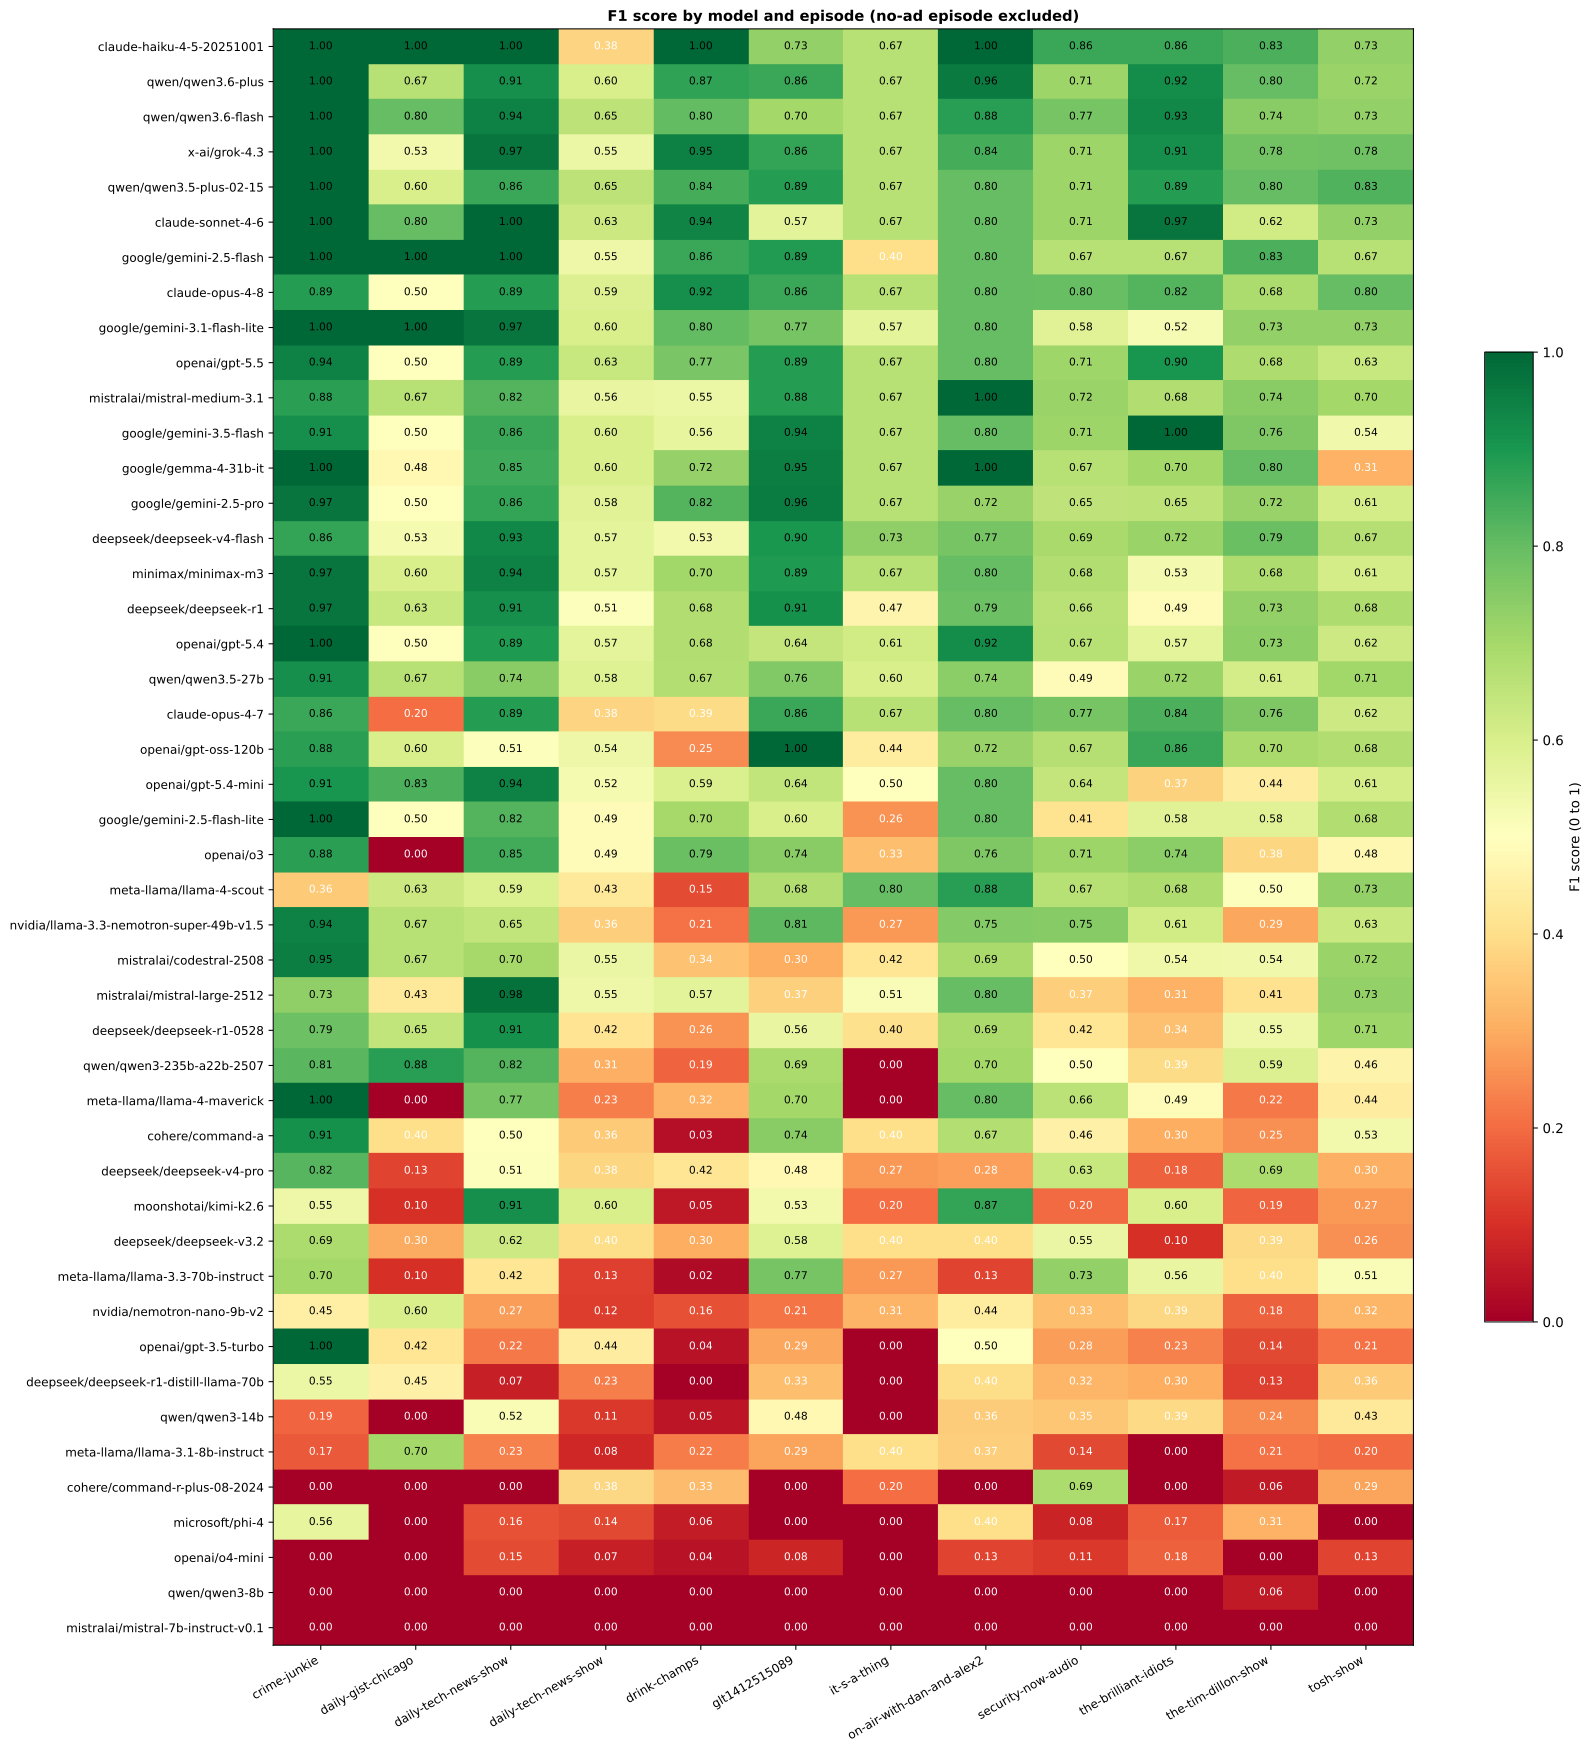
Source data: Quick Comparison, Per-Episode Detail
Confidence calibration (heatmap)
Section titled “Confidence calibration (heatmap)”One row per model, one column per self-reported confidence bin. Cell text is the actual hit rate at that bin plus the sample size; cell color is the calibration error (actual minus bin midpoint). Red cells mean the model claimed high confidence but was usually wrong; green is well-calibrated; blue is underconfident. Empty cells mean the model never produced a prediction in that bin. Models are sorted from most overconfident at the top to most underconfident at the bottom.
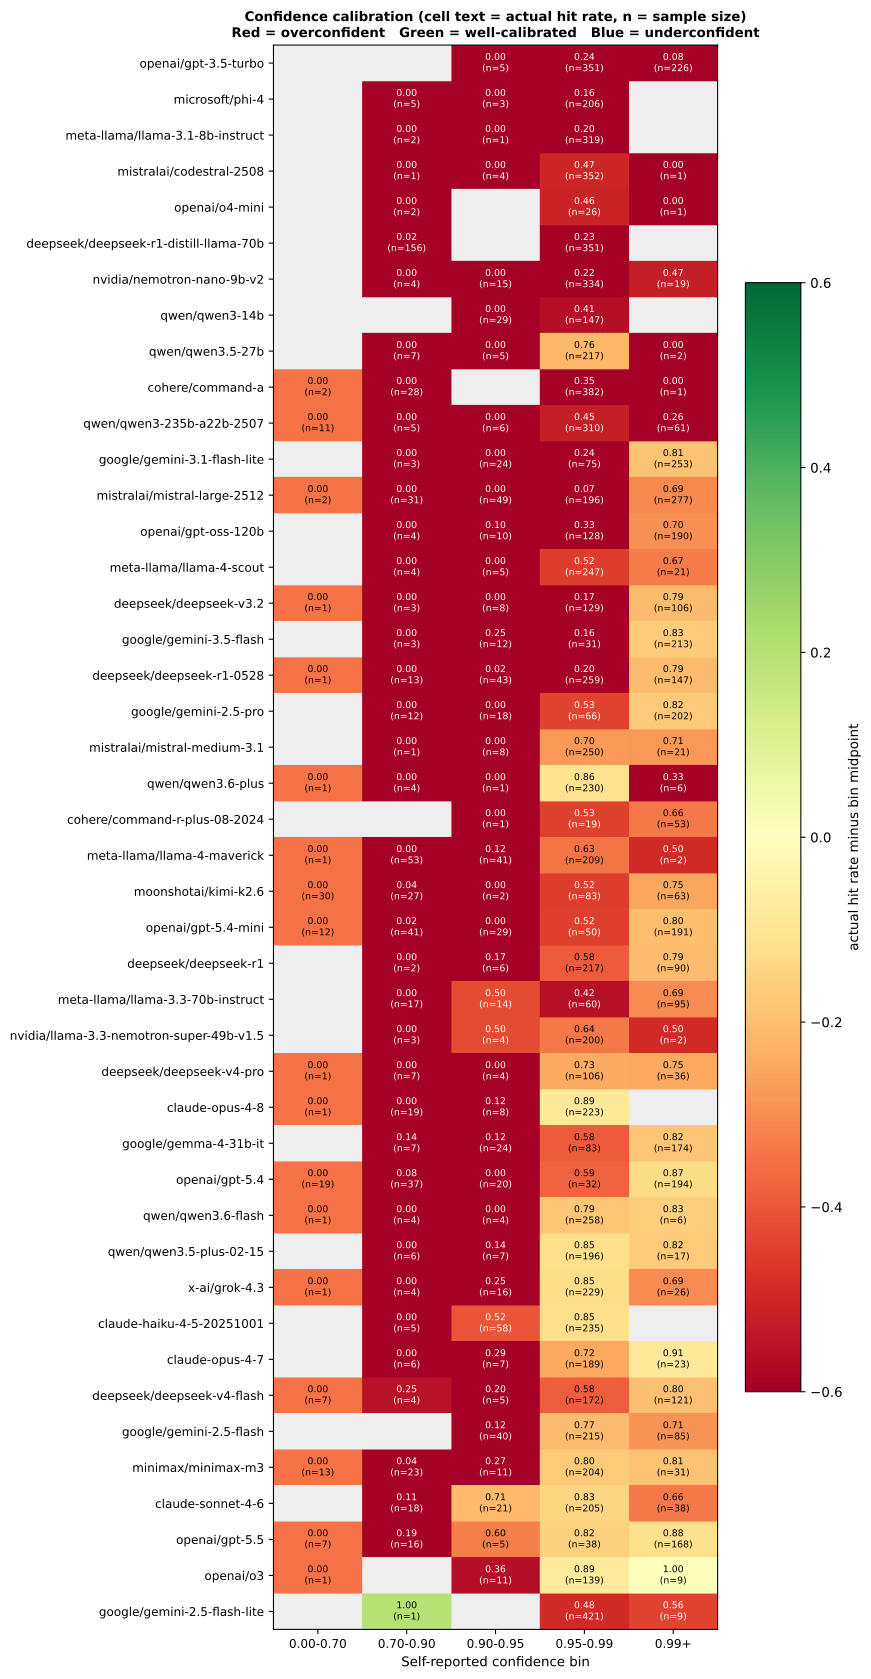
Source data: Confidence calibration table
Latency percentiles
Section titled “Latency percentiles”p50, p90, p99, and max per model on a log scale. The gap between p99 and max indicates how heavy the tail is. For OpenRouter-routed models, the tail also includes upstream provider load.
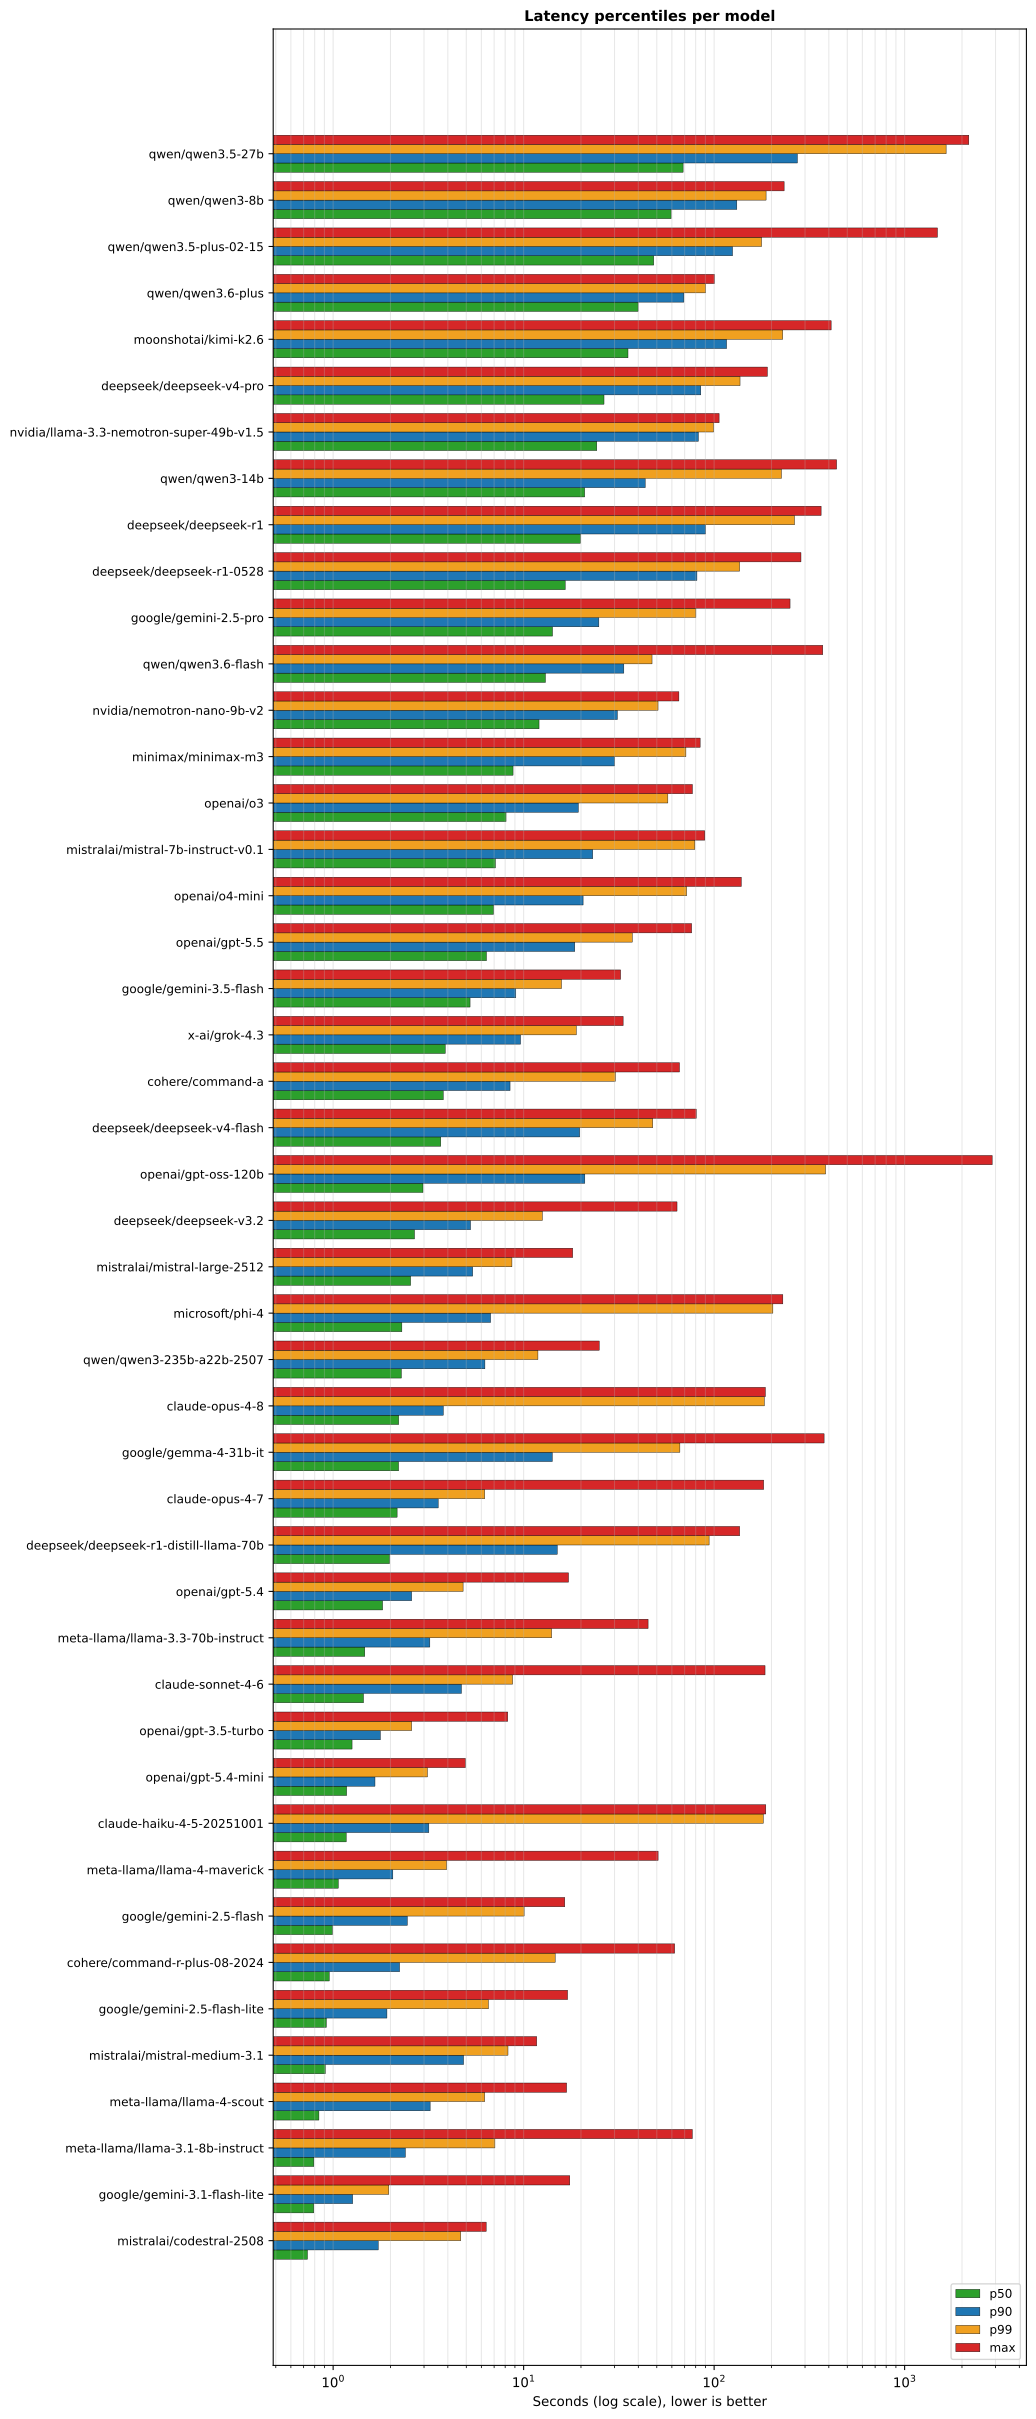
Source data: Latency tail table
Cross-model agreement (window distribution)
Section titled “Cross-model agreement (window distribution)”Histogram of how many models flagged at least one ad per (episode, window). The left side is windows nobody flagged (clear non-ad content), the right side is windows everyone flagged (clear sponsor reads). Bars in the middle are contested (some models said yes, some said no) and are candidates for ensemble voting or manual review. This view is anonymous (bars don’t show which models contributed); the per-model breakdown is in the next chart.
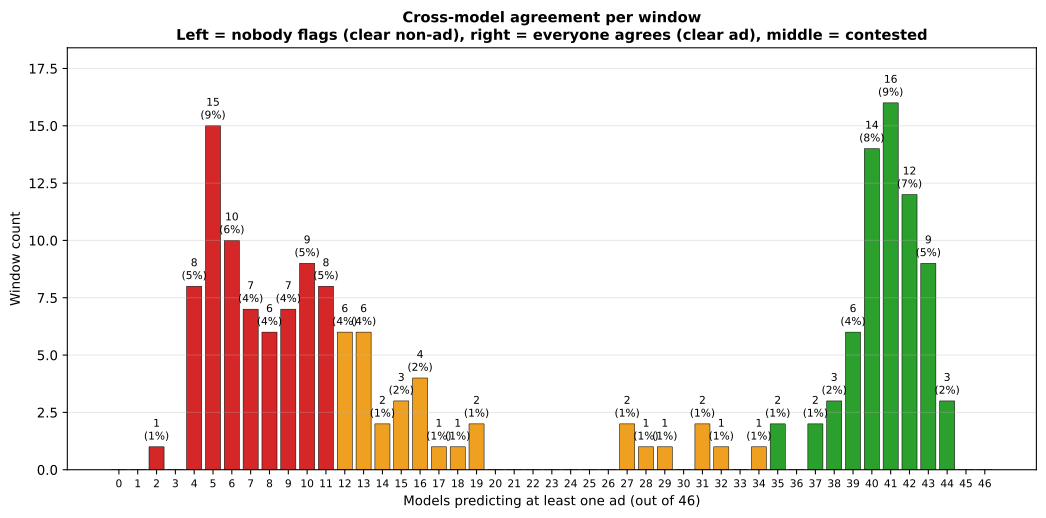
Source data: Cross-model agreement table
Per-model alignment with majority
Section titled “Per-model alignment with majority”Stacked horizontal bar per model. Green + blue segments are windows where the model voted with the majority (true positives + true negatives); orange is windows where it voted yes but most others voted no (likely false positive / hallucination); red is windows where it voted no but most others voted yes (likely missed real ad). Right-edge label is alignment rate. High alignment means the model tracks consensus; low alignment is either insight or noise depending on whether those broken-from-consensus calls were right.
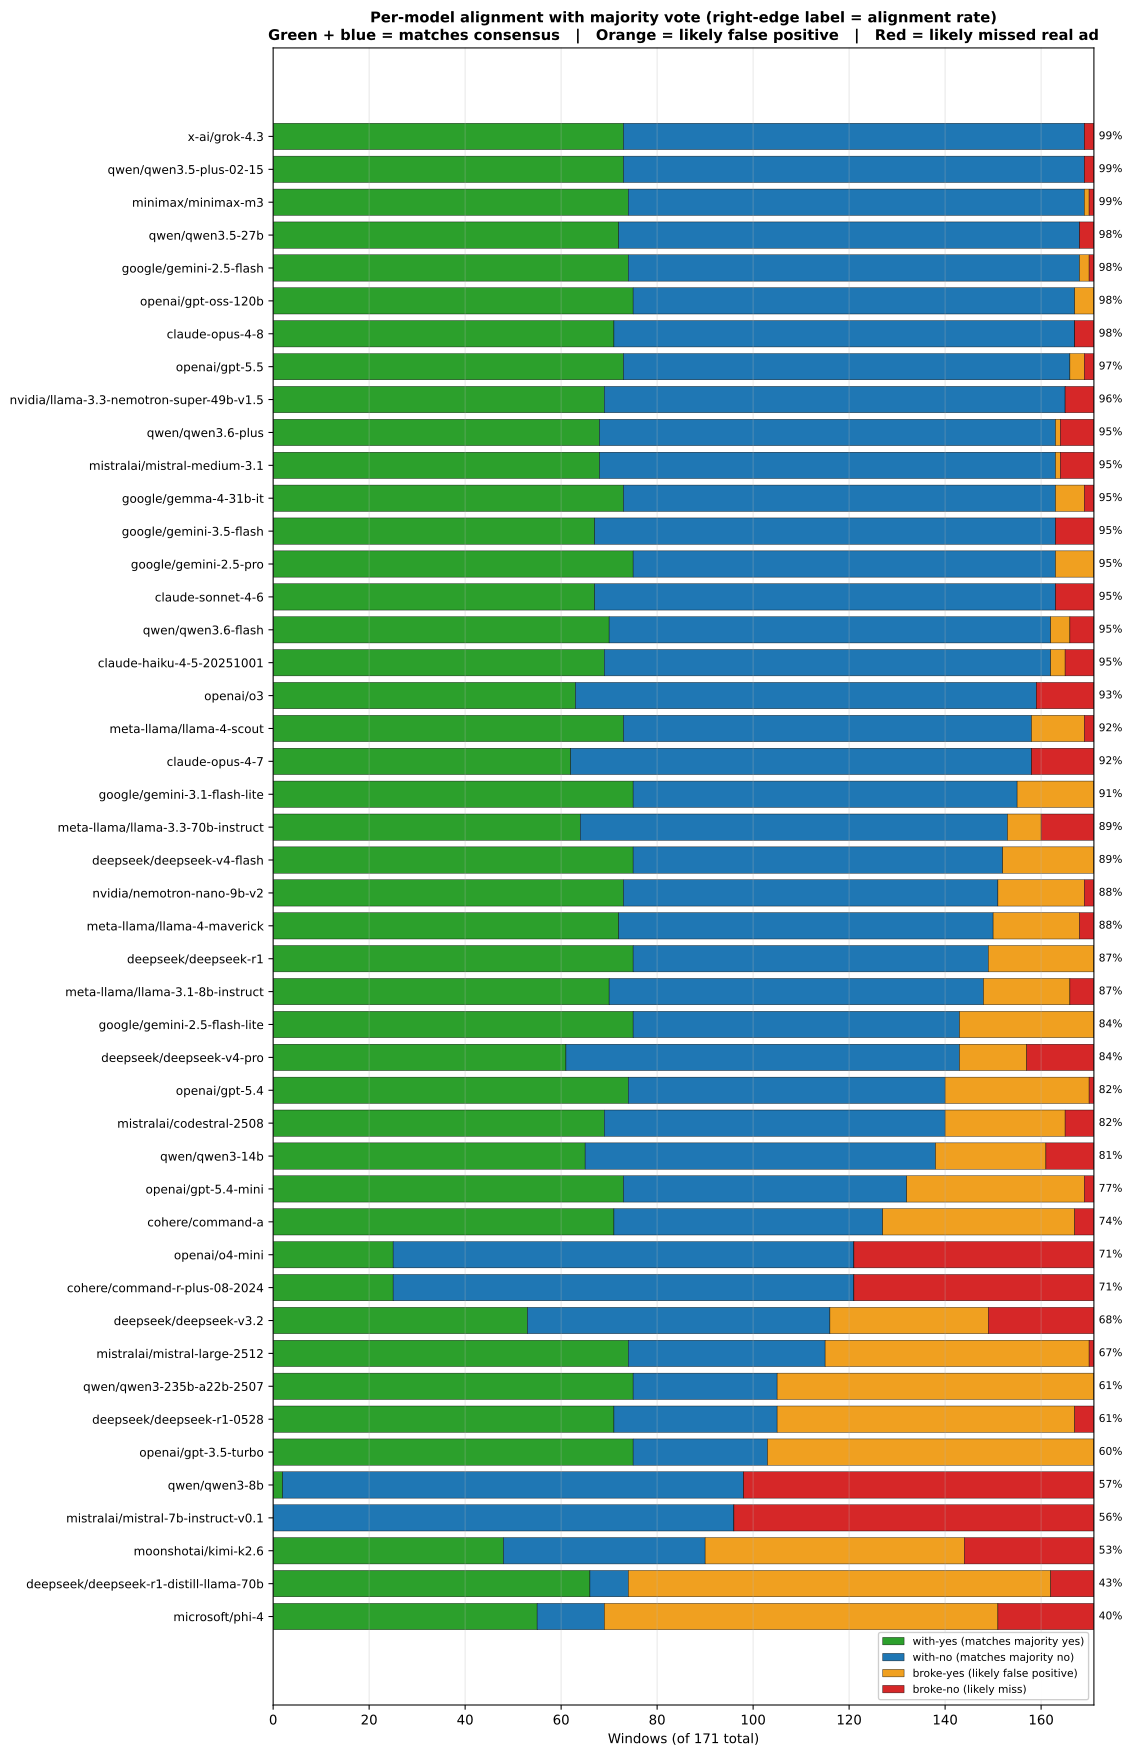
Source data: Per-model alignment with consensus table
Precision vs Recall (with F1 isocurves)
Section titled “Precision vs Recall (with F1 isocurves)”Scatter of precision (y) vs recall (x) for each model. Dashed gray lines are F1 isocurves; points on the same dashed line have the same F1. Top-right is ideal (high precision AND high recall). Top-left is cautious (high precision, low recall). Bottom-right is greedy (high recall, low precision). Useful for picking a model whose error profile matches your tolerance: precision-leaning for environments where false positives are expensive, recall-leaning for completeness-first.
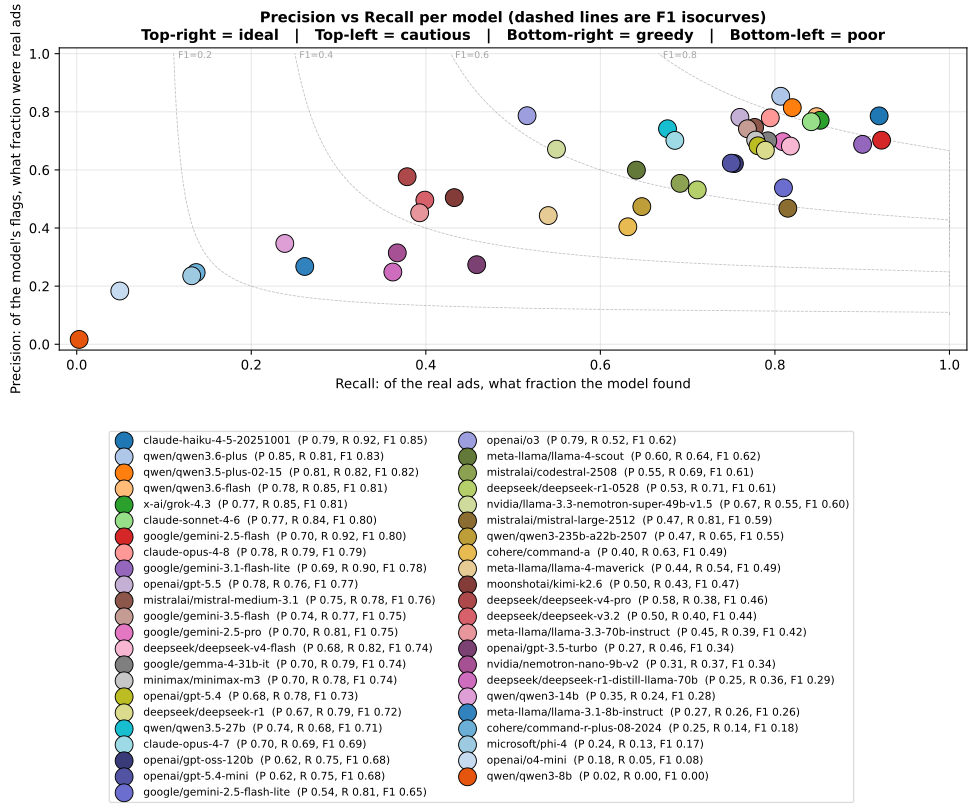
Source data: Precision, recall, and FP/FN breakdown table
Boundary accuracy (start + end MAE)
Section titled “Boundary accuracy (start + end MAE)”Stacked horizontal bars per model: blue is mean absolute error on the predicted ad START in seconds, orange is the same for END. Total error labeled at the right. Sorted by total ascending so the cleanest boundaries are at the top. Skewed bars (start much larger than end, or vice versa) mean the model systematically overshoots on one side. Relevant if you cut audio downstream.
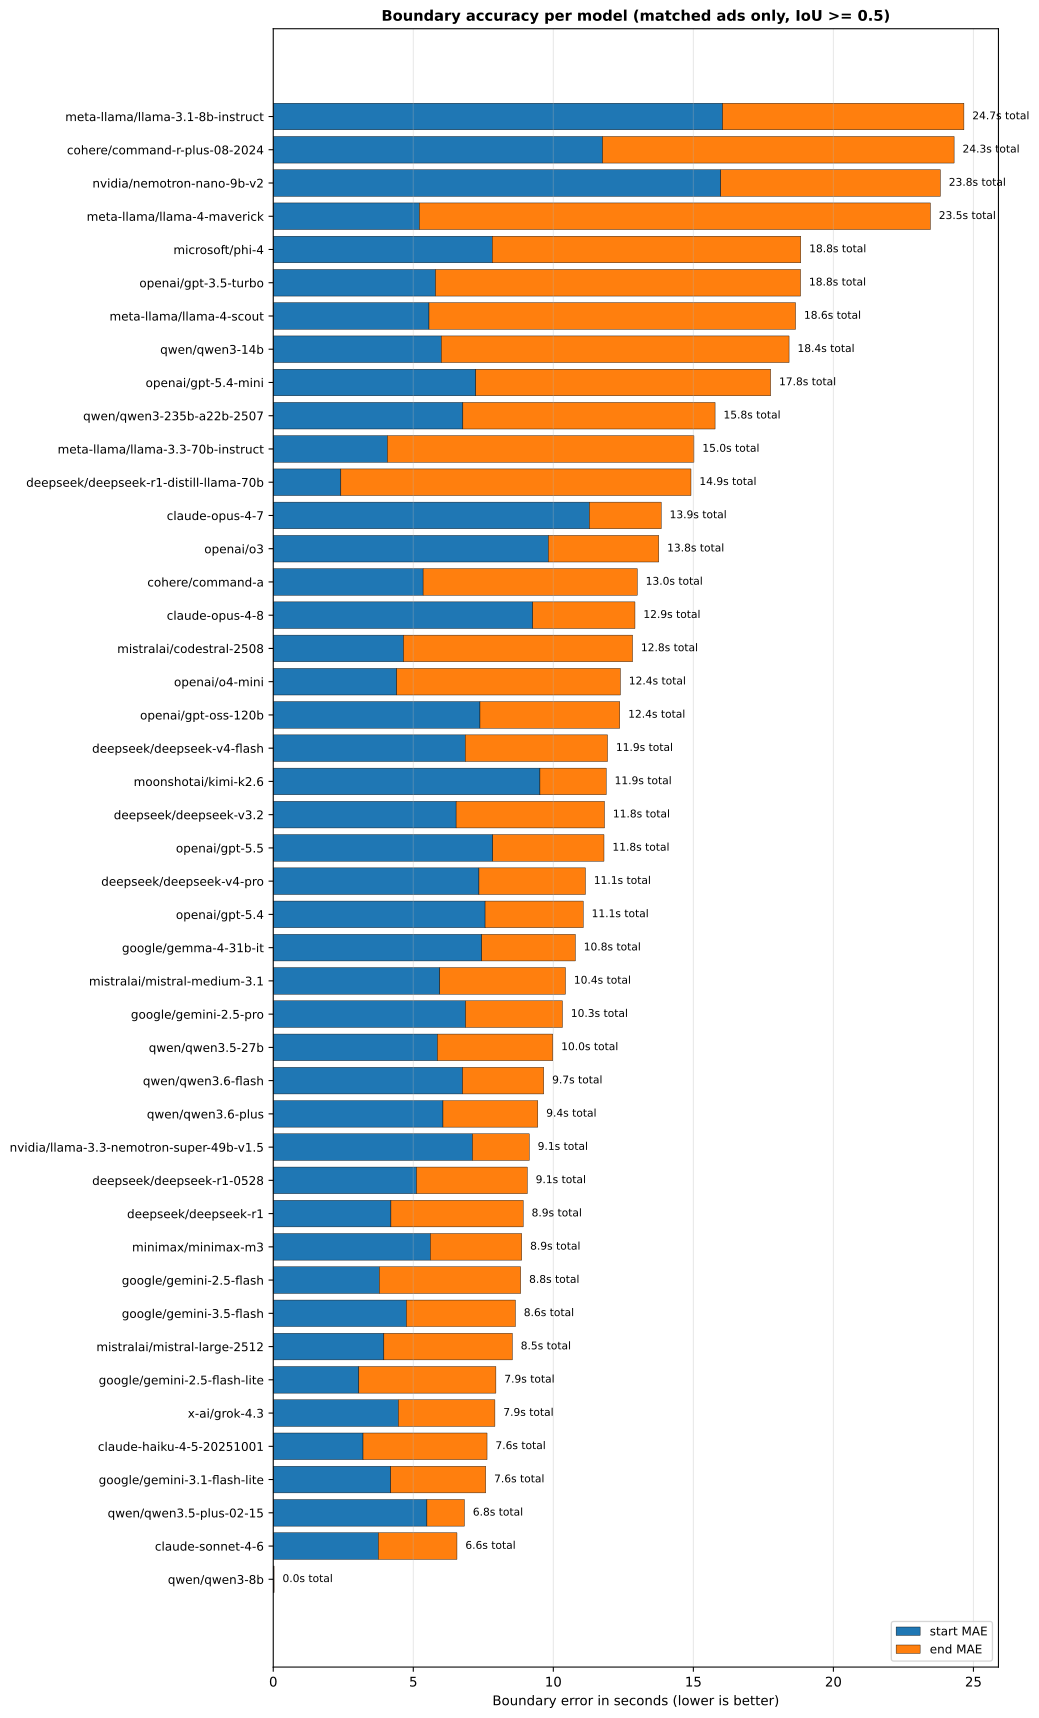
Source data: Boundary accuracy table
Token efficiency vs F1
Section titled “Token efficiency vs F1”Scatter of output tokens per detected ad (x, log scale) vs F1 (y). Upper-left is the efficient zone: high accuracy with few output tokens. Right-side points are reasoning-heavy models that emit chain-of-thought alongside their JSON. The chart answers whether the extra tokens buy more F1 or just burn output budget. A model that lands far right at modest F1 is paying for reasoning that didn’t help.
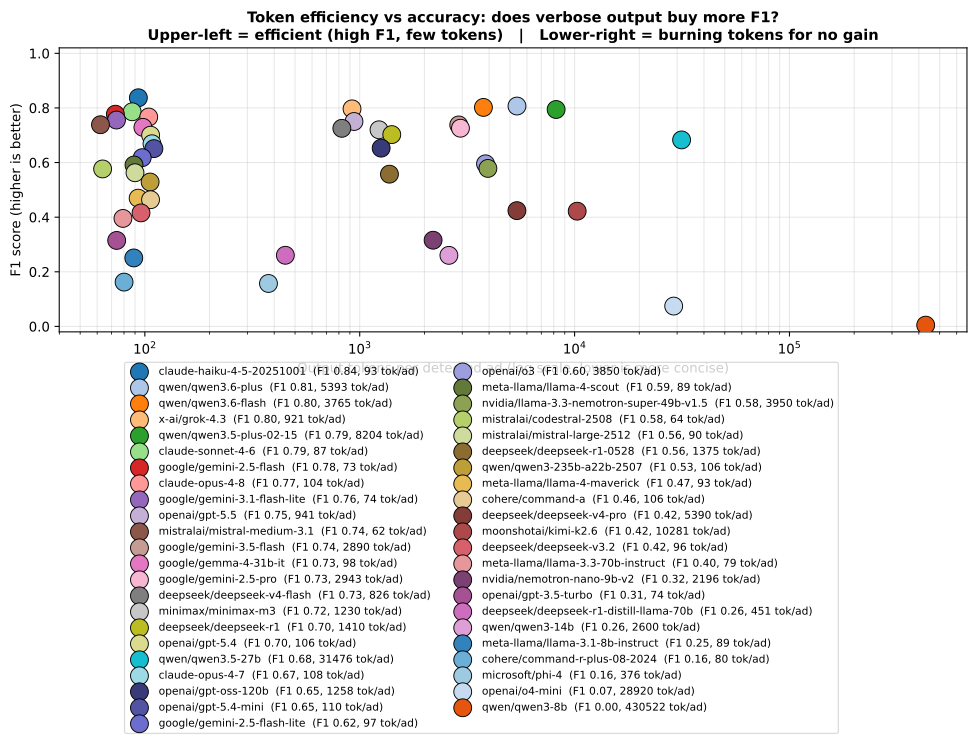
Source data: Output token efficiency table
Trial variance (determinism check)
Section titled “Trial variance (determinism check)”Horizontal bars of mean F1 stdev across episodes per model. All trials run at temperature 0.0 so well-behaved models cluster near zero. Bars are color-graded: green below 0.02 (effectively deterministic), yellow 0.02-0.05 (slight noise), red above 0.05 (single-trial F1 numbers from this model should be treated with suspicion). Dotted reference lines mark the 0.02 and 0.05 thresholds.
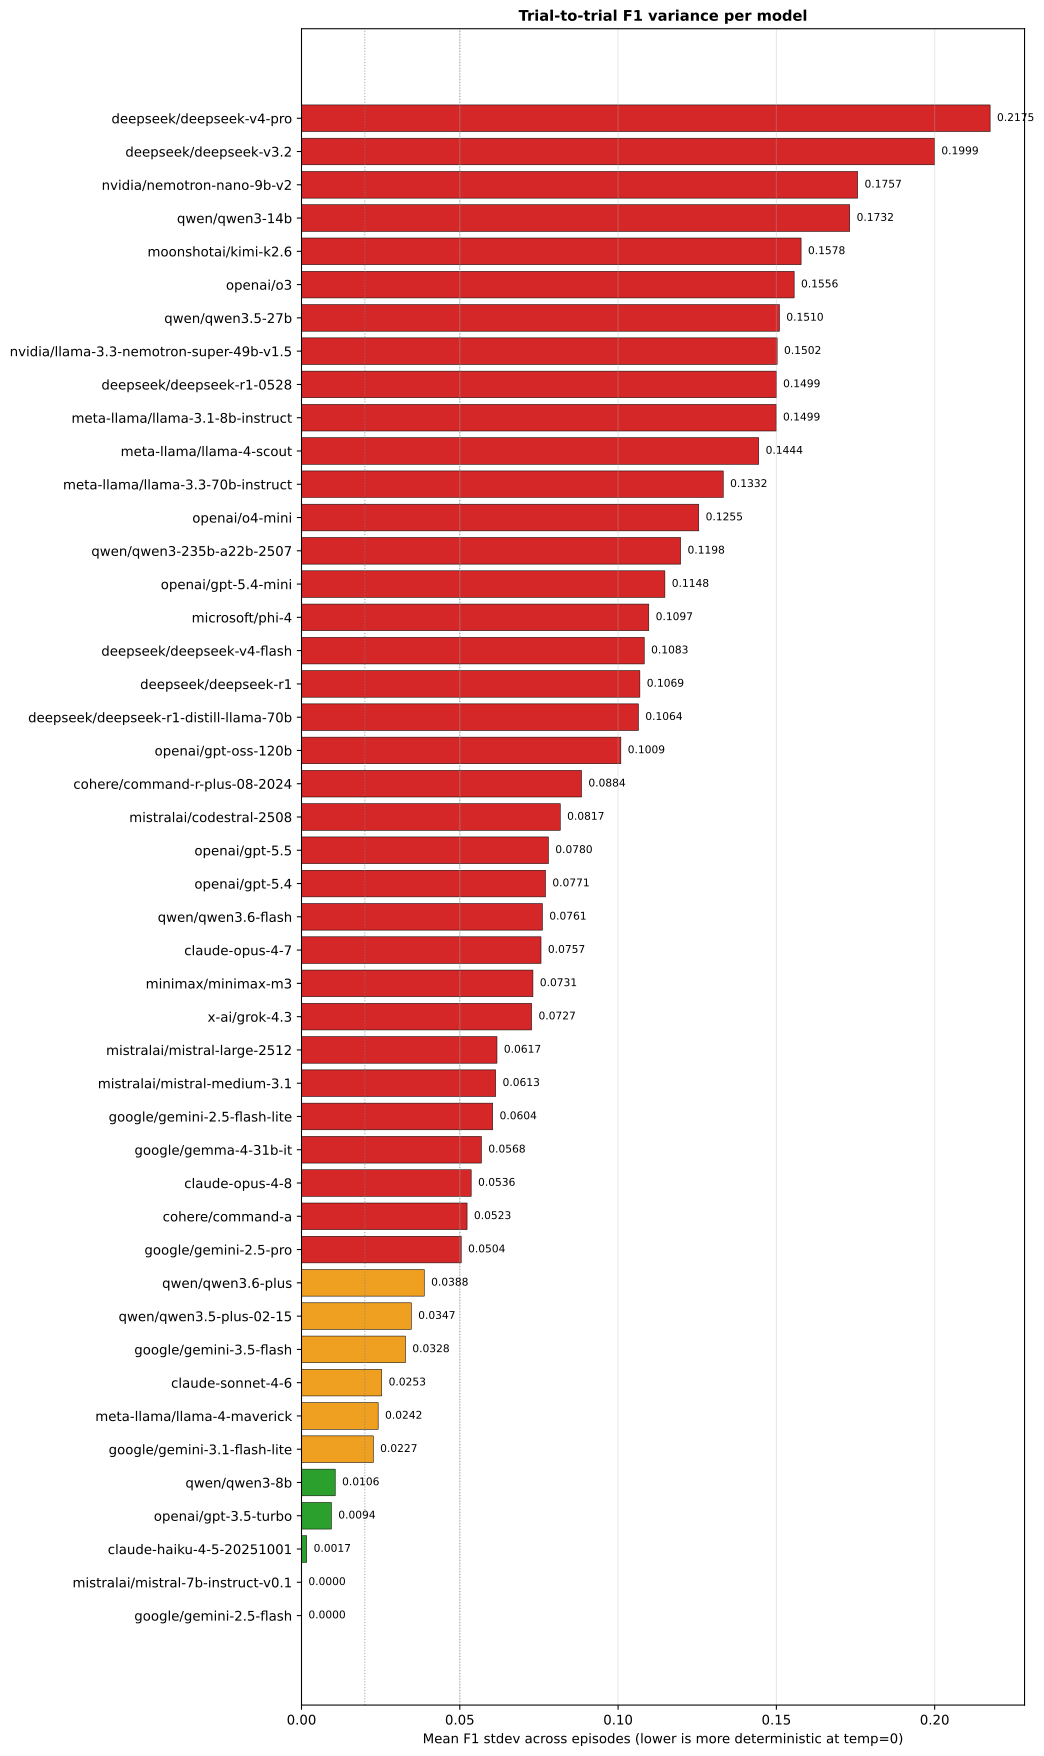
Source data: Trial variance (determinism check) table
Detection rate by ad length
Section titled “Detection rate by ad length”Heatmap of model (row) vs ad-length bucket (column), cell = detection rate with sample size. Greener = caught more ads in that bucket; redder = missed more. Models are sorted by overall detection rate so the strongest are at the top. Empty (gray) cells mean that bucket had no truth ads for the corresponding model’s trials.
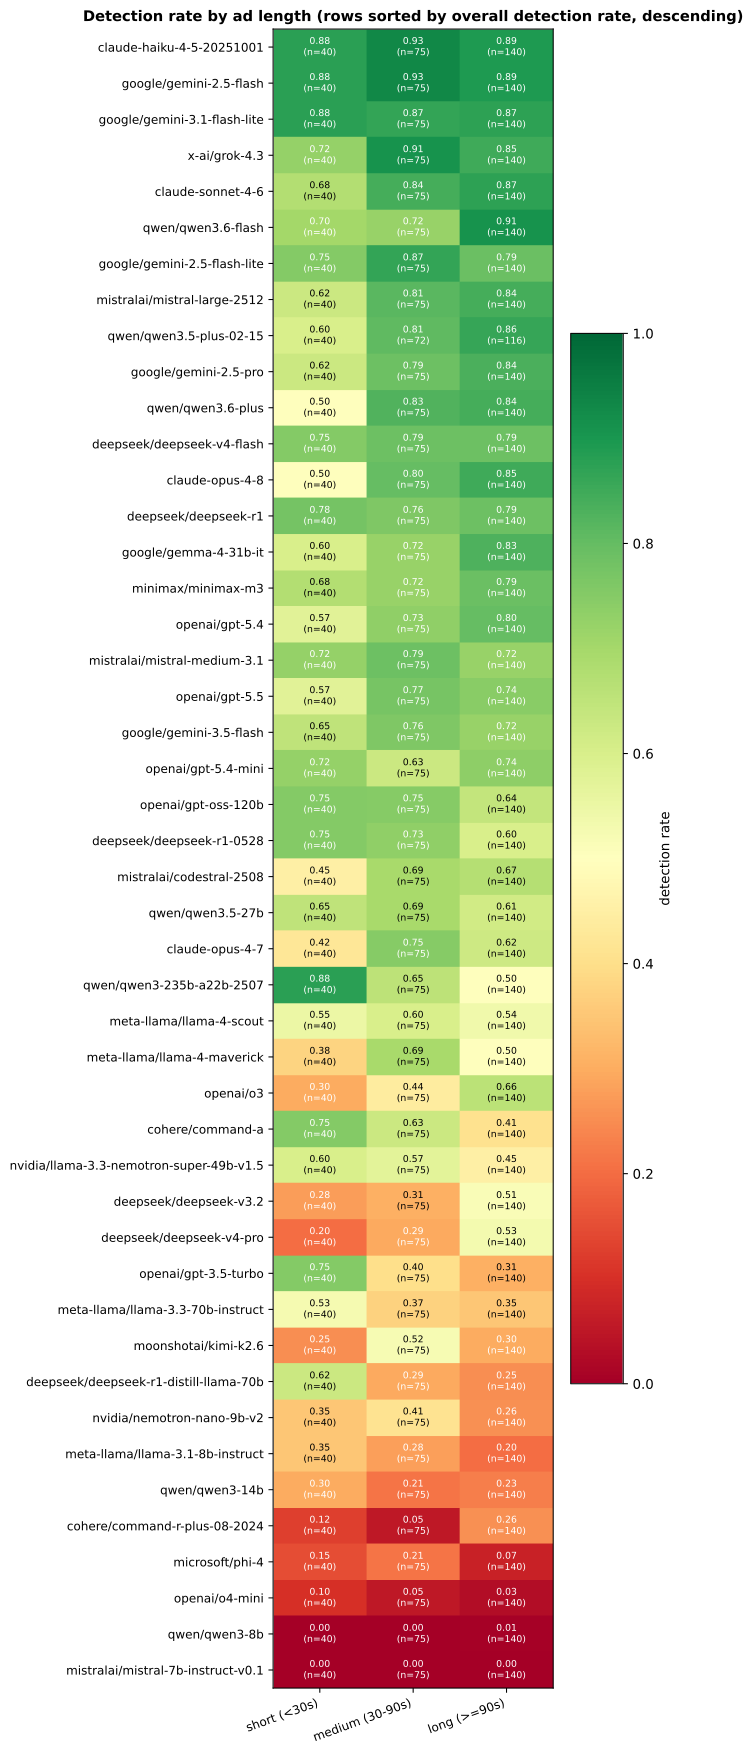
Source data: Detection rate by ad characteristic > By ad length table
Detection rate by ad position
Section titled “Detection rate by ad position”Same shape as the ad-length heatmap, but columns are episode position (pre-roll / mid-roll / post-roll). A common pattern: pre-roll is easy because of clear show-intro transitions; post-roll is harder because models near the end of long episodes often produce shorter responses or run out of context to anchor on.
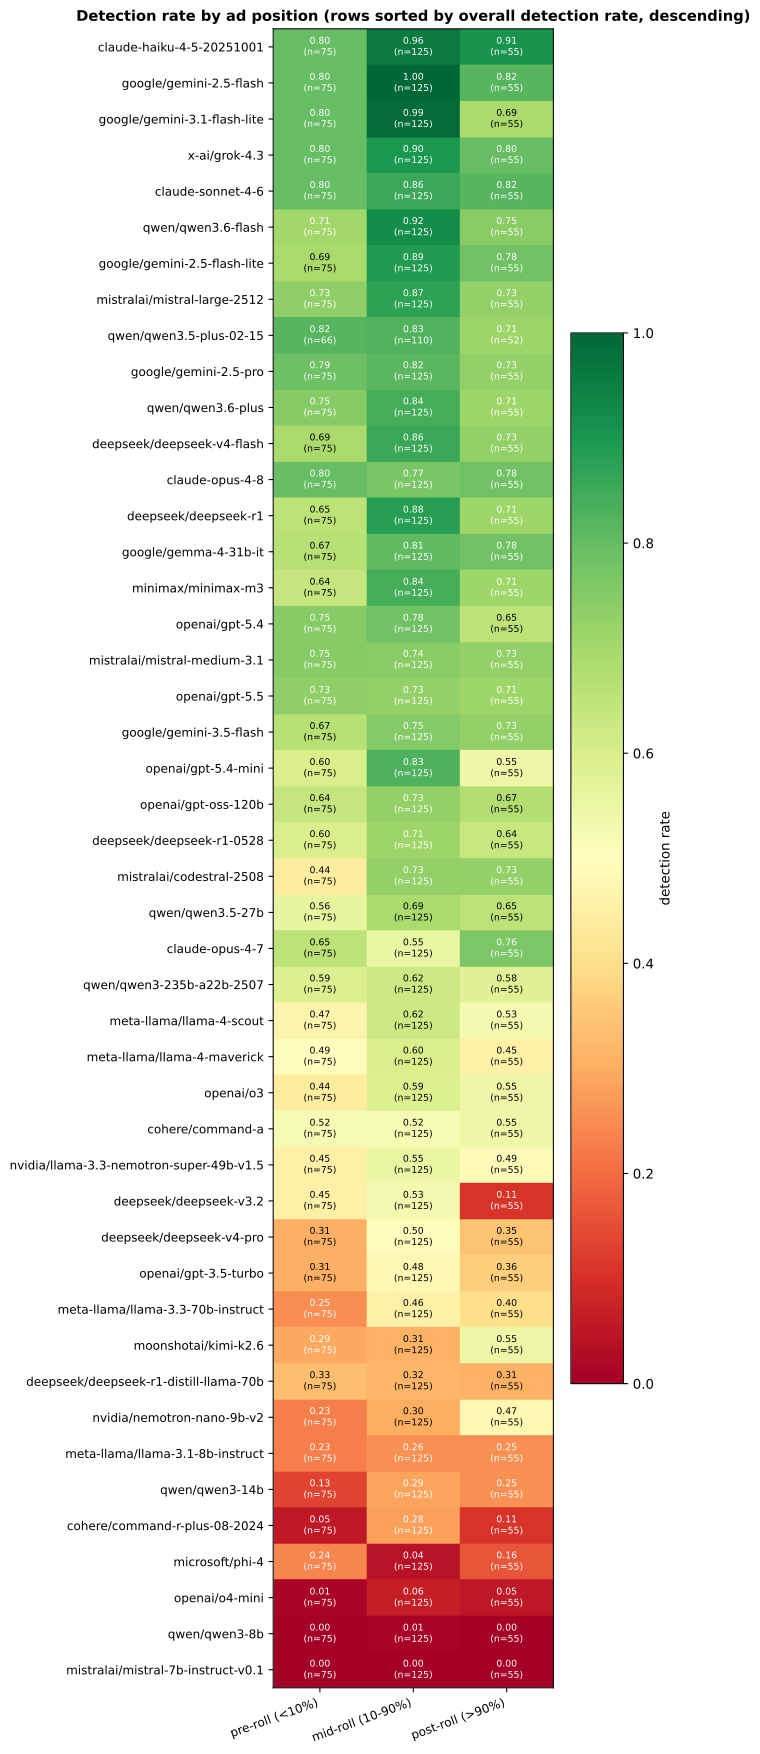
Source data: Detection rate by ad characteristic > By ad position table
Parser stress (extraction-method usage)
Section titled “Parser stress (extraction-method usage)”Heatmap of model (row) vs extraction-method (column), cell = number of responses parsed via that method. Columns are ordered by total usage. json_array_direct is the clean path; everything else is a recovery path the parser had to take because the model added markdown fences, wrapped the array in an object, or returned malformed JSON. Models near the top of the chart use the clean path most often. They are operationally easier to consume.
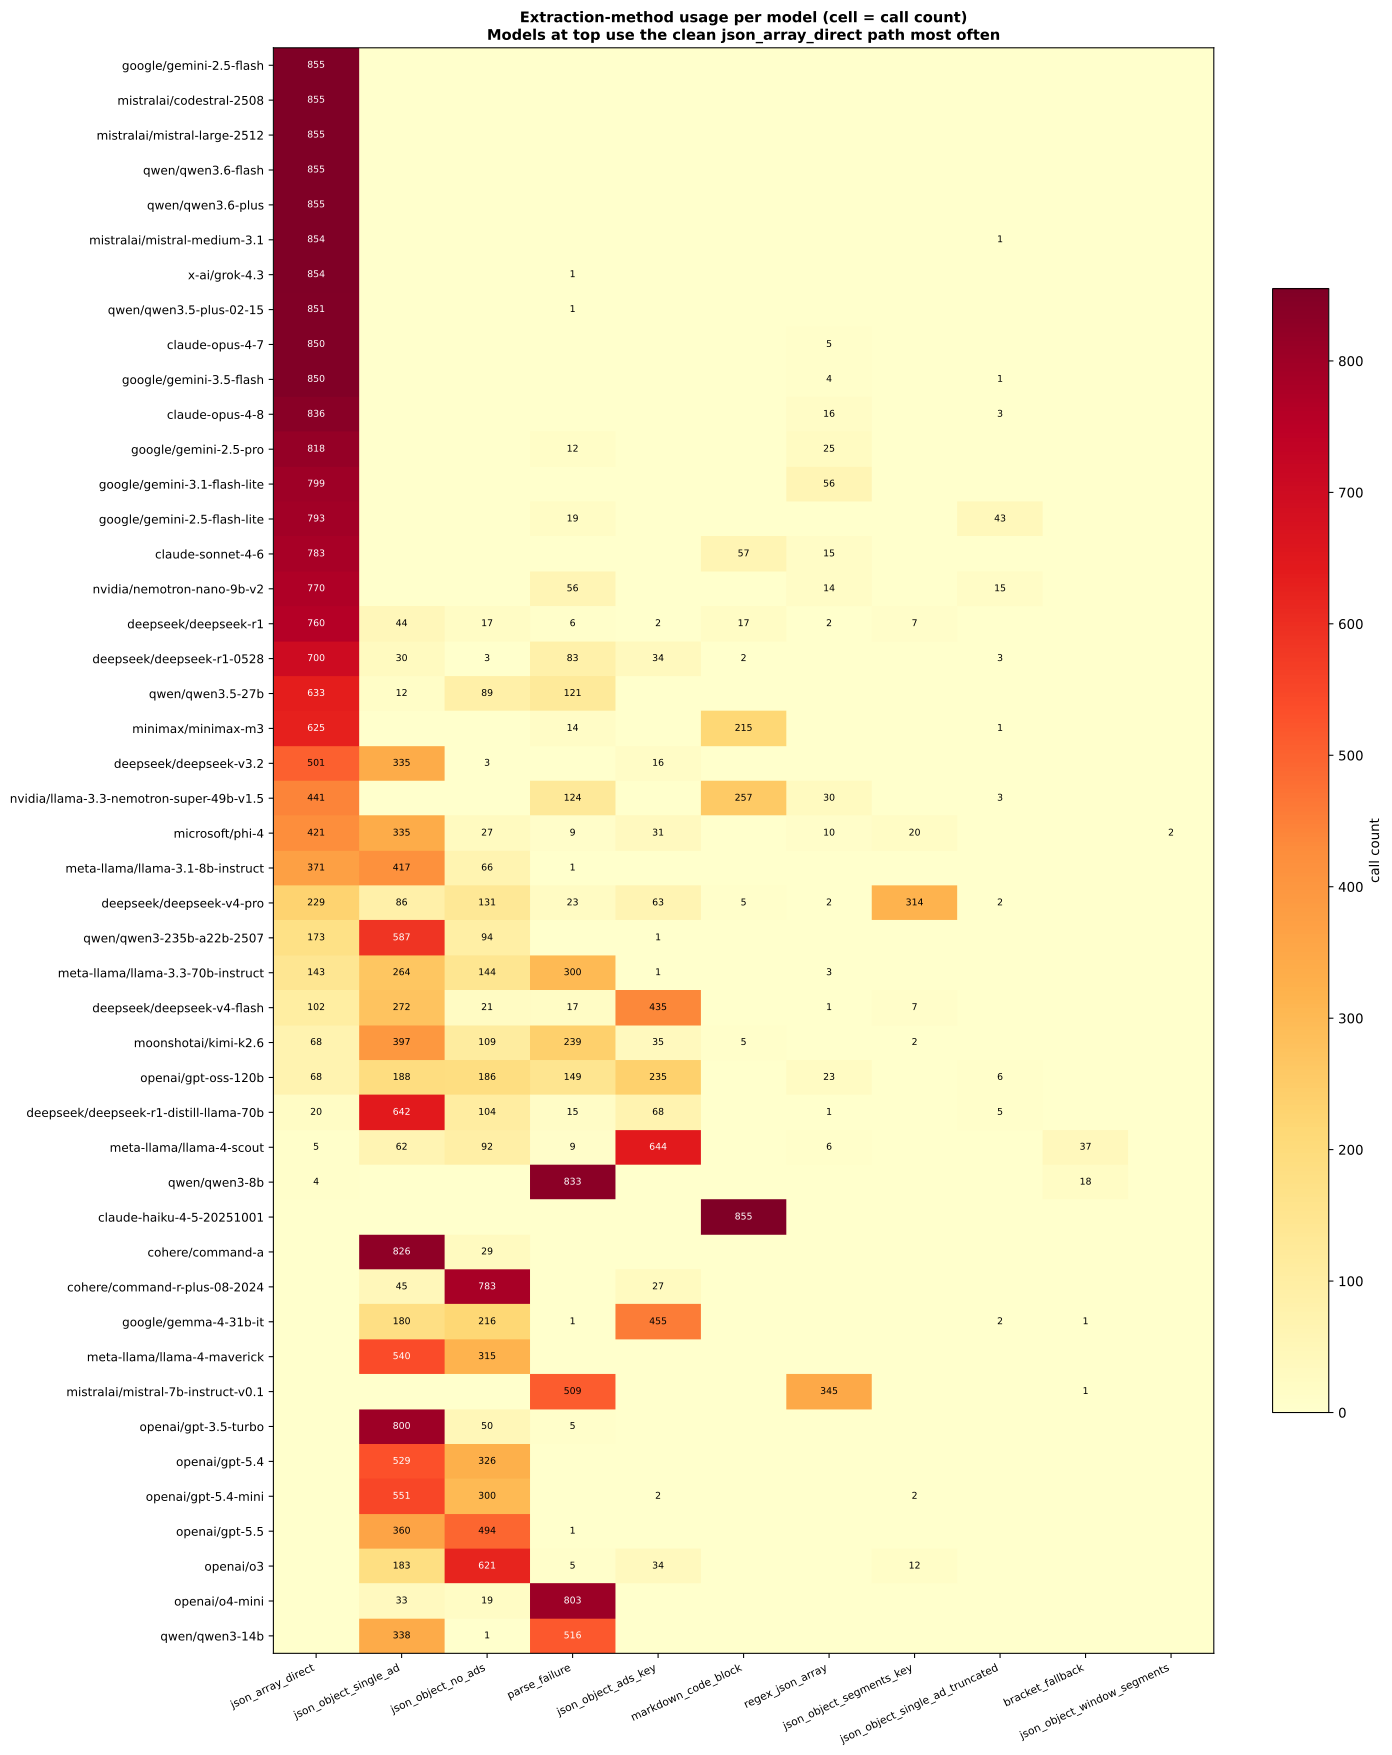
Source data: Parser stress test table
Failures and provider issues
Section titled “Failures and provider issues”3 call(s) failed out of 39330 total (0.01%). Failures are excluded from F1 / cost calculations, but they often surface real production-relevant gotchas worth knowing.
By category
Section titled “By category”Errors classified into coarse buckets so failure patterns are visible at a glance. A model showing up here doesn’t mean it’s broken. Some categories are provider-side (content moderation, rate limits) and tell you more about routing reliability than model quality.
| Category | Calls | Affected models |
|---|---|---|
| Provider content moderation rejection | 3 | qwen/qwen3.5-plus-02-15 |
Per-model error count
Section titled “Per-model error count”Same errors grouped by model, with the failure rate as a fraction of that model’s total calls. Rates under 1% are usually one-off provider hiccups; rates above 5% suggest the model isn’t operationally viable for production with the current prompts and concurrency caps.
| Model | Errors | of total |
|---|---|---|
qwen/qwen3.5-plus-02-15 |
3 | 3/855 (0.4%) |
Sample messages (first 3 per category)
Section titled “Sample messages (first 3 per category)”First three raw error messages per category, so you can see what the provider actually returned without grepping calls.jsonl. Messages are truncated to ~240 characters; full text lives in results/raw/calls.jsonl.
Provider content moderation rejection (3)
qwen/qwen3.5-plus-02-15onep-drink-champs-30c9a2d49f13(trial 0, window 15): Error code: 400 - {‘error’: {‘message’: ‘Provider returned error’, ‘code’: 400, ‘metadata’: {‘raw’: ’{“error”:{“message”:“<400> InternalError.Algo.DataInspectionFailed: Input text data may contain inappropriate content.”,“type”:“data_inspec…qwen/qwen3.5-plus-02-15onep-drink-champs-30c9a2d49f13(trial 1, window 15): Error code: 400 - {‘error’: {‘message’: ‘Provider returned error’, ‘code’: 400, ‘metadata’: {‘raw’: ’{“error”:{“message”:“<400> InternalError.Algo.DataInspectionFailed: Input text data may contain inappropriate content.”,“type”:“data_inspec…qwen/qwen3.5-plus-02-15onep-drink-champs-30c9a2d49f13(trial 3, window 15): Error code: 400 - {‘error’: {‘message’: ‘Provider returned error’, ‘code’: 400, ‘metadata’: {‘raw’: ’{“error”:{“message”:“<400> InternalError.Algo.DataInspectionFailed: Input text data may contain inappropriate content.”,“type”:“data_inspec…
Why this section exists
Section titled “Why this section exists”If you’re picking a model for production, an aggregate compliance score doesn’t tell you when the provider will simply refuse to answer. A few cases that have shown up here:
- Content moderation rejections (Alibaba on Qwen, Google on Gemma, sometimes others): the provider’s classifier blocks the prompt before the model runs. For ad detection on real podcast transcripts, this can happen on episodes with adult content, profanity, or politically sensitive topics. Rate is small but non-zero; plan for it.
- Deprecated parameters: the Claude 4.x family rejects
temperature. The benchmark memoizes this per-process and retries without, but it tells you which models you cannot pass legacy sampling controls to. - Rate limits: tail-latency or 429s under load. Not a model-quality issue, but determines whether a given provider is operationally viable for your throughput.
Precision, recall, and FP/FN breakdown
Section titled “Precision, recall, and FP/FN breakdown”F1 collapses two failure modes into one number. A precision-leaning model misses ads but rarely flags non-ads; a recall-leaning model catches everything at the cost of false positives. Production tradeoffs hinge on which one you can tolerate.
Column key
Section titled “Column key”| Column | Meaning | Range |
|---|---|---|
| TP (true positive) | Predicted an ad and a real ad existed at that span (IoU >= 0.5) | 0 to total truth ads |
| FP (false positive) | Predicted an ad where no real ad existed | 0 to total predictions |
| FN (false negative) | Missed a real ad entirely (no prediction matched it at IoU >= 0.5) | 0 to total truth ads |
| Precision | TP / (TP + FP). Of the ads the model claimed, how many were real? Higher means fewer false positives. |
0.000 to 1.000 |
| Recall | TP / (TP + FN). Of the real ads, how many did the model find? Higher means fewer misses. |
0.000 to 1.000 |
Reading the table: high precision + low recall means the model is cautious. It rarely flags something that isn’t an ad, but misses real ads. High recall + low precision means the opposite: catches everything but invents false positives. F1 is the harmonic mean of the two and rewards models that do both well.
| Model | Precision | Recall | TP | FP | FN |
|---|---|---|---|---|---|
claude-haiku-4-5-20251001 |
0.786 | 0.919 | 230 | 68 | 25 |
qwen/qwen3.6-plus |
0.853 | 0.807 | 200 | 42 | 55 |
qwen/qwen3.6-flash |
0.783 | 0.848 | 209 | 62 | 46 |
x-ai/grok-4.3 |
0.771 | 0.852 | 216 | 60 | 39 |
qwen/qwen3.5-plus-02-15 |
0.814 | 0.820 | 182 | 44 | 46 |
claude-sonnet-4-6 |
0.766 | 0.842 | 212 | 70 | 43 |
google/gemini-2.5-flash |
0.702 | 0.922 | 230 | 110 | 25 |
claude-opus-4-8 |
0.779 | 0.795 | 199 | 52 | 56 |
google/gemini-3.1-flash-lite |
0.688 | 0.900 | 222 | 128 | 33 |
openai/gpt-5.5 |
0.781 | 0.760 | 185 | 48 | 70 |
mistralai/mistral-medium-3.1 |
0.746 | 0.777 | 189 | 91 | 66 |
google/gemini-3.5-flash |
0.742 | 0.769 | 184 | 75 | 71 |
google/gemma-4-31b-it |
0.700 | 0.792 | 194 | 89 | 61 |
google/gemini-2.5-pro |
0.697 | 0.809 | 201 | 91 | 54 |
deepseek/deepseek-v4-flash |
0.682 | 0.818 | 199 | 109 | 56 |
minimax/minimax-m3 |
0.703 | 0.778 | 192 | 90 | 63 |
deepseek/deepseek-r1 |
0.668 | 0.789 | 198 | 111 | 57 |
openai/gpt-5.4 |
0.683 | 0.781 | 190 | 104 | 65 |
qwen/qwen3.5-27b |
0.742 | 0.677 | 164 | 67 | 91 |
claude-opus-4-7 |
0.702 | 0.685 | 160 | 65 | 95 |
openai/gpt-oss-120b |
0.622 | 0.754 | 176 | 151 | 79 |
openai/gpt-5.4-mini |
0.623 | 0.750 | 179 | 140 | 76 |
google/gemini-2.5-flash-lite |
0.538 | 0.810 | 206 | 220 | 49 |
openai/o3 |
0.787 | 0.516 | 137 | 23 | 118 |
meta-llama/llama-4-scout |
0.599 | 0.641 | 142 | 135 | 113 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.671 | 0.550 | 130 | 79 | 125 |
mistralai/codestral-2508 |
0.554 | 0.691 | 164 | 194 | 91 |
mistralai/mistral-large-2512 |
0.468 | 0.815 | 204 | 351 | 51 |
deepseek/deepseek-r1-0528 |
0.531 | 0.711 | 169 | 278 | 86 |
qwen/qwen3-235b-a22b-2507 |
0.474 | 0.648 | 154 | 214 | 101 |
meta-llama/llama-4-maverick |
0.443 | 0.540 | 137 | 164 | 118 |
cohere/command-a |
0.404 | 0.631 | 134 | 267 | 121 |
deepseek/deepseek-v4-pro |
0.577 | 0.379 | 104 | 50 | 151 |
moonshotai/kimi-k2.6 |
0.505 | 0.433 | 91 | 102 | 164 |
deepseek/deepseek-v3.2 |
0.496 | 0.399 | 106 | 135 | 149 |
meta-llama/llama-3.3-70b-instruct |
0.452 | 0.393 | 98 | 88 | 157 |
nvidia/nemotron-nano-9b-v2 |
0.315 | 0.367 | 81 | 290 | 174 |
openai/gpt-3.5-turbo |
0.274 | 0.458 | 103 | 423 | 152 |
deepseek/deepseek-r1-distill-llama-70b |
0.249 | 0.362 | 82 | 372 | 173 |
qwen/qwen3-14b |
0.347 | 0.238 | 60 | 114 | 195 |
meta-llama/llama-3.1-8b-instruct |
0.268 | 0.261 | 63 | 259 | 192 |
cohere/command-r-plus-08-2024 |
0.247 | 0.137 | 45 | 28 | 210 |
microsoft/phi-4 |
0.236 | 0.132 | 32 | 147 | 223 |
openai/o4-mini |
0.183 | 0.049 | 12 | 17 | 243 |
qwen/qwen3-8b |
0.017 | 0.003 | 1 | 3 | 254 |
mistralai/mistral-7b-instruct-v0.1 |
0.000 | 0.000 | 0 | 0 | 255 |
Boundary accuracy
Section titled “Boundary accuracy”For ads that match the truth at IoU >= 0.5, how far off were the predicted start and end timestamps? Lower is better. A model can hit F1 cleanly while still being 20s off on every boundary. Bad for any pipeline that cuts the audio.
| Model | Start MAE (s) | End MAE (s) |
|---|---|---|
qwen/qwen3-8b |
0.02 | 0.01 |
claude-sonnet-4-6 |
3.75 | 2.81 |
qwen/qwen3.5-plus-02-15 |
5.49 | 1.34 |
google/gemini-3.1-flash-lite |
4.20 | 3.39 |
claude-haiku-4-5-20251001 |
3.21 | 4.43 |
x-ai/grok-4.3 |
4.47 | 3.45 |
google/gemini-2.5-flash-lite |
3.06 | 4.89 |
mistralai/mistral-large-2512 |
3.95 | 4.59 |
google/gemini-3.5-flash |
4.75 | 3.89 |
google/gemini-2.5-flash |
3.78 | 5.05 |
minimax/minimax-m3 |
5.61 | 3.26 |
deepseek/deepseek-r1 |
4.20 | 4.72 |
deepseek/deepseek-r1-0528 |
5.11 | 3.96 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
7.11 | 2.03 |
qwen/qwen3.6-plus |
6.06 | 3.39 |
qwen/qwen3.6-flash |
6.76 | 2.90 |
qwen/qwen3.5-27b |
5.86 | 4.12 |
google/gemini-2.5-pro |
6.87 | 3.46 |
mistralai/mistral-medium-3.1 |
5.95 | 4.49 |
google/gemma-4-31b-it |
7.45 | 3.34 |
openai/gpt-5.4 |
7.56 | 3.50 |
deepseek/deepseek-v4-pro |
7.34 | 3.80 |
openai/gpt-5.5 |
7.84 | 3.97 |
deepseek/deepseek-v3.2 |
6.53 | 5.30 |
moonshotai/kimi-k2.6 |
9.52 | 2.37 |
deepseek/deepseek-v4-flash |
6.85 | 5.08 |
openai/gpt-oss-120b |
7.38 | 4.99 |
openai/o4-mini |
4.41 | 7.99 |
mistralai/codestral-2508 |
4.65 | 8.18 |
claude-opus-4-8 |
9.27 | 3.65 |
cohere/command-a |
5.35 | 7.65 |
openai/o3 |
9.82 | 3.94 |
claude-opus-4-7 |
11.28 | 2.57 |
deepseek/deepseek-r1-distill-llama-70b |
2.41 | 12.50 |
meta-llama/llama-3.3-70b-instruct |
4.07 | 10.95 |
qwen/qwen3-235b-a22b-2507 |
6.77 | 9.01 |
openai/gpt-5.4-mini |
7.23 | 10.53 |
qwen/qwen3-14b |
6.00 | 12.42 |
meta-llama/llama-4-scout |
5.56 | 13.09 |
openai/gpt-3.5-turbo |
5.79 | 13.03 |
microsoft/phi-4 |
7.82 | 11.02 |
meta-llama/llama-4-maverick |
5.22 | 18.25 |
nvidia/nemotron-nano-9b-v2 |
15.98 | 7.84 |
cohere/command-r-plus-08-2024 |
11.76 | 12.55 |
meta-llama/llama-3.1-8b-instruct |
16.04 | 8.62 |
Confidence calibration
Section titled “Confidence calibration”Models include a self-reported confidence on each detected ad. A well-calibrated model should be right ~95% of the time when it claims 0.95 confidence. The table below bins each model’s predictions and shows the actual hit rate (fraction that were true positives at IoU >= 0.5). A bin near 1.0 is well-calibrated; a low number with a high count means the model is overconfident.
| Model | 0.00-0.70 | 0.70-0.90 | 0.90-0.95 | 0.95-0.99 | 0.99+ | total |
|---|---|---|---|---|---|---|
claude-haiku-4-5-20251001 |
– | 0.00 (n=5) | 0.52 (n=58) | 0.85 (n=235) | – | 298 |
claude-opus-4-7 |
– | 0.00 (n=6) | 0.29 (n=7) | 0.72 (n=189) | 0.91 (n=23) | 225 |
claude-opus-4-8 |
0.00 (n=1) | 0.00 (n=19) | 0.12 (n=8) | 0.89 (n=223) | – | 251 |
claude-sonnet-4-6 |
– | 0.11 (n=18) | 0.71 (n=21) | 0.83 (n=205) | 0.66 (n=38) | 282 |
cohere/command-a |
0.00 (n=2) | 0.00 (n=28) | – | 0.35 (n=382) | 0.00 (n=1) | 413 |
cohere/command-r-plus-08-2024 |
– | – | 0.00 (n=1) | 0.53 (n=19) | 0.66 (n=53) | 73 |
deepseek/deepseek-r1 |
– | 0.00 (n=2) | 0.17 (n=6) | 0.58 (n=217) | 0.79 (n=90) | 315 |
deepseek/deepseek-r1-0528 |
0.00 (n=1) | 0.00 (n=13) | 0.02 (n=43) | 0.20 (n=259) | 0.79 (n=147) | 463 |
deepseek/deepseek-r1-distill-llama-70b |
– | 0.02 (n=156) | – | 0.23 (n=351) | – | 507 |
deepseek/deepseek-v3.2 |
0.00 (n=1) | 0.00 (n=3) | 0.00 (n=8) | 0.17 (n=129) | 0.79 (n=106) | 247 |
deepseek/deepseek-v4-flash |
0.00 (n=7) | 0.25 (n=4) | 0.20 (n=5) | 0.58 (n=172) | 0.80 (n=121) | 309 |
deepseek/deepseek-v4-pro |
0.00 (n=1) | 0.00 (n=7) | 0.00 (n=4) | 0.73 (n=106) | 0.75 (n=36) | 154 |
google/gemini-2.5-flash |
– | – | 0.12 (n=40) | 0.77 (n=215) | 0.71 (n=85) | 340 |
google/gemini-2.5-flash-lite |
– | 1.00 (n=1) | – | 0.48 (n=421) | 0.56 (n=9) | 431 |
google/gemini-2.5-pro |
– | 0.00 (n=12) | 0.00 (n=18) | 0.53 (n=66) | 0.82 (n=202) | 298 |
google/gemini-3.1-flash-lite |
– | 0.00 (n=3) | 0.00 (n=24) | 0.24 (n=75) | 0.81 (n=253) | 355 |
google/gemini-3.5-flash |
– | 0.00 (n=3) | 0.25 (n=12) | 0.16 (n=31) | 0.83 (n=213) | 259 |
google/gemma-4-31b-it |
– | 0.14 (n=7) | 0.12 (n=24) | 0.58 (n=83) | 0.82 (n=174) | 288 |
meta-llama/llama-3.1-8b-instruct |
– | 0.00 (n=2) | 0.00 (n=1) | 0.20 (n=319) | – | 322 |
meta-llama/llama-3.3-70b-instruct |
– | 0.00 (n=17) | 0.50 (n=14) | 0.42 (n=60) | 0.69 (n=95) | 186 |
meta-llama/llama-4-maverick |
0.00 (n=1) | 0.00 (n=53) | 0.12 (n=41) | 0.63 (n=209) | 0.50 (n=2) | 306 |
meta-llama/llama-4-scout |
– | 0.00 (n=4) | 0.00 (n=5) | 0.52 (n=247) | 0.67 (n=21) | 277 |
microsoft/phi-4 |
– | 0.00 (n=5) | 0.00 (n=3) | 0.16 (n=206) | – | 214 |
minimax/minimax-m3 |
0.00 (n=13) | 0.04 (n=23) | 0.27 (n=11) | 0.80 (n=204) | 0.81 (n=31) | 282 |
mistralai/codestral-2508 |
– | 0.00 (n=1) | 0.00 (n=4) | 0.47 (n=352) | 0.00 (n=1) | 358 |
mistralai/mistral-large-2512 |
0.00 (n=2) | 0.00 (n=31) | 0.00 (n=49) | 0.07 (n=196) | 0.69 (n=277) | 555 |
mistralai/mistral-medium-3.1 |
– | 0.00 (n=1) | 0.00 (n=8) | 0.70 (n=250) | 0.71 (n=21) | 280 |
moonshotai/kimi-k2.6 |
0.00 (n=30) | 0.04 (n=27) | 0.00 (n=2) | 0.52 (n=83) | 0.75 (n=63) | 205 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
– | 0.00 (n=3) | 0.50 (n=4) | 0.64 (n=200) | 0.50 (n=2) | 209 |
nvidia/nemotron-nano-9b-v2 |
– | 0.00 (n=4) | 0.00 (n=15) | 0.22 (n=334) | 0.47 (n=19) | 372 |
openai/gpt-3.5-turbo |
– | – | 0.00 (n=5) | 0.24 (n=351) | 0.08 (n=226) | 582 |
openai/gpt-5.4 |
0.00 (n=19) | 0.08 (n=37) | 0.00 (n=20) | 0.59 (n=32) | 0.87 (n=194) | 302 |
openai/gpt-5.4-mini |
0.00 (n=12) | 0.02 (n=41) | 0.00 (n=29) | 0.52 (n=50) | 0.80 (n=191) | 323 |
openai/gpt-5.5 |
0.00 (n=7) | 0.19 (n=16) | 0.60 (n=5) | 0.82 (n=38) | 0.88 (n=168) | 234 |
openai/gpt-oss-120b |
– | 0.00 (n=4) | 0.10 (n=10) | 0.33 (n=128) | 0.70 (n=190) | 332 |
openai/o3 |
0.00 (n=1) | – | 0.36 (n=11) | 0.89 (n=139) | 1.00 (n=9) | 160 |
openai/o4-mini |
– | 0.00 (n=2) | – | 0.46 (n=26) | 0.00 (n=1) | 29 |
qwen/qwen3-14b |
– | – | 0.00 (n=29) | 0.41 (n=147) | – | 176 |
qwen/qwen3-235b-a22b-2507 |
0.00 (n=11) | 0.00 (n=5) | 0.00 (n=6) | 0.45 (n=310) | 0.26 (n=61) | 393 |
qwen/qwen3-8b |
– | – | – | 0.25 (n=4) | – | 4 |
qwen/qwen3.5-27b |
– | 0.00 (n=7) | 0.00 (n=5) | 0.76 (n=217) | 0.00 (n=2) | 231 |
qwen/qwen3.5-plus-02-15 |
– | 0.00 (n=6) | 0.14 (n=7) | 0.85 (n=196) | 0.82 (n=17) | 226 |
qwen/qwen3.6-flash |
0.00 (n=1) | 0.00 (n=4) | 0.00 (n=4) | 0.79 (n=258) | 0.83 (n=6) | 273 |
qwen/qwen3.6-plus |
0.00 (n=1) | 0.00 (n=4) | 0.00 (n=1) | 0.86 (n=230) | 0.33 (n=6) | 242 |
x-ai/grok-4.3 |
0.00 (n=1) | 0.00 (n=4) | 0.25 (n=16) | 0.85 (n=229) | 0.69 (n=26) | 276 |
See report_assets/calibration.svg for the visual reliability diagram.
Latency tail
Section titled “Latency tail”Median latency hides outliers. p99 and max are what determines queue depth and worst-case user wait. For OpenRouter-routed models the tail also reflects upstream provider load, not just model compute.
| Model | p50 | p90 | p95 | p99 | max |
|---|---|---|---|---|---|
mistralai/codestral-2508 |
0.73s | 1.72s | 2.24s | 4.67s | 6.36s |
google/gemini-3.1-flash-lite |
0.79s | 1.27s | 1.44s | 1.96s | 17.47s |
meta-llama/llama-3.1-8b-instruct |
0.79s | 2.39s | 4.04s | 7.07s | 76.80s |
meta-llama/llama-4-scout |
0.84s | 3.23s | 4.44s | 6.25s | 16.81s |
mistralai/mistral-medium-3.1 |
0.91s | 4.84s | 6.18s | 8.28s | 11.71s |
google/gemini-2.5-flash-lite |
0.92s | 1.92s | 3.23s | 6.53s | 17.01s |
cohere/command-r-plus-08-2024 |
0.95s | 2.23s | 3.45s | 14.64s | 62.06s |
google/gemini-2.5-flash |
0.99s | 2.45s | 3.59s | 10.06s | 16.44s |
meta-llama/llama-4-maverick |
1.06s | 2.06s | 2.38s | 3.94s | 50.80s |
claude-haiku-4-5-20251001 |
1.17s | 3.18s | 4.06s | 181.18s | 186.76s |
openai/gpt-5.4-mini |
1.18s | 1.66s | 2.24s | 3.13s | 4.94s |
openai/gpt-3.5-turbo |
1.26s | 1.77s | 1.95s | 2.58s | 8.25s |
claude-sonnet-4-6 |
1.44s | 4.71s | 6.04s | 8.75s | 185.04s |
meta-llama/llama-3.3-70b-instruct |
1.47s | 3.22s | 4.82s | 14.03s | 45.01s |
openai/gpt-5.4 |
1.82s | 2.58s | 3.12s | 4.81s | 17.20s |
deepseek/deepseek-r1-distill-llama-70b |
1.98s | 15.01s | 51.21s | 94.11s | 136.13s |
claude-opus-4-7 |
2.17s | 3.56s | 4.21s | 6.25s | 181.97s |
google/gemma-4-31b-it |
2.21s | 14.13s | 19.39s | 66.10s | 377.81s |
claude-opus-4-8 |
2.21s | 3.79s | 6.42s | 183.45s | 185.75s |
qwen/qwen3-235b-a22b-2507 |
2.28s | 6.26s | 7.75s | 11.89s | 24.93s |
microsoft/phi-4 |
2.29s | 6.71s | 11.55s | 203.39s | 229.43s |
mistralai/mistral-large-2512 |
2.55s | 5.40s | 6.20s | 8.68s | 18.09s |
deepseek/deepseek-v3.2 |
2.67s | 5.26s | 7.32s | 12.54s | 63.86s |
openai/gpt-oss-120b |
2.96s | 20.95s | 34.40s | 384.58s | 2880.77s |
deepseek/deepseek-v4-flash |
3.67s | 19.68s | 28.76s | 47.61s | 80.55s |
cohere/command-a |
3.78s | 8.49s | 11.46s | 30.31s | 65.77s |
x-ai/grok-4.3 |
3.88s | 9.63s | 12.56s | 18.90s | 33.29s |
google/gemini-3.5-flash |
5.23s | 9.10s | 11.13s | 15.80s | 32.29s |
openai/gpt-5.5 |
6.38s | 18.56s | 24.05s | 37.19s | 76.20s |
openai/o4-mini |
6.95s | 20.52s | 25.84s | 71.70s | 138.80s |
mistralai/mistral-7b-instruct-v0.1 |
7.11s | 23.05s | 33.05s | 79.21s | 89.36s |
openai/o3 |
8.08s | 19.36s | 27.07s | 57.15s | 76.89s |
minimax/minimax-m3 |
8.80s | 30.01s | 42.72s | 71.09s | 84.45s |
nvidia/nemotron-nano-9b-v2 |
12.05s | 31.04s | 36.70s | 50.76s | 65.31s |
qwen/qwen3.6-flash |
13.01s | 33.57s | 39.29s | 47.21s | 371.73s |
google/gemini-2.5-pro |
14.17s | 24.82s | 27.87s | 80.22s | 250.33s |
deepseek/deepseek-r1-0528 |
16.52s | 81.21s | 94.87s | 136.08s | 285.69s |
deepseek/deepseek-r1 |
19.86s | 90.13s | 153.13s | 264.17s | 364.40s |
qwen/qwen3-14b |
20.91s | 43.46s | 63.42s | 225.55s | 439.49s |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
24.21s | 82.63s | 86.23s | 99.39s | 106.19s |
deepseek/deepseek-v4-pro |
26.42s | 85.12s | 101.25s | 136.77s | 190.30s |
moonshotai/kimi-k2.6 |
35.30s | 116.25s | 160.11s | 229.07s | 411.39s |
qwen/qwen3.6-plus |
39.88s | 69.37s | 74.53s | 90.19s | 100.27s |
qwen/qwen3.5-plus-02-15 |
48.19s | 124.89s | 143.16s | 177.42s | 1486.87s |
qwen/qwen3-8b |
59.45s | 131.55s | 144.22s | 187.38s | 233.05s |
qwen/qwen3.5-27b |
68.74s | 273.44s | 1145.40s | 1651.28s | 2172.22s |
Output token efficiency
Section titled “Output token efficiency”How many output tokens the model spent per detected ad. Lower is more concise (the model finds an ad and returns the JSON). Higher means the model is producing a lot of text the parser will discard, which costs you whether or not the answer is right.
| Model | Total output tokens | Ads detected | Tokens / ad | Cost / TP |
|---|---|---|---|---|
mistralai/mistral-medium-3.1 |
40,161 | 646 | 62 | $0.0023 |
mistralai/codestral-2508 |
42,107 | 662 | 64 | $0.0020 |
google/gemini-2.5-flash |
67,460 | 925 | 73 | $0.0015 |
google/gemini-3.1-flash-lite |
60,147 | 815 | 74 | $0.0012 |
openai/gpt-3.5-turbo |
50,066 | 677 | 74 | $0.0049 |
meta-llama/llama-3.3-70b-instruct |
25,864 | 327 | 79 | $0.0010 |
cohere/command-r-plus-08-2024 |
10,247 | 128 | 80 | $0.0573 |
claude-sonnet-4-6 |
52,052 | 596 | 87 | $0.0167 |
meta-llama/llama-3.1-8b-instruct |
90,169 | 1015 | 89 | $0.0003 |
meta-llama/llama-4-scout |
48,083 | 540 | 89 | $0.0006 |
mistralai/mistral-large-2512 |
108,068 | 1201 | 90 | $0.0027 |
meta-llama/llama-4-maverick |
38,620 | 415 | 93 | $0.0011 |
claude-haiku-4-5-20251001 |
74,744 | 801 | 93 | $0.0052 |
deepseek/deepseek-v3.2 |
33,405 | 348 | 96 | $0.0022 |
google/gemini-2.5-flash-lite |
89,161 | 917 | 97 | $0.0005 |
google/gemma-4-31b-it |
55,826 | 570 | 98 | $0.0007 |
claude-opus-4-8 |
41,074 | 394 | 104 | $0.0393 |
qwen/qwen3-235b-a22b-2507 |
59,253 | 560 | 106 | $0.0005 |
cohere/command-a |
55,492 | 522 | 106 | $0.0199 |
openai/gpt-5.4 |
41,810 | 393 | 106 | $0.0133 |
claude-opus-4-7 |
36,811 | 341 | 108 | $0.0488 |
openai/gpt-5.4-mini |
46,289 | 420 | 110 | $0.0043 |
microsoft/phi-4 |
211,787 | 563 | 376 | $0.0022 |
deepseek/deepseek-r1-distill-llama-70b |
264,150 | 586 | 451 | $0.0089 |
deepseek/deepseek-v4-flash |
492,887 | 597 | 826 | $0.0006 |
x-ai/grok-4.3 |
547,955 | 595 | 921 | $0.0069 |
openai/gpt-5.5 |
310,390 | 330 | 941 | $0.0361 |
minimax/minimax-m3 |
576,740 | 469 | 1230 | $0.0023 |
openai/gpt-oss-120b |
736,151 | 585 | 1258 | $0.0004 |
deepseek/deepseek-r1-0528 |
1,197,928 | 871 | 1375 | $0.0060 |
deepseek/deepseek-r1 |
817,850 | 580 | 1410 | $0.0056 |
nvidia/nemotron-nano-9b-v2 |
1,220,752 | 556 | 2196 | $0.0010 |
qwen/qwen3-14b |
504,429 | 194 | 2600 | $0.0021 |
google/gemini-3.5-flash |
1,095,187 | 379 | 2890 | $0.0191 |
google/gemini-2.5-pro |
1,295,072 | 440 | 2943 | $0.0192 |
qwen/qwen3.6-flash |
1,566,281 | 416 | 3765 | $0.0026 |
openai/o3 |
700,781 | 182 | 3850 | $0.0223 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
1,461,554 | 370 | 3950 | $0.0017 |
deepseek/deepseek-v4-pro |
1,148,041 | 213 | 5390 | $0.0061 |
qwen/qwen3.6-plus |
1,990,086 | 369 | 5393 | $0.0056 |
qwen/qwen3.5-plus-02-15 |
3,059,957 | 373 | 8204 | $0.0068 |
moonshotai/kimi-k2.6 |
2,323,592 | 226 | 10281 | $0.0248 |
openai/o4-mini |
954,370 | 33 | 28920 | $0.1583 |
qwen/qwen3.5-27b |
9,663,262 | 307 | 31476 | $0.0196 |
qwen/qwen3-8b |
2,583,129 | 6 | 430522 | $0.2578 |
Trial variance (determinism check)
Section titled “Trial variance (determinism check)”All trials run at temperature 0.0. If a model produces stable output you’d expect the F1 stdev across trials to be near zero. Higher numbers mean the model is non-deterministic even at temp=0. That’s fine to know, but means you cannot trust a single trial’s number for that model.
| Model | Mean F1 stdev across episodes | Highest single-episode stdev |
|---|---|---|
claude-haiku-4-5-20251001 |
0.0017 | 0.0199 |
qwen/qwen3.6-plus |
0.0388 | 0.1582 |
qwen/qwen3.6-flash |
0.0761 | 0.2739 |
x-ai/grok-4.3 |
0.0727 | 0.1963 |
qwen/qwen3.5-plus-02-15 |
0.0347 | 0.1673 |
claude-sonnet-4-6 |
0.0253 | 0.1826 |
google/gemini-2.5-flash |
0.0000 | 0.0000 |
claude-opus-4-8 |
0.0536 | 0.1296 |
google/gemini-3.1-flash-lite |
0.0227 | 0.0913 |
openai/gpt-5.5 |
0.0780 | 0.1863 |
mistralai/mistral-medium-3.1 |
0.0613 | 0.1399 |
google/gemini-3.5-flash |
0.0328 | 0.1334 |
google/gemma-4-31b-it |
0.0568 | 0.1443 |
google/gemini-2.5-pro |
0.0504 | 0.1095 |
deepseek/deepseek-v4-flash |
0.1083 | 0.3130 |
minimax/minimax-m3 |
0.0731 | 0.2236 |
deepseek/deepseek-r1 |
0.1069 | 0.2739 |
openai/gpt-5.4 |
0.0771 | 0.1253 |
qwen/qwen3.5-27b |
0.1510 | 0.3651 |
claude-opus-4-7 |
0.0757 | 0.2739 |
openai/gpt-oss-120b |
0.1009 | 0.3651 |
openai/gpt-5.4-mini |
0.1148 | 0.2887 |
google/gemini-2.5-flash-lite |
0.0604 | 0.1532 |
openai/o3 |
0.1556 | 0.4714 |
meta-llama/llama-4-scout |
0.1444 | 0.3759 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.1502 | 0.3651 |
mistralai/codestral-2508 |
0.0817 | 0.1869 |
mistralai/mistral-large-2512 |
0.0617 | 0.1520 |
deepseek/deepseek-r1-0528 |
0.1499 | 0.2807 |
qwen/qwen3-235b-a22b-2507 |
0.1198 | 0.2859 |
meta-llama/llama-4-maverick |
0.0242 | 0.1600 |
cohere/command-a |
0.0523 | 0.1217 |
deepseek/deepseek-v4-pro |
0.2175 | 0.4382 |
moonshotai/kimi-k2.6 |
0.1578 | 0.2739 |
deepseek/deepseek-v3.2 |
0.1999 | 0.5477 |
meta-llama/llama-3.3-70b-instruct |
0.1332 | 0.3651 |
nvidia/nemotron-nano-9b-v2 |
0.1757 | 0.3651 |
openai/gpt-3.5-turbo |
0.0094 | 0.0447 |
deepseek/deepseek-r1-distill-llama-70b |
0.1064 | 0.3070 |
qwen/qwen3-14b |
0.1732 | 0.3322 |
meta-llama/llama-3.1-8b-instruct |
0.1499 | 0.5477 |
cohere/command-r-plus-08-2024 |
0.0884 | 0.4472 |
microsoft/phi-4 |
0.1097 | 0.3651 |
openai/o4-mini |
0.1255 | 0.2981 |
qwen/qwen3-8b |
0.0106 | 0.1278 |
mistralai/mistral-7b-instruct-v0.1 |
0.0000 | 0.0000 |
Cross-model agreement
Section titled “Cross-model agreement”For each of the 171 (episode, window, trial-equivalent) entries, how many of the 46 active models predicted at least one ad? High-agreement windows are unambiguous ads (or unambiguously not ads). Low-agreement windows are where individual models disagree, and are candidates for ensemble voting if you want a cheap accuracy boost.
| Models predicting an ad | Window count | Share |
|---|---|---|
| 2 of 46 | 1 | 0.6% |
| 4 of 46 | 8 | 4.7% |
| 5 of 46 | 15 | 8.8% |
| 6 of 46 | 10 | 5.8% |
| 7 of 46 | 7 | 4.1% |
| 8 of 46 | 6 | 3.5% |
| 9 of 46 | 7 | 4.1% |
| 10 of 46 | 9 | 5.3% |
| 11 of 46 | 8 | 4.7% |
| 12 of 46 | 6 | 3.5% |
| 13 of 46 | 6 | 3.5% |
| 14 of 46 | 2 | 1.2% |
| 15 of 46 | 3 | 1.8% |
| 16 of 46 | 4 | 2.3% |
| 17 of 46 | 1 | 0.6% |
| 18 of 46 | 1 | 0.6% |
| 19 of 46 | 2 | 1.2% |
| 27 of 46 | 2 | 1.2% |
| 28 of 46 | 1 | 0.6% |
| 29 of 46 | 1 | 0.6% |
| 31 of 46 | 2 | 1.2% |
| 32 of 46 | 1 | 0.6% |
| 34 of 46 | 1 | 0.6% |
| 35 of 46 | 2 | 1.2% |
| 37 of 46 | 2 | 1.2% |
| 38 of 46 | 3 | 1.8% |
| 39 of 46 | 6 | 3.5% |
| 40 of 46 | 14 | 8.2% |
| 41 of 46 | 16 | 9.4% |
| 42 of 46 | 12 | 7.0% |
| 43 of 46 | 9 | 5.3% |
| 44 of 46 | 3 | 1.8% |
Read this as: rows near the top are windows where the field disagrees (most models said no, a few said yes, usually false positives); rows near the bottom are windows where the field broadly agrees (typical of clear sponsor reads).
Per-model alignment with consensus
Section titled “Per-model alignment with consensus”Same data, viewed per model. For each window, the majority is whether more than half of the 46 active models flagged an ad. Then for each model: did it vote with the majority or against it? Four buckets:
- with-yes: this model voted yes, majority also voted yes (likely true positive)
- with-no: this model voted no, majority also voted no (likely true negative)
- broke-yes: this model voted yes, majority voted no (likely false positive / hallucination)
- broke-no: this model voted no, majority voted yes (likely missed real ad)
Alignment rate is (with-yes + with-no) / total. High alignment means the model tracks the consensus; low alignment means it disagrees often, which could be brilliance or noise depending on whether its disagreements are also where its F1 wins or loses.
| Model | with-yes | with-no | broke-yes | broke-no | Alignment |
|---|---|---|---|---|---|
minimax/minimax-m3 |
74 | 95 | 1 | 1 | 98.8% |
qwen/qwen3.5-plus-02-15 |
73 | 96 | 0 | 2 | 98.8% |
x-ai/grok-4.3 |
73 | 96 | 0 | 2 | 98.8% |
google/gemini-2.5-flash |
74 | 94 | 2 | 1 | 98.2% |
qwen/qwen3.5-27b |
72 | 96 | 0 | 3 | 98.2% |
claude-opus-4-8 |
71 | 96 | 0 | 4 | 97.7% |
openai/gpt-oss-120b |
75 | 92 | 4 | 0 | 97.7% |
openai/gpt-5.5 |
73 | 93 | 3 | 2 | 97.1% |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
69 | 96 | 0 | 6 | 96.5% |
claude-sonnet-4-6 |
67 | 96 | 0 | 8 | 95.3% |
google/gemini-2.5-pro |
75 | 88 | 8 | 0 | 95.3% |
google/gemini-3.5-flash |
67 | 96 | 0 | 8 | 95.3% |
google/gemma-4-31b-it |
73 | 90 | 6 | 2 | 95.3% |
mistralai/mistral-medium-3.1 |
68 | 95 | 1 | 7 | 95.3% |
qwen/qwen3.6-plus |
68 | 95 | 1 | 7 | 95.3% |
claude-haiku-4-5-20251001 |
69 | 93 | 3 | 6 | 94.7% |
qwen/qwen3.6-flash |
70 | 92 | 4 | 5 | 94.7% |
openai/o3 |
63 | 96 | 0 | 12 | 93.0% |
claude-opus-4-7 |
62 | 96 | 0 | 13 | 92.4% |
meta-llama/llama-4-scout |
73 | 85 | 11 | 2 | 92.4% |
google/gemini-3.1-flash-lite |
75 | 80 | 16 | 0 | 90.6% |
meta-llama/llama-3.3-70b-instruct |
64 | 89 | 7 | 11 | 89.5% |
deepseek/deepseek-v4-flash |
75 | 77 | 19 | 0 | 88.9% |
nvidia/nemotron-nano-9b-v2 |
73 | 78 | 18 | 2 | 88.3% |
meta-llama/llama-4-maverick |
72 | 78 | 18 | 3 | 87.7% |
deepseek/deepseek-r1 |
75 | 74 | 22 | 0 | 87.1% |
meta-llama/llama-3.1-8b-instruct |
70 | 78 | 18 | 5 | 86.5% |
deepseek/deepseek-v4-pro |
61 | 82 | 14 | 14 | 83.6% |
google/gemini-2.5-flash-lite |
75 | 68 | 28 | 0 | 83.6% |
mistralai/codestral-2508 |
69 | 71 | 25 | 6 | 81.9% |
openai/gpt-5.4 |
74 | 66 | 30 | 1 | 81.9% |
qwen/qwen3-14b |
65 | 73 | 23 | 10 | 80.7% |
openai/gpt-5.4-mini |
73 | 59 | 37 | 2 | 77.2% |
cohere/command-a |
71 | 56 | 40 | 4 | 74.3% |
cohere/command-r-plus-08-2024 |
25 | 96 | 0 | 50 | 70.8% |
openai/o4-mini |
25 | 96 | 0 | 50 | 70.8% |
deepseek/deepseek-v3.2 |
53 | 63 | 33 | 22 | 67.8% |
mistralai/mistral-large-2512 |
74 | 41 | 55 | 1 | 67.3% |
deepseek/deepseek-r1-0528 |
71 | 34 | 62 | 4 | 61.4% |
qwen/qwen3-235b-a22b-2507 |
75 | 30 | 66 | 0 | 61.4% |
openai/gpt-3.5-turbo |
75 | 28 | 68 | 0 | 60.2% |
qwen/qwen3-8b |
2 | 96 | 0 | 73 | 57.3% |
mistralai/mistral-7b-instruct-v0.1 |
0 | 96 | 0 | 75 | 56.1% |
moonshotai/kimi-k2.6 |
48 | 42 | 54 | 27 | 52.6% |
deepseek/deepseek-r1-distill-llama-70b |
66 | 8 | 88 | 9 | 43.3% |
microsoft/phi-4 |
55 | 14 | 82 | 20 | 40.4% |
Detection rate by ad characteristic
Section titled “Detection rate by ad characteristic”Aggregate detection rates often hide systematic blind spots. Below: for each model, what fraction of truth ads in each bucket were detected (matched at IoU >= 0.5).
By ad length
Section titled “By ad length”Truth ads bucketed by duration: short (<30s), medium (30-90s), long (>=90s). Cell values are detection rate (fraction of truth ads in that bucket the model caught), with the sample size n so a misleading 1.00 on a 2-ad bucket doesn’t get over-weighted. Models that systematically miss short ads usually fail on network-inserted brand-tagline spots; missing long ads is rarer and usually means the model gave up before processing the full window.
| Model | long (>=90s) | medium (30-90s) | short (<30s) |
|---|---|---|---|
claude-haiku-4-5-20251001 |
0.89 (n=140) | 0.93 (n=75) | 0.88 (n=40) |
claude-opus-4-7 |
0.62 (n=140) | 0.75 (n=75) | 0.42 (n=40) |
claude-opus-4-8 |
0.85 (n=140) | 0.80 (n=75) | 0.50 (n=40) |
claude-sonnet-4-6 |
0.87 (n=140) | 0.84 (n=75) | 0.68 (n=40) |
cohere/command-a |
0.41 (n=140) | 0.63 (n=75) | 0.75 (n=40) |
cohere/command-r-plus-08-2024 |
0.26 (n=140) | 0.05 (n=75) | 0.12 (n=40) |
deepseek/deepseek-r1 |
0.79 (n=140) | 0.76 (n=75) | 0.78 (n=40) |
deepseek/deepseek-r1-0528 |
0.60 (n=140) | 0.73 (n=75) | 0.75 (n=40) |
deepseek/deepseek-r1-distill-llama-70b |
0.25 (n=140) | 0.29 (n=75) | 0.62 (n=40) |
deepseek/deepseek-v3.2 |
0.51 (n=140) | 0.31 (n=75) | 0.28 (n=40) |
deepseek/deepseek-v4-flash |
0.79 (n=140) | 0.79 (n=75) | 0.75 (n=40) |
deepseek/deepseek-v4-pro |
0.53 (n=140) | 0.29 (n=75) | 0.20 (n=40) |
google/gemini-2.5-flash |
0.89 (n=140) | 0.93 (n=75) | 0.88 (n=40) |
google/gemini-2.5-flash-lite |
0.79 (n=140) | 0.87 (n=75) | 0.75 (n=40) |
google/gemini-2.5-pro |
0.84 (n=140) | 0.79 (n=75) | 0.62 (n=40) |
google/gemini-3.1-flash-lite |
0.87 (n=140) | 0.87 (n=75) | 0.88 (n=40) |
google/gemini-3.5-flash |
0.72 (n=140) | 0.76 (n=75) | 0.65 (n=40) |
google/gemma-4-31b-it |
0.83 (n=140) | 0.72 (n=75) | 0.60 (n=40) |
meta-llama/llama-3.1-8b-instruct |
0.20 (n=140) | 0.28 (n=75) | 0.35 (n=40) |
meta-llama/llama-3.3-70b-instruct |
0.35 (n=140) | 0.37 (n=75) | 0.53 (n=40) |
meta-llama/llama-4-maverick |
0.50 (n=140) | 0.69 (n=75) | 0.38 (n=40) |
meta-llama/llama-4-scout |
0.54 (n=140) | 0.60 (n=75) | 0.55 (n=40) |
microsoft/phi-4 |
0.07 (n=140) | 0.21 (n=75) | 0.15 (n=40) |
minimax/minimax-m3 |
0.79 (n=140) | 0.72 (n=75) | 0.68 (n=40) |
mistralai/codestral-2508 |
0.67 (n=140) | 0.69 (n=75) | 0.45 (n=40) |
mistralai/mistral-7b-instruct-v0.1 |
0.00 (n=140) | 0.00 (n=75) | 0.00 (n=40) |
mistralai/mistral-large-2512 |
0.84 (n=140) | 0.81 (n=75) | 0.62 (n=40) |
mistralai/mistral-medium-3.1 |
0.72 (n=140) | 0.79 (n=75) | 0.72 (n=40) |
moonshotai/kimi-k2.6 |
0.30 (n=140) | 0.52 (n=75) | 0.25 (n=40) |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.45 (n=140) | 0.57 (n=75) | 0.60 (n=40) |
nvidia/nemotron-nano-9b-v2 |
0.26 (n=140) | 0.41 (n=75) | 0.35 (n=40) |
openai/gpt-3.5-turbo |
0.31 (n=140) | 0.40 (n=75) | 0.75 (n=40) |
openai/gpt-5.4 |
0.80 (n=140) | 0.73 (n=75) | 0.57 (n=40) |
openai/gpt-5.4-mini |
0.74 (n=140) | 0.63 (n=75) | 0.72 (n=40) |
openai/gpt-5.5 |
0.74 (n=140) | 0.77 (n=75) | 0.57 (n=40) |
openai/gpt-oss-120b |
0.64 (n=140) | 0.75 (n=75) | 0.75 (n=40) |
openai/o3 |
0.66 (n=140) | 0.44 (n=75) | 0.30 (n=40) |
openai/o4-mini |
0.03 (n=140) | 0.05 (n=75) | 0.10 (n=40) |
qwen/qwen3-14b |
0.23 (n=140) | 0.21 (n=75) | 0.30 (n=40) |
qwen/qwen3-235b-a22b-2507 |
0.50 (n=140) | 0.65 (n=75) | 0.88 (n=40) |
qwen/qwen3-8b |
0.01 (n=140) | 0.00 (n=75) | 0.00 (n=40) |
qwen/qwen3.5-27b |
0.61 (n=140) | 0.69 (n=75) | 0.65 (n=40) |
qwen/qwen3.5-plus-02-15 |
0.86 (n=116) | 0.81 (n=72) | 0.60 (n=40) |
qwen/qwen3.6-flash |
0.91 (n=140) | 0.72 (n=75) | 0.70 (n=40) |
qwen/qwen3.6-plus |
0.84 (n=140) | 0.83 (n=75) | 0.50 (n=40) |
x-ai/grok-4.3 |
0.85 (n=140) | 0.91 (n=75) | 0.72 (n=40) |
By ad position
Section titled “By ad position”Truth ads bucketed by where they fall in the episode: pre-roll (first 10%), mid-roll (10-90%), post-roll (last 10%). Cell values are the same detection-rate-with-n format as ad length. A common failure pattern in our data: most models detect pre-roll and mid-roll reliably and miss post-roll, because the prompt windows near the end often catch the model mid-reasoning or with fewer transition phrases to anchor on.
| Model | pre-roll (<10%) | mid-roll (10-90%) | post-roll (>90%) |
|---|---|---|---|
claude-haiku-4-5-20251001 |
0.80 (n=75) | 0.96 (n=125) | 0.91 (n=55) |
claude-opus-4-7 |
0.65 (n=75) | 0.55 (n=125) | 0.76 (n=55) |
claude-opus-4-8 |
0.80 (n=75) | 0.77 (n=125) | 0.78 (n=55) |
claude-sonnet-4-6 |
0.80 (n=75) | 0.86 (n=125) | 0.82 (n=55) |
cohere/command-a |
0.52 (n=75) | 0.52 (n=125) | 0.55 (n=55) |
cohere/command-r-plus-08-2024 |
0.05 (n=75) | 0.28 (n=125) | 0.11 (n=55) |
deepseek/deepseek-r1 |
0.65 (n=75) | 0.88 (n=125) | 0.71 (n=55) |
deepseek/deepseek-r1-0528 |
0.60 (n=75) | 0.71 (n=125) | 0.64 (n=55) |
deepseek/deepseek-r1-distill-llama-70b |
0.33 (n=75) | 0.32 (n=125) | 0.31 (n=55) |
deepseek/deepseek-v3.2 |
0.45 (n=75) | 0.53 (n=125) | 0.11 (n=55) |
deepseek/deepseek-v4-flash |
0.69 (n=75) | 0.86 (n=125) | 0.73 (n=55) |
deepseek/deepseek-v4-pro |
0.31 (n=75) | 0.50 (n=125) | 0.35 (n=55) |
google/gemini-2.5-flash |
0.80 (n=75) | 1.00 (n=125) | 0.82 (n=55) |
google/gemini-2.5-flash-lite |
0.69 (n=75) | 0.89 (n=125) | 0.78 (n=55) |
google/gemini-2.5-pro |
0.79 (n=75) | 0.82 (n=125) | 0.73 (n=55) |
google/gemini-3.1-flash-lite |
0.80 (n=75) | 0.99 (n=125) | 0.69 (n=55) |
google/gemini-3.5-flash |
0.67 (n=75) | 0.75 (n=125) | 0.73 (n=55) |
google/gemma-4-31b-it |
0.67 (n=75) | 0.81 (n=125) | 0.78 (n=55) |
meta-llama/llama-3.1-8b-instruct |
0.23 (n=75) | 0.26 (n=125) | 0.25 (n=55) |
meta-llama/llama-3.3-70b-instruct |
0.25 (n=75) | 0.46 (n=125) | 0.40 (n=55) |
meta-llama/llama-4-maverick |
0.49 (n=75) | 0.60 (n=125) | 0.45 (n=55) |
meta-llama/llama-4-scout |
0.47 (n=75) | 0.62 (n=125) | 0.53 (n=55) |
microsoft/phi-4 |
0.24 (n=75) | 0.04 (n=125) | 0.16 (n=55) |
minimax/minimax-m3 |
0.64 (n=75) | 0.84 (n=125) | 0.71 (n=55) |
mistralai/codestral-2508 |
0.44 (n=75) | 0.73 (n=125) | 0.73 (n=55) |
mistralai/mistral-7b-instruct-v0.1 |
0.00 (n=75) | 0.00 (n=125) | 0.00 (n=55) |
mistralai/mistral-large-2512 |
0.73 (n=75) | 0.87 (n=125) | 0.73 (n=55) |
mistralai/mistral-medium-3.1 |
0.75 (n=75) | 0.74 (n=125) | 0.73 (n=55) |
moonshotai/kimi-k2.6 |
0.29 (n=75) | 0.31 (n=125) | 0.55 (n=55) |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.45 (n=75) | 0.55 (n=125) | 0.49 (n=55) |
nvidia/nemotron-nano-9b-v2 |
0.23 (n=75) | 0.30 (n=125) | 0.47 (n=55) |
openai/gpt-3.5-turbo |
0.31 (n=75) | 0.48 (n=125) | 0.36 (n=55) |
openai/gpt-5.4 |
0.75 (n=75) | 0.78 (n=125) | 0.65 (n=55) |
openai/gpt-5.4-mini |
0.60 (n=75) | 0.83 (n=125) | 0.55 (n=55) |
openai/gpt-5.5 |
0.73 (n=75) | 0.73 (n=125) | 0.71 (n=55) |
openai/gpt-oss-120b |
0.64 (n=75) | 0.73 (n=125) | 0.67 (n=55) |
openai/o3 |
0.44 (n=75) | 0.59 (n=125) | 0.55 (n=55) |
openai/o4-mini |
0.01 (n=75) | 0.06 (n=125) | 0.05 (n=55) |
qwen/qwen3-14b |
0.13 (n=75) | 0.29 (n=125) | 0.25 (n=55) |
qwen/qwen3-235b-a22b-2507 |
0.59 (n=75) | 0.62 (n=125) | 0.58 (n=55) |
qwen/qwen3-8b |
0.00 (n=75) | 0.01 (n=125) | 0.00 (n=55) |
qwen/qwen3.5-27b |
0.56 (n=75) | 0.69 (n=125) | 0.65 (n=55) |
qwen/qwen3.5-plus-02-15 |
0.82 (n=66) | 0.83 (n=110) | 0.71 (n=52) |
qwen/qwen3.6-flash |
0.71 (n=75) | 0.92 (n=125) | 0.75 (n=55) |
qwen/qwen3.6-plus |
0.75 (n=75) | 0.84 (n=125) | 0.71 (n=55) |
x-ai/grok-4.3 |
0.80 (n=75) | 0.90 (n=125) | 0.80 (n=55) |
Quick Comparison
Section titled “Quick Comparison”One row per model, one column per episode. The headline columns (F1, Cost/ep, p50) summarize across all episodes; the per-episode columns let you see whether a model’s average hides wide swings (a model that scores well overall might still bomb on a specific genre). The right-most F1 stdev column averages the per-trial standard deviations across episodes; high values mean the model isn’t deterministic at temperature 0.0, so its single-trial F1 number is noisy.
| Model | F1 | Cost/ep | p50 | ep-crime-junkie-8ce498f299d7 | ep-daily-gist-chicago-70a82fe93a5c | ep-daily-tech-news-show-b576979e1fe8 | ep-daily-tech-news-show-c1904b8605f7 | ep-drink-champs-30c9a2d49f13 | ep-glt1412515089-373d5ba5007b | ep-it-s-a-thing-e339179dfad6 | ep-on-air-with-dan-and-alex2-574e4f303730 | ep-security-now-audio-2850b24903b2 | ep-the-brilliant-idiots-0bb9bf634c8e | ep-the-tim-dillon-show-f62bd5fa1cfe | ep-tosh-show-5f6894439bb6 | ep-ai-cloud-essentials-e8dc897fbd6b (no-ad) | ep-oxide-and-friends-ce789ff5b62e (no-ad) | F1 stdev |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
claude-haiku-4-5-20251001 |
0.837 | $1.2017 | 1.2s | 1.000 | 1.000 | 1.000 | 0.378 | 1.000 | 0.727 | 0.667 | 1.000 | 0.857 | 0.857 | 0.833 | 0.727 | PASS | PASS | 0.002 |
qwen/qwen3.6-plus |
0.807 | $1.1119 | 39.9s | 1.000 | 0.667 | 0.914 | 0.600 | 0.867 | 0.857 | 0.667 | 0.960 | 0.714 | 0.921 | 0.800 | 0.716 | PASS | PASS | 0.039 |
qwen/qwen3.6-flash |
0.802 | $0.5461 | 13.0s | 1.000 | 0.800 | 0.943 | 0.653 | 0.804 | 0.700 | 0.667 | 0.880 | 0.771 | 0.933 | 0.744 | 0.727 | FAIL (1 FP) | PASS | 0.076 |
x-ai/grok-4.3 |
0.797 | $1.4987 | 3.9s | 1.000 | 0.533 | 0.971 | 0.547 | 0.946 | 0.864 | 0.667 | 0.840 | 0.714 | 0.914 | 0.781 | 0.782 | PASS | PASS | 0.073 |
qwen/qwen3.5-plus-02-15 |
0.794 | $1.2346 | 48.2s | 1.000 | 0.600 | 0.857 | 0.653 | 0.842 | 0.886 | 0.667 | 0.800 | 0.714 | 0.886 | 0.800 | 0.827 | PASS | PASS | 0.035 |
claude-sonnet-4-6 |
0.786 | $3.5376 | 1.4s | 1.000 | 0.800 | 1.000 | 0.627 | 0.938 | 0.571 | 0.667 | 0.800 | 0.714 | 0.971 | 0.615 | 0.727 | PASS | PASS | 0.025 |
google/gemini-2.5-flash |
0.777 | $0.3435 | 1.0s | 1.000 | 1.000 | 1.000 | 0.545 | 0.857 | 0.889 | 0.400 | 0.800 | 0.667 | 0.667 | 0.833 | 0.667 | PASS | PASS | 0.000 |
claude-opus-4-8 |
0.767 | $7.8217 | 2.2s | 0.886 | 0.500 | 0.886 | 0.589 | 0.916 | 0.857 | 0.667 | 0.800 | 0.796 | 0.821 | 0.684 | 0.800 | PASS | PASS | 0.054 |
google/gemini-3.1-flash-lite |
0.756 | $0.2762 | 0.8s | 1.000 | 1.000 | 0.971 | 0.600 | 0.803 | 0.771 | 0.567 | 0.800 | 0.582 | 0.520 | 0.727 | 0.727 | FAIL (1 FP) | PASS | 0.023 |
openai/gpt-5.5 |
0.750 | $6.6806 | 6.4s | 0.943 | 0.500 | 0.886 | 0.633 | 0.766 | 0.886 | 0.667 | 0.800 | 0.708 | 0.903 | 0.680 | 0.633 | FAIL (1 FP) | PASS | 0.078 |
mistralai/mistral-medium-3.1 |
0.739 | $0.4380 | 0.9s | 0.876 | 0.667 | 0.821 | 0.556 | 0.550 | 0.883 | 0.667 | 1.000 | 0.718 | 0.679 | 0.745 | 0.702 | PASS | PASS | 0.061 |
google/gemini-3.5-flash |
0.738 | $3.5200 | 5.2s | 0.914 | 0.500 | 0.857 | 0.600 | 0.562 | 0.943 | 0.667 | 0.800 | 0.714 | 1.000 | 0.760 | 0.536 | PASS | PASS | 0.033 |
google/gemma-4-31b-it |
0.729 | $0.1291 | 2.2s | 1.000 | 0.480 | 0.850 | 0.600 | 0.723 | 0.950 | 0.667 | 1.000 | 0.667 | 0.700 | 0.799 | 0.311 | FAIL (1 FP) | PASS | 0.057 |
google/gemini-2.5-pro |
0.726 | $3.8631 | 14.2s | 0.971 | 0.500 | 0.864 | 0.578 | 0.821 | 0.956 | 0.667 | 0.720 | 0.650 | 0.653 | 0.720 | 0.609 | FAIL (1 FP) | FAIL (1 FP) | 0.050 |
deepseek/deepseek-v4-flash |
0.725 | $0.1182 | 3.7s | 0.864 | 0.527 | 0.933 | 0.569 | 0.532 | 0.901 | 0.733 | 0.773 | 0.695 | 0.717 | 0.791 | 0.669 | FAIL (1 FP) | PASS | 0.108 |
minimax/minimax-m3 |
0.720 | $0.4367 | 8.8s | 0.971 | 0.600 | 0.943 | 0.569 | 0.705 | 0.892 | 0.667 | 0.800 | 0.676 | 0.528 | 0.680 | 0.609 | PASS | PASS | 0.073 |
deepseek/deepseek-r1 |
0.702 | $1.1157 | 19.9s | 0.971 | 0.633 | 0.914 | 0.507 | 0.679 | 0.911 | 0.467 | 0.787 | 0.661 | 0.487 | 0.730 | 0.681 | FAIL (1 FP) | FAIL (1 FP) | 0.107 |
openai/gpt-5.4 |
0.700 | $2.5345 | 1.8s | 1.000 | 0.500 | 0.892 | 0.567 | 0.676 | 0.641 | 0.613 | 0.920 | 0.668 | 0.568 | 0.735 | 0.622 | FAIL (1 FP) | FAIL (1 FP) | 0.077 |
qwen/qwen3.5-27b |
0.683 | $3.2163 | 68.7s | 0.914 | 0.667 | 0.743 | 0.582 | 0.675 | 0.757 | 0.600 | 0.740 | 0.488 | 0.716 | 0.607 | 0.707 | PASS | PASS | 0.151 |
claude-opus-4-7 |
0.669 | $7.8054 | 2.2s | 0.857 | 0.200 | 0.886 | 0.378 | 0.393 | 0.857 | 0.667 | 0.800 | 0.771 | 0.836 | 0.760 | 0.622 | PASS | PASS | 0.076 |
openai/gpt-oss-120b |
0.653 | $0.0643 | 3.0s | 0.876 | 0.600 | 0.507 | 0.545 | 0.247 | 1.000 | 0.440 | 0.720 | 0.669 | 0.857 | 0.695 | 0.678 | FAIL (1 FP) | PASS | 0.101 |
openai/gpt-5.4-mini |
0.651 | $0.7644 | 1.2s | 0.906 | 0.833 | 0.943 | 0.524 | 0.595 | 0.645 | 0.500 | 0.800 | 0.643 | 0.375 | 0.443 | 0.607 | FAIL (1 FP) | FAIL (1 FP) | 0.115 |
google/gemini-2.5-flash-lite |
0.618 | $0.1104 | 0.9s | 1.000 | 0.500 | 0.821 | 0.489 | 0.698 | 0.599 | 0.261 | 0.800 | 0.411 | 0.580 | 0.579 | 0.676 | FAIL (1 FP) | PASS | 0.060 |
openai/o3 |
0.595 | $3.0485 | 8.1s | 0.876 | 0.000 | 0.848 | 0.486 | 0.789 | 0.743 | 0.333 | 0.760 | 0.714 | 0.740 | 0.381 | 0.475 | PASS | PASS | 0.156 |
meta-llama/llama-4-scout |
0.591 | $0.0807 | 0.8s | 0.358 | 0.627 | 0.592 | 0.432 | 0.147 | 0.679 | 0.800 | 0.880 | 0.667 | 0.681 | 0.505 | 0.727 | PASS | PASS | 0.144 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.579 | $0.2159 | 24.2s | 0.943 | 0.667 | 0.648 | 0.364 | 0.208 | 0.810 | 0.267 | 0.753 | 0.749 | 0.613 | 0.290 | 0.633 | PASS | PASS | 0.150 |
mistralai/codestral-2508 |
0.577 | $0.3241 | 0.7s | 0.950 | 0.667 | 0.698 | 0.551 | 0.343 | 0.303 | 0.420 | 0.693 | 0.501 | 0.542 | 0.535 | 0.718 | PASS | PASS | 0.082 |
mistralai/mistral-large-2512 |
0.563 | $0.5599 | 2.6s | 0.733 | 0.427 | 0.978 | 0.545 | 0.574 | 0.368 | 0.513 | 0.800 | 0.367 | 0.310 | 0.409 | 0.727 | PASS | PASS | 0.062 |
deepseek/deepseek-r1-0528 |
0.557 | $1.0181 | 16.5s | 0.787 | 0.647 | 0.911 | 0.417 | 0.260 | 0.558 | 0.404 | 0.693 | 0.421 | 0.338 | 0.545 | 0.708 | FAIL (27 FP) | FAIL (12 FP) | 0.150 |
qwen/qwen3-235b-a22b-2507 |
0.529 | $0.0735 | 2.3s | 0.813 | 0.880 | 0.822 | 0.308 | 0.185 | 0.689 | 0.000 | 0.701 | 0.503 | 0.392 | 0.589 | 0.462 | FAIL (2 FP) | FAIL (6 FP) | 0.120 |
meta-llama/llama-4-maverick |
0.470 | $0.1508 | 1.1s | 1.000 | 0.000 | 0.771 | 0.228 | 0.316 | 0.703 | 0.000 | 0.800 | 0.660 | 0.492 | 0.222 | 0.444 | FAIL (1 FP) | PASS | 0.024 |
cohere/command-a |
0.464 | $2.6688 | 3.8s | 0.911 | 0.400 | 0.500 | 0.356 | 0.034 | 0.744 | 0.400 | 0.674 | 0.456 | 0.304 | 0.255 | 0.533 | FAIL (3 FP) | PASS | 0.052 |
deepseek/deepseek-v4-pro |
0.424 | $0.6376 | 26.4s | 0.819 | 0.133 | 0.507 | 0.381 | 0.420 | 0.477 | 0.267 | 0.280 | 0.634 | 0.180 | 0.687 | 0.305 | PASS | PASS | 0.218 |
moonshotai/kimi-k2.6 |
0.422 | $2.2593 | 35.3s | 0.547 | 0.100 | 0.914 | 0.600 | 0.054 | 0.532 | 0.200 | 0.867 | 0.196 | 0.598 | 0.189 | 0.267 | FAIL (1 FP) | FAIL (4 FP) | 0.158 |
deepseek/deepseek-v3.2 |
0.416 | $0.2328 | 2.7s | 0.686 | 0.300 | 0.622 | 0.396 | 0.301 | 0.584 | 0.400 | 0.400 | 0.553 | 0.100 | 0.389 | 0.257 | PASS | FAIL (2 FP) | 0.200 |
meta-llama/llama-3.3-70b-instruct |
0.395 | $0.1008 | 1.5s | 0.702 | 0.100 | 0.420 | 0.129 | 0.024 | 0.771 | 0.267 | 0.133 | 0.728 | 0.557 | 0.400 | 0.514 | PASS | PASS | 0.133 |
nvidia/nemotron-nano-9b-v2 |
0.316 | $0.0813 | 12.0s | 0.450 | 0.600 | 0.274 | 0.124 | 0.156 | 0.212 | 0.313 | 0.440 | 0.333 | 0.386 | 0.180 | 0.320 | FAIL (1 FP) | PASS | 0.176 |
openai/gpt-3.5-turbo |
0.315 | $0.5091 | 1.3s | 1.000 | 0.420 | 0.222 | 0.444 | 0.040 | 0.291 | 0.000 | 0.500 | 0.275 | 0.233 | 0.143 | 0.209 | FAIL (3 FP) | FAIL (10 FP) | 0.009 |
deepseek/deepseek-r1-distill-llama-70b |
0.261 | $0.7331 | 2.0s | 0.547 | 0.453 | 0.067 | 0.228 | 0.000 | 0.333 | 0.000 | 0.397 | 0.317 | 0.301 | 0.126 | 0.357 | FAIL (2 FP) | FAIL (10 FP) | 0.106 |
qwen/qwen3-14b |
0.260 | $0.1261 | 20.9s | 0.190 | 0.000 | 0.518 | 0.114 | 0.047 | 0.478 | 0.000 | 0.360 | 0.351 | 0.390 | 0.244 | 0.429 | PASS | FAIL (1 FP) | 0.173 |
meta-llama/llama-3.1-8b-instruct |
0.251 | $0.0207 | 0.8s | 0.168 | 0.700 | 0.231 | 0.084 | 0.224 | 0.286 | 0.400 | 0.367 | 0.141 | 0.000 | 0.211 | 0.197 | PASS | PASS | 0.150 |
cohere/command-r-plus-08-2024 |
0.162 | $2.5787 | 1.0s | 0.000 | 0.000 | 0.000 | 0.384 | 0.330 | 0.000 | 0.200 | 0.000 | 0.687 | 0.000 | 0.057 | 0.289 | PASS | PASS | 0.088 |
microsoft/phi-4 |
0.157 | $0.0713 | 2.3s | 0.562 | 0.000 | 0.160 | 0.144 | 0.059 | 0.000 | 0.000 | 0.400 | 0.076 | 0.174 | 0.312 | 0.000 | FAIL (3 FP) | FAIL (15 FP) | 0.110 |
openai/o4-mini |
0.075 | $1.8999 | 6.9s | 0.000 | 0.000 | 0.147 | 0.067 | 0.040 | 0.080 | 0.000 | 0.133 | 0.114 | 0.180 | 0.000 | 0.133 | PASS | PASS | 0.125 |
qwen/qwen3-8b |
0.005 | $0.2578 | 59.4s | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.057 | 0.000 | PASS | PASS | 0.011 |
mistralai/mistral-7b-instruct-v0.1 |
0.000 | $0.0000 | 7.1s | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | PASS | PASS | 0.000 |
Detailed Results
Section titled “Detailed Results”Per-Model Detail
Section titled “Per-Model Detail”Full per-model profile: F1 averaged across episodes, total cost per episode at current pricing, p50 / p95 latency, JSON compliance, parse-failure rate, the distribution of extraction methods the parser had to use, and verbosity / truncation telemetry. The Extraction methods list shows how often each route was hit. json_array_direct is the cleanest; the rest are recovery paths. The verbosity row flags models that emit long reason fields or run out of token budget mid-response. Ordered by F1 descending so the best performers appear first.
claude-haiku-4-5-20251001
Section titled “claude-haiku-4-5-20251001”- F1 (avg across episodes): 0.837
- Total cost / episode: $1.2017
- p50 / p95 latency: 1.17s / 4.06s
- JSON compliance: 0.60
- JSON mode: prompt-inject (0% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
markdown_code_block: 855 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 711
- Extra keys observed: end_text, sponsor
qwen/qwen3.6-plus
Section titled “qwen/qwen3.6-plus”- F1 (avg across episodes): 0.807
- Total cost / episode: $1.1119
- p50 / p95 latency: 39.88s / 74.53s
- JSON compliance: 1.00
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_array_direct: 855 - Verbosity: 813/855 calls over 1024 output tokens (95.1%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
qwen/qwen3.6-flash
Section titled “qwen/qwen3.6-flash”- F1 (avg across episodes): 0.802
- Total cost / episode: $0.5461
- p50 / p95 latency: 13.01s / 39.29s
- JSON compliance: 1.00
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_array_direct: 855 - Verbosity: 585/855 calls over 1024 output tokens (68.4%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
x-ai/grok-4.3
Section titled “x-ai/grok-4.3”- F1 (avg across episodes): 0.797
- Total cost / episode: $1.4987
- p50 / p95 latency: 3.88s / 12.56s
- JSON compliance: 1.00
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.1%
- Extraction methods:
json_array_direct: 854,parse_failure: 1 - Verbosity: 165/855 calls over 1024 output tokens (19.3%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
qwen/qwen3.5-plus-02-15
Section titled “qwen/qwen3.5-plus-02-15”- F1 (avg across episodes): 0.794
- Total cost / episode: $1.2346
- p50 / p95 latency: 48.19s / 143.16s
- JSON compliance: 1.00
- JSON mode: native (100% native, 852 calls)
- Parse failure rate: 0.1%
- Extraction methods:
json_array_direct: 851,parse_failure: 1 - Verbosity: 749/852 calls over 1024 output tokens (87.9%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 384
- Extra keys observed: end_text, sponsor
claude-sonnet-4-6
Section titled “claude-sonnet-4-6”- F1 (avg across episodes): 0.786
- Total cost / episode: $3.5376
- p50 / p95 latency: 1.44s / 6.04s
- JSON compliance: 0.96
- JSON mode: prompt-inject (0% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_array_direct: 783,markdown_code_block: 57,regex_json_array: 15 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 461
- Extra keys observed: end_text, sponsor
google/gemini-2.5-flash
Section titled “google/gemini-2.5-flash”- F1 (avg across episodes): 0.777
- Total cost / episode: $0.3435
- p50 / p95 latency: 0.99s / 3.59s
- JSON compliance: 1.00
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_array_direct: 855 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 710
- Extra keys observed: end_text, sponsor
claude-opus-4-8
Section titled “claude-opus-4-8”- F1 (avg across episodes): 0.767
- Total cost / episode: $7.8217
- p50 / p95 latency: 2.21s / 6.42s
- JSON compliance: 0.99
- JSON mode: prompt-inject (0% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_array_direct: 836,json_object_single_ad_truncated: 3,regex_json_array: 16 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 3 salvaged from truncated JSON (0.4%)
google/gemini-3.1-flash-lite
Section titled “google/gemini-3.1-flash-lite”- F1 (avg across episodes): 0.756
- Total cost / episode: $0.2762
- p50 / p95 latency: 0.79s / 1.44s
- JSON compliance: 0.96
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_array_direct: 799,regex_json_array: 56 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
openai/gpt-5.5
Section titled “openai/gpt-5.5”- F1 (avg across episodes): 0.750
- Total cost / episode: $6.6806
- p50 / p95 latency: 6.38s / 24.05s
- JSON compliance: 0.87
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.1%
- Extraction methods:
json_object_no_ads: 494,json_object_single_ad: 360,parse_failure: 1 - Verbosity: 76/855 calls over 1024 output tokens (8.9%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 332
- Extra keys observed: end_text, sponsor
mistralai/mistral-medium-3.1
Section titled “mistralai/mistral-medium-3.1”- F1 (avg across episodes): 0.739
- Total cost / episode: $0.4380
- p50 / p95 latency: 0.91s / 6.18s
- JSON compliance: 1.00
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_array_direct: 854,json_object_single_ad_truncated: 1 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 1 salvaged from truncated JSON (0.1%)
- Schema violations: 608
- Extra keys observed: end_text, sponsor
google/gemini-3.5-flash
Section titled “google/gemini-3.5-flash”- F1 (avg across episodes): 0.738
- Total cost / episode: $3.5200
- p50 / p95 latency: 5.23s / 11.13s
- JSON compliance: 1.00
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_array_direct: 850,json_object_single_ad_truncated: 1,regex_json_array: 4 - Verbosity: 519/855 calls over 1024 output tokens (60.7%); 1 hit max_tokens (0.1%); 1 salvaged from truncated JSON (0.1%)
google/gemma-4-31b-it
Section titled “google/gemma-4-31b-it”- F1 (avg across episodes): 0.729
- Total cost / episode: $0.1291
- p50 / p95 latency: 2.21s / 19.39s
- JSON compliance: 0.85
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.1%
- Extraction methods:
bracket_fallback: 1,json_object_ads_key: 455,json_object_no_ads: 216,json_object_single_ad: 180,json_object_single_ad_truncated: 2,parse_failure: 1 - Verbosity: 3/855 calls over 1024 output tokens (0.4%); 3 hit max_tokens (0.4%); 2 salvaged from truncated JSON (0.2%)
- Schema violations: 532
- Extra keys observed: end_text, sponsor
google/gemini-2.5-pro
Section titled “google/gemini-2.5-pro”- F1 (avg across episodes): 0.726
- Total cost / episode: $3.8631
- p50 / p95 latency: 14.17s / 27.87s
- JSON compliance: 0.97
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 1.4%
- Extraction methods:
json_array_direct: 818,parse_failure: 12,regex_json_array: 25 - Verbosity: 673/855 calls over 1024 output tokens (78.7%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 389
- Extra keys observed: end_text, sponsor
deepseek/deepseek-v4-flash
Section titled “deepseek/deepseek-v4-flash”- F1 (avg across episodes): 0.725
- Total cost / episode: $0.1182
- p50 / p95 latency: 3.67s / 28.76s
- JSON compliance: 0.81
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 2.0%
- Extraction methods:
json_array_direct: 102,json_object_ads_key: 435,json_object_no_ads: 21,json_object_segments_key: 7,json_object_single_ad: 272,parse_failure: 17,regex_json_array: 1 - Verbosity: 181/855 calls over 1024 output tokens (21.2%); 2 hit max_tokens (0.2%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 631
- Extra keys observed: end_text, sponsor
minimax/minimax-m3
Section titled “minimax/minimax-m3”- F1 (avg across episodes): 0.720
- Total cost / episode: $0.4367
- p50 / p95 latency: 8.80s / 42.72s
- JSON compliance: 0.88
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 1.6%
- Extraction methods:
json_array_direct: 625,json_object_single_ad_truncated: 1,markdown_code_block: 215,parse_failure: 14 - Verbosity: 159/855 calls over 1024 output tokens (18.6%); 15 hit max_tokens (1.8%); 1 salvaged from truncated JSON (0.1%)
deepseek/deepseek-r1
Section titled “deepseek/deepseek-r1”- F1 (avg across episodes): 0.702
- Total cost / episode: $1.1157
- p50 / p95 latency: 19.86s / 153.13s
- JSON compliance: 0.97
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.7%
- Extraction methods:
json_array_direct: 760,json_object_ads_key: 2,json_object_no_ads: 17,json_object_segments_key: 7,json_object_single_ad: 44,markdown_code_block: 17,parse_failure: 6,regex_json_array: 2 - Verbosity: 152/855 calls over 1024 output tokens (17.8%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 486
- Extra keys observed: end_text, sponsor
openai/gpt-5.4
Section titled “openai/gpt-5.4”- F1 (avg across episodes): 0.700
- Total cost / episode: $2.5345
- p50 / p95 latency: 1.82s / 3.12s
- JSON compliance: 0.81
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_object_no_ads: 326,json_object_single_ad: 529 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 398
- Extra keys observed: end_text, sponsor
qwen/qwen3.5-27b
Section titled “qwen/qwen3.5-27b”- F1 (avg across episodes): 0.683
- Total cost / episode: $3.2163
- p50 / p95 latency: 68.74s / 1145.40s
- JSON compliance: 0.85
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 14.2%
- Extraction methods:
json_array_direct: 633,json_object_no_ads: 89,json_object_single_ad: 12,parse_failure: 121 - Verbosity: 798/855 calls over 1024 output tokens (93.3%); 108 hit max_tokens (12.6%); 0 salvaged from truncated JSON (0.0%)
claude-opus-4-7
Section titled “claude-opus-4-7”- F1 (avg across episodes): 0.669
- Total cost / episode: $7.8054
- p50 / p95 latency: 2.17s / 4.21s
- JSON compliance: 1.00
- JSON mode: prompt-inject (0% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_array_direct: 850,regex_json_array: 5 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 341
- Extra keys observed: end_text, sponsor
openai/gpt-oss-120b
Section titled “openai/gpt-oss-120b”- F1 (avg across episodes): 0.653
- Total cost / episode: $0.0643
- p50 / p95 latency: 2.96s / 34.40s
- JSON compliance: 0.70
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 17.4%
- Extraction methods:
json_array_direct: 68,json_object_ads_key: 235,json_object_no_ads: 186,json_object_single_ad: 188,json_object_single_ad_truncated: 6,parse_failure: 149,regex_json_array: 23 - Verbosity: 162/855 calls over 1024 output tokens (18.9%); 2 hit max_tokens (0.2%); 6 salvaged from truncated JSON (0.7%)
openai/gpt-5.4-mini
Section titled “openai/gpt-5.4-mini”- F1 (avg across episodes): 0.651
- Total cost / episode: $0.7644
- p50 / p95 latency: 1.18s / 2.24s
- JSON compliance: 0.81
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_object_ads_key: 2,json_object_no_ads: 300,json_object_segments_key: 2,json_object_single_ad: 551 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
google/gemini-2.5-flash-lite
Section titled “google/gemini-2.5-flash-lite”- F1 (avg across episodes): 0.618
- Total cost / episode: $0.1104
- p50 / p95 latency: 0.92s / 3.23s
- JSON compliance: 0.97
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 2.2%
- Extraction methods:
json_array_direct: 793,json_object_single_ad_truncated: 43,parse_failure: 19 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 43 salvaged from truncated JSON (5.0%)
openai/o3
Section titled “openai/o3”- F1 (avg across episodes): 0.595
- Total cost / episode: $3.0485
- p50 / p95 latency: 8.08s / 27.07s
- JSON compliance: 0.92
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.6%
- Extraction methods:
json_object_ads_key: 34,json_object_no_ads: 621,json_object_segments_key: 12,json_object_single_ad: 183,parse_failure: 5 - Verbosity: 246/855 calls over 1024 output tokens (28.8%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 132
- Extra keys observed: end_text, sponsor
meta-llama/llama-4-scout
Section titled “meta-llama/llama-4-scout”- F1 (avg across episodes): 0.591
- Total cost / episode: $0.0807
- p50 / p95 latency: 0.84s / 4.44s
- JSON compliance: 0.82
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 1.1%
- Extraction methods:
bracket_fallback: 37,json_array_direct: 5,json_object_ads_key: 644,json_object_no_ads: 92,json_object_single_ad: 62,parse_failure: 9,regex_json_array: 6 - Verbosity: 1/855 calls over 1024 output tokens (0.1%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 507
- Extra keys observed: end_text, sponsor
nvidia/llama-3.3-nemotron-super-49b-v1.5
Section titled “nvidia/llama-3.3-nemotron-super-49b-v1.5”- F1 (avg across episodes): 0.579
- Total cost / episode: $0.2159
- p50 / p95 latency: 24.21s / 86.23s
- JSON compliance: 0.71
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 14.5%
- Extraction methods:
json_array_direct: 441,json_object_single_ad_truncated: 3,markdown_code_block: 257,parse_failure: 124,regex_json_array: 30 - Verbosity: 515/855 calls over 1024 output tokens (60.2%); 58 hit max_tokens (6.8%); 3 salvaged from truncated JSON (0.4%)
- Schema violations: 266
- Extra keys observed: end_text, sponsor
mistralai/codestral-2508
Section titled “mistralai/codestral-2508”- F1 (avg across episodes): 0.577
- Total cost / episode: $0.3241
- p50 / p95 latency: 0.73s / 2.24s
- JSON compliance: 1.00
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_array_direct: 855 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 622
- Extra keys observed: end_text, sponsor
mistralai/mistral-large-2512
Section titled “mistralai/mistral-large-2512”- F1 (avg across episodes): 0.563
- Total cost / episode: $0.5599
- p50 / p95 latency: 2.55s / 6.20s
- JSON compliance: 1.00
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_array_direct: 855 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 1342
- Extra keys observed: end_text, sponsor
deepseek/deepseek-r1-0528
Section titled “deepseek/deepseek-r1-0528”- F1 (avg across episodes): 0.557
- Total cost / episode: $1.0181
- p50 / p95 latency: 16.52s / 94.87s
- JSON compliance: 0.88
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 9.7%
- Extraction methods:
json_array_direct: 700,json_object_ads_key: 34,json_object_no_ads: 3,json_object_single_ad: 30,json_object_single_ad_truncated: 3,markdown_code_block: 2,parse_failure: 83 - Verbosity: 341/855 calls over 1024 output tokens (39.9%); 38 hit max_tokens (4.4%); 3 salvaged from truncated JSON (0.4%)
- Schema violations: 694
- Extra keys observed: end_text, sponsor
qwen/qwen3-235b-a22b-2507
Section titled “qwen/qwen3-235b-a22b-2507”- F1 (avg across episodes): 0.529
- Total cost / episode: $0.0735
- p50 / p95 latency: 2.28s / 7.75s
- JSON compliance: 0.79
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_array_direct: 173,json_object_ads_key: 1,json_object_no_ads: 94,json_object_single_ad: 587 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
meta-llama/llama-4-maverick
Section titled “meta-llama/llama-4-maverick”- F1 (avg across episodes): 0.470
- Total cost / episode: $0.1508
- p50 / p95 latency: 1.06s / 2.38s
- JSON compliance: 0.81
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_object_no_ads: 315,json_object_single_ad: 540 - Verbosity: 3/855 calls over 1024 output tokens (0.4%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 372
- Extra keys observed: end_text, sponsor
cohere/command-a
Section titled “cohere/command-a”- F1 (avg across episodes): 0.464
- Total cost / episode: $2.6688
- p50 / p95 latency: 3.78s / 11.46s
- JSON compliance: 0.71
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_object_no_ads: 29,json_object_single_ad: 826 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 478
- Extra keys observed: end_text, sponsor
deepseek/deepseek-v4-pro
Section titled “deepseek/deepseek-v4-pro”- F1 (avg across episodes): 0.424
- Total cost / episode: $0.6376
- p50 / p95 latency: 26.42s / 101.25s
- JSON compliance: 0.87
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 2.7%
- Extraction methods:
json_array_direct: 229,json_object_ads_key: 63,json_object_no_ads: 131,json_object_segments_key: 314,json_object_single_ad: 86,json_object_single_ad_truncated: 2,markdown_code_block: 5,parse_failure: 23,regex_json_array: 2 - Verbosity: 433/855 calls over 1024 output tokens (50.6%); 15 hit max_tokens (1.8%); 2 salvaged from truncated JSON (0.2%)
moonshotai/kimi-k2.6
Section titled “moonshotai/kimi-k2.6”- F1 (avg across episodes): 0.422
- Total cost / episode: $2.2593
- p50 / p95 latency: 35.30s / 160.11s
- JSON compliance: 0.57
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 28.0%
- Extraction methods:
json_array_direct: 68,json_object_ads_key: 35,json_object_no_ads: 109,json_object_segments_key: 2,json_object_single_ad: 397,markdown_code_block: 5,parse_failure: 239 - Verbosity: 767/855 calls over 1024 output tokens (89.7%); 113 hit max_tokens (13.2%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 234
- Extra keys observed: end_text, sponsor
deepseek/deepseek-v3.2
Section titled “deepseek/deepseek-v3.2”- F1 (avg across episodes): 0.416
- Total cost / episode: $0.2328
- p50 / p95 latency: 2.67s / 7.32s
- JSON compliance: 0.88
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_array_direct: 501,json_object_ads_key: 16,json_object_no_ads: 3,json_object_single_ad: 335 - Verbosity: 1/855 calls over 1024 output tokens (0.1%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 263
- Extra keys observed: end_text, sponsor
meta-llama/llama-3.3-70b-instruct
Section titled “meta-llama/llama-3.3-70b-instruct”- F1 (avg across episodes): 0.395
- Total cost / episode: $0.1008
- p50 / p95 latency: 1.47s / 4.82s
- JSON compliance: 0.55
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 35.1%
- Extraction methods:
json_array_direct: 143,json_object_ads_key: 1,json_object_no_ads: 144,json_object_single_ad: 264,parse_failure: 300,regex_json_array: 3 - Verbosity: 1/855 calls over 1024 output tokens (0.1%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 378
- Extra keys observed: end_text, sponsor
nvidia/nemotron-nano-9b-v2
Section titled “nvidia/nemotron-nano-9b-v2”- F1 (avg across episodes): 0.316
- Total cost / episode: $0.0813
- p50 / p95 latency: 12.05s / 36.70s
- JSON compliance: 0.92
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 6.5%
- Extraction methods:
json_array_direct: 770,json_object_single_ad_truncated: 15,parse_failure: 56,regex_json_array: 14 - Verbosity: 489/855 calls over 1024 output tokens (57.2%); 11 hit max_tokens (1.3%); 15 salvaged from truncated JSON (1.8%)
- Schema violations: 476
- Extra keys observed: end_text, sponsor
openai/gpt-3.5-turbo
Section titled “openai/gpt-3.5-turbo”- F1 (avg across episodes): 0.315
- Total cost / episode: $0.5091
- p50 / p95 latency: 1.26s / 1.95s
- JSON compliance: 0.71
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.6%
- Extraction methods:
json_object_no_ads: 50,json_object_single_ad: 800,parse_failure: 5 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 593
- Extra keys observed: end_text, sponsor
deepseek/deepseek-r1-distill-llama-70b
Section titled “deepseek/deepseek-r1-distill-llama-70b”- F1 (avg across episodes): 0.261
- Total cost / episode: $0.7331
- p50 / p95 latency: 1.98s / 51.21s
- JSON compliance: 0.74
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 1.8%
- Extraction methods:
json_array_direct: 20,json_object_ads_key: 68,json_object_no_ads: 104,json_object_single_ad: 642,json_object_single_ad_truncated: 5,parse_failure: 15,regex_json_array: 1 - Verbosity: 57/855 calls over 1024 output tokens (6.7%); 17 hit max_tokens (2.0%); 5 salvaged from truncated JSON (0.6%)
- Schema violations: 474
- Extra keys observed: end_text, sponsor
qwen/qwen3-14b
Section titled “qwen/qwen3-14b”- F1 (avg across episodes): 0.260
- Total cost / episode: $0.1261
- p50 / p95 latency: 20.91s / 63.42s
- JSON compliance: 0.28
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 60.4%
- Extraction methods:
json_object_no_ads: 1,json_object_single_ad: 338,parse_failure: 516 - Verbosity: 91/855 calls over 1024 output tokens (10.6%); 10 hit max_tokens (1.2%); 0 salvaged from truncated JSON (0.0%)
meta-llama/llama-3.1-8b-instruct
Section titled “meta-llama/llama-3.1-8b-instruct”- F1 (avg across episodes): 0.251
- Total cost / episode: $0.0207
- p50 / p95 latency: 0.79s / 4.04s
- JSON compliance: 0.85
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.1%
- Extraction methods:
json_array_direct: 371,json_object_no_ads: 66,json_object_single_ad: 417,parse_failure: 1 - Verbosity: 26/855 calls over 1024 output tokens (3.0%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 1270
- Extra keys observed: end_text, sponsor
cohere/command-r-plus-08-2024
Section titled “cohere/command-r-plus-08-2024”- F1 (avg across episodes): 0.162
- Total cost / episode: $2.5787
- p50 / p95 latency: 0.95s / 3.45s
- JSON compliance: 0.98
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 0.0%
- Extraction methods:
json_object_ads_key: 27,json_object_no_ads: 783,json_object_single_ad: 45 - Verbosity: 0/855 calls over 1024 output tokens (0.0%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 132
- Extra keys observed: end_text, sponsor
microsoft/phi-4
Section titled “microsoft/phi-4”- F1 (avg across episodes): 0.157
- Total cost / episode: $0.0713
- p50 / p95 latency: 2.29s / 11.55s
- JSON compliance: 0.86
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 1.1%
- Extraction methods:
json_array_direct: 421,json_object_ads_key: 31,json_object_no_ads: 27,json_object_segments_key: 20,json_object_single_ad: 335,json_object_window_segments: 2,parse_failure: 9,regex_json_array: 10 - Verbosity: 19/855 calls over 1024 output tokens (2.2%); 12 hit max_tokens (1.4%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 412
- Extra keys observed: end_text, sponsor
openai/o4-mini
Section titled “openai/o4-mini”- F1 (avg across episodes): 0.075
- Total cost / episode: $1.8999
- p50 / p95 latency: 6.95s / 25.84s
- JSON compliance: 0.05
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 93.9%
- Extraction methods:
json_object_no_ads: 19,json_object_single_ad: 33,parse_failure: 803 - Verbosity: 340/855 calls over 1024 output tokens (39.8%); 12 hit max_tokens (1.4%); 0 salvaged from truncated JSON (0.0%)
- Schema violations: 28
- Extra keys observed: end_text, sponsor
qwen/qwen3-8b
Section titled “qwen/qwen3-8b”- F1 (avg across episodes): 0.005
- Total cost / episode: $0.2578
- p50 / p95 latency: 59.45s / 144.22s
- JSON compliance: 0.01
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 97.4%
- Extraction methods:
bracket_fallback: 18,json_array_direct: 4,parse_failure: 833 - Verbosity: 588/855 calls over 1024 output tokens (68.8%); 119 hit max_tokens (13.9%); 0 salvaged from truncated JSON (0.0%)
mistralai/mistral-7b-instruct-v0.1
Section titled “mistralai/mistral-7b-instruct-v0.1”- F1 (avg across episodes): 0.000
- Total cost / episode: $0.0000
- p50 / p95 latency: 7.11s / 33.05s
- JSON compliance: 0.16
- JSON mode: native (100% native, 855 calls)
- Parse failure rate: 59.5%
- Extraction methods:
bracket_fallback: 1,parse_failure: 509,regex_json_array: 345 - Verbosity: 15/855 calls over 1024 output tokens (1.8%); 0 hit max_tokens (0.0%); 0 salvaged from truncated JSON (0.0%)
Per-Episode Detail
Section titled “Per-Episode Detail”One subsection per episode in the corpus, showing how every model performed on that specific episode. For ad-bearing episodes you see F1 and the stdev across trials (low stdev means stable, high stdev means the model’s number on this episode is noisy). For the no-ad episode you see PASS / FAIL on the negative control: PASS = zero false positives across all windows, FAIL = the model flagged something that wasn’t an ad, with the count.
ep-ai-cloud-essentials-e8dc897fbd6b: How Physical AI is Streamlining Engineering
Section titled “ep-ai-cloud-essentials-e8dc897fbd6b: How Physical AI is Streamlining Engineering”- Podcast: ai-cloud-essentials
- Duration: 16.4 min
- Truth: no-ads episode
| Model | Result | FP count |
|---|---|---|
claude-haiku-4-5-20251001 |
PASS | 0 |
claude-opus-4-7 |
PASS | 0 |
claude-opus-4-8 |
PASS | 0 |
claude-sonnet-4-6 |
PASS | 0 |
cohere/command-r-plus-08-2024 |
PASS | 0 |
deepseek/deepseek-v3.2 |
PASS | 0 |
deepseek/deepseek-v4-pro |
PASS | 0 |
google/gemini-2.5-flash |
PASS | 0 |
google/gemini-3.5-flash |
PASS | 0 |
meta-llama/llama-3.1-8b-instruct |
PASS | 0 |
meta-llama/llama-3.3-70b-instruct |
PASS | 0 |
meta-llama/llama-4-scout |
PASS | 0 |
minimax/minimax-m3 |
PASS | 0 |
mistralai/codestral-2508 |
PASS | 0 |
mistralai/mistral-7b-instruct-v0.1 |
PASS | 0 |
mistralai/mistral-large-2512 |
PASS | 0 |
mistralai/mistral-medium-3.1 |
PASS | 0 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
PASS | 0 |
openai/o3 |
PASS | 0 |
openai/o4-mini |
PASS | 0 |
qwen/qwen3-14b |
PASS | 0 |
qwen/qwen3-8b |
PASS | 0 |
qwen/qwen3.5-27b |
PASS | 0 |
qwen/qwen3.5-plus-02-15 |
PASS | 0 |
qwen/qwen3.6-plus |
PASS | 0 |
x-ai/grok-4.3 |
PASS | 0 |
deepseek/deepseek-r1 |
FAIL | 1 |
deepseek/deepseek-v4-flash |
FAIL | 1 |
google/gemini-2.5-flash-lite |
FAIL | 1 |
google/gemini-2.5-pro |
FAIL | 1 |
google/gemini-3.1-flash-lite |
FAIL | 1 |
google/gemma-4-31b-it |
FAIL | 1 |
meta-llama/llama-4-maverick |
FAIL | 1 |
moonshotai/kimi-k2.6 |
FAIL | 1 |
nvidia/nemotron-nano-9b-v2 |
FAIL | 1 |
openai/gpt-5.4 |
FAIL | 1 |
openai/gpt-5.4-mini |
FAIL | 1 |
openai/gpt-5.5 |
FAIL | 1 |
openai/gpt-oss-120b |
FAIL | 1 |
qwen/qwen3.6-flash |
FAIL | 1 |
deepseek/deepseek-r1-distill-llama-70b |
FAIL | 2 |
qwen/qwen3-235b-a22b-2507 |
FAIL | 2 |
cohere/command-a |
FAIL | 3 |
microsoft/phi-4 |
FAIL | 3 |
openai/gpt-3.5-turbo |
FAIL | 3 |
deepseek/deepseek-r1-0528 |
FAIL | 27 |
ep-crime-junkie-8ce498f299d7: MISSING: Christopher “Cole” Thomas
Section titled “ep-crime-junkie-8ce498f299d7: MISSING: Christopher “Cole” Thomas”- Podcast: crime-junkie
- Duration: 48.2 min
- Truth ads: 4
| Model | F1 | F1 stdev |
|---|---|---|
claude-haiku-4-5-20251001 |
1.000 | 0.000 |
claude-sonnet-4-6 |
1.000 | 0.000 |
google/gemini-2.5-flash |
1.000 | 0.000 |
google/gemini-2.5-flash-lite |
1.000 | 0.000 |
google/gemini-3.1-flash-lite |
1.000 | 0.000 |
google/gemma-4-31b-it |
1.000 | 0.000 |
meta-llama/llama-4-maverick |
1.000 | 0.000 |
openai/gpt-3.5-turbo |
1.000 | 0.000 |
openai/gpt-5.4 |
1.000 | 0.000 |
qwen/qwen3.5-plus-02-15 |
1.000 | 0.000 |
qwen/qwen3.6-flash |
1.000 | 0.000 |
qwen/qwen3.6-plus |
1.000 | 0.000 |
x-ai/grok-4.3 |
1.000 | 0.000 |
deepseek/deepseek-r1 |
0.971 | 0.064 |
google/gemini-2.5-pro |
0.971 | 0.064 |
minimax/minimax-m3 |
0.971 | 0.064 |
mistralai/codestral-2508 |
0.950 | 0.112 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.943 | 0.078 |
openai/gpt-5.5 |
0.943 | 0.078 |
google/gemini-3.5-flash |
0.914 | 0.078 |
qwen/qwen3.5-27b |
0.914 | 0.078 |
cohere/command-a |
0.911 | 0.050 |
openai/gpt-5.4-mini |
0.906 | 0.103 |
claude-opus-4-8 |
0.886 | 0.064 |
mistralai/mistral-medium-3.1 |
0.876 | 0.137 |
openai/gpt-oss-120b |
0.876 | 0.137 |
openai/o3 |
0.876 | 0.137 |
deepseek/deepseek-v4-flash |
0.864 | 0.089 |
claude-opus-4-7 |
0.857 | 0.000 |
deepseek/deepseek-v4-pro |
0.819 | 0.085 |
qwen/qwen3-235b-a22b-2507 |
0.813 | 0.119 |
deepseek/deepseek-r1-0528 |
0.787 | 0.197 |
mistralai/mistral-large-2512 |
0.733 | 0.149 |
meta-llama/llama-3.3-70b-instruct |
0.702 | 0.259 |
deepseek/deepseek-v3.2 |
0.686 | 0.104 |
microsoft/phi-4 |
0.562 | 0.136 |
deepseek/deepseek-r1-distill-llama-70b |
0.547 | 0.268 |
moonshotai/kimi-k2.6 |
0.547 | 0.203 |
nvidia/nemotron-nano-9b-v2 |
0.450 | 0.201 |
meta-llama/llama-4-scout |
0.358 | 0.203 |
qwen/qwen3-14b |
0.190 | 0.294 |
meta-llama/llama-3.1-8b-instruct |
0.168 | 0.159 |
cohere/command-r-plus-08-2024 |
0.000 | 0.000 |
mistralai/mistral-7b-instruct-v0.1 |
0.000 | 0.000 |
openai/o4-mini |
0.000 | 0.000 |
qwen/qwen3-8b |
0.000 | 0.000 |
ep-daily-gist-chicago-70a82fe93a5c: Suburban apartment market heats up
Section titled “ep-daily-gist-chicago-70a82fe93a5c: Suburban apartment market heats up”- Podcast: daily-gist-chicago
- Duration: 21.2 min
- Truth ads: 2
| Model | F1 | F1 stdev |
|---|---|---|
claude-haiku-4-5-20251001 |
1.000 | 0.000 |
google/gemini-2.5-flash |
1.000 | 0.000 |
google/gemini-3.1-flash-lite |
1.000 | 0.000 |
qwen/qwen3-235b-a22b-2507 |
0.880 | 0.110 |
openai/gpt-5.4-mini |
0.833 | 0.236 |
claude-sonnet-4-6 |
0.800 | 0.183 |
qwen/qwen3.6-flash |
0.800 | 0.274 |
meta-llama/llama-3.1-8b-instruct |
0.700 | 0.183 |
mistralai/codestral-2508 |
0.667 | 0.000 |
mistralai/mistral-medium-3.1 |
0.667 | 0.000 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.667 | 0.000 |
qwen/qwen3.5-27b |
0.667 | 0.204 |
qwen/qwen3.6-plus |
0.667 | 0.000 |
deepseek/deepseek-r1-0528 |
0.647 | 0.228 |
deepseek/deepseek-r1 |
0.633 | 0.217 |
meta-llama/llama-4-scout |
0.627 | 0.376 |
minimax/minimax-m3 |
0.600 | 0.224 |
nvidia/nemotron-nano-9b-v2 |
0.600 | 0.365 |
openai/gpt-oss-120b |
0.600 | 0.365 |
qwen/qwen3.5-plus-02-15 |
0.600 | 0.091 |
x-ai/grok-4.3 |
0.533 | 0.075 |
deepseek/deepseek-v4-flash |
0.527 | 0.313 |
claude-opus-4-8 |
0.500 | 0.000 |
google/gemini-2.5-flash-lite |
0.500 | 0.000 |
google/gemini-2.5-pro |
0.500 | 0.000 |
google/gemini-3.5-flash |
0.500 | 0.000 |
openai/gpt-5.4 |
0.500 | 0.000 |
openai/gpt-5.5 |
0.500 | 0.000 |
google/gemma-4-31b-it |
0.480 | 0.045 |
deepseek/deepseek-r1-distill-llama-70b |
0.453 | 0.307 |
mistralai/mistral-large-2512 |
0.427 | 0.072 |
openai/gpt-3.5-turbo |
0.420 | 0.045 |
cohere/command-a |
0.400 | 0.000 |
deepseek/deepseek-v3.2 |
0.300 | 0.274 |
claude-opus-4-7 |
0.200 | 0.274 |
deepseek/deepseek-v4-pro |
0.133 | 0.298 |
meta-llama/llama-3.3-70b-instruct |
0.100 | 0.224 |
moonshotai/kimi-k2.6 |
0.100 | 0.224 |
cohere/command-r-plus-08-2024 |
0.000 | 0.000 |
meta-llama/llama-4-maverick |
0.000 | 0.000 |
microsoft/phi-4 |
0.000 | 0.000 |
mistralai/mistral-7b-instruct-v0.1 |
0.000 | 0.000 |
openai/o3 |
0.000 | 0.000 |
openai/o4-mini |
0.000 | 0.000 |
qwen/qwen3-14b |
0.000 | 0.000 |
qwen/qwen3-8b |
0.000 | 0.000 |
ep-daily-tech-news-show-b576979e1fe8: Motorola Razr Fold is a Noble Competitor to the Galaxy Z Fold 7 - DTNS 5269
Section titled “ep-daily-tech-news-show-b576979e1fe8: Motorola Razr Fold is a Noble Competitor to the Galaxy Z Fold 7 - DTNS 5269”- Podcast: daily-tech-news-show
- Duration: 34.6 min
- Truth ads: 4
| Model | F1 | F1 stdev |
|---|---|---|
claude-haiku-4-5-20251001 |
1.000 | 0.000 |
claude-sonnet-4-6 |
1.000 | 0.000 |
google/gemini-2.5-flash |
1.000 | 0.000 |
mistralai/mistral-large-2512 |
0.978 | 0.050 |
google/gemini-3.1-flash-lite |
0.971 | 0.064 |
x-ai/grok-4.3 |
0.971 | 0.064 |
minimax/minimax-m3 |
0.943 | 0.078 |
openai/gpt-5.4-mini |
0.943 | 0.078 |
qwen/qwen3.6-flash |
0.943 | 0.078 |
deepseek/deepseek-v4-flash |
0.933 | 0.061 |
deepseek/deepseek-r1 |
0.914 | 0.078 |
moonshotai/kimi-k2.6 |
0.914 | 0.078 |
qwen/qwen3.6-plus |
0.914 | 0.078 |
deepseek/deepseek-r1-0528 |
0.911 | 0.145 |
openai/gpt-5.4 |
0.892 | 0.062 |
claude-opus-4-7 |
0.886 | 0.064 |
claude-opus-4-8 |
0.886 | 0.064 |
openai/gpt-5.5 |
0.886 | 0.064 |
google/gemini-2.5-pro |
0.864 | 0.089 |
google/gemini-3.5-flash |
0.857 | 0.000 |
qwen/qwen3.5-plus-02-15 |
0.857 | 0.000 |
google/gemma-4-31b-it |
0.850 | 0.137 |
openai/o3 |
0.848 | 0.119 |
qwen/qwen3-235b-a22b-2507 |
0.822 | 0.149 |
google/gemini-2.5-flash-lite |
0.821 | 0.110 |
mistralai/mistral-medium-3.1 |
0.821 | 0.066 |
meta-llama/llama-4-maverick |
0.771 | 0.048 |
qwen/qwen3.5-27b |
0.743 | 0.104 |
mistralai/codestral-2508 |
0.698 | 0.079 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.648 | 0.043 |
deepseek/deepseek-v3.2 |
0.622 | 0.153 |
meta-llama/llama-4-scout |
0.592 | 0.243 |
qwen/qwen3-14b |
0.518 | 0.332 |
openai/gpt-oss-120b |
0.507 | 0.164 |
deepseek/deepseek-v4-pro |
0.507 | 0.146 |
cohere/command-a |
0.500 | 0.000 |
meta-llama/llama-3.3-70b-instruct |
0.420 | 0.045 |
nvidia/nemotron-nano-9b-v2 |
0.274 | 0.194 |
meta-llama/llama-3.1-8b-instruct |
0.231 | 0.132 |
openai/gpt-3.5-turbo |
0.222 | 0.000 |
microsoft/phi-4 |
0.160 | 0.219 |
openai/o4-mini |
0.147 | 0.202 |
deepseek/deepseek-r1-distill-llama-70b |
0.067 | 0.149 |
cohere/command-r-plus-08-2024 |
0.000 | 0.000 |
mistralai/mistral-7b-instruct-v0.1 |
0.000 | 0.000 |
qwen/qwen3-8b |
0.000 | 0.000 |
ep-daily-tech-news-show-c1904b8605f7: Switch 2 Prices Rise, Forecast Drops - DTNS 5265
Section titled “ep-daily-tech-news-show-c1904b8605f7: Switch 2 Prices Rise, Forecast Drops - DTNS 5265”- Podcast: daily-tech-news-show
- Duration: 38.6 min
- Truth ads: 5
| Model | F1 | F1 stdev |
|---|---|---|
qwen/qwen3.5-plus-02-15 |
0.653 | 0.030 |
qwen/qwen3.6-flash |
0.653 | 0.030 |
openai/gpt-5.5 |
0.633 | 0.075 |
claude-sonnet-4-6 |
0.627 | 0.037 |
google/gemini-3.1-flash-lite |
0.600 | 0.000 |
google/gemini-3.5-flash |
0.600 | 0.000 |
google/gemma-4-31b-it |
0.600 | 0.000 |
qwen/qwen3.6-plus |
0.600 | 0.000 |
moonshotai/kimi-k2.6 |
0.600 | 0.091 |
claude-opus-4-8 |
0.589 | 0.024 |
qwen/qwen3.5-27b |
0.582 | 0.082 |
google/gemini-2.5-pro |
0.578 | 0.030 |
minimax/minimax-m3 |
0.569 | 0.045 |
deepseek/deepseek-v4-flash |
0.569 | 0.070 |
openai/gpt-5.4 |
0.567 | 0.091 |
mistralai/mistral-medium-3.1 |
0.556 | 0.024 |
mistralai/codestral-2508 |
0.551 | 0.187 |
x-ai/grok-4.3 |
0.547 | 0.064 |
google/gemini-2.5-flash |
0.545 | 0.000 |
mistralai/mistral-large-2512 |
0.545 | 0.000 |
openai/gpt-oss-120b |
0.545 | 0.076 |
openai/gpt-5.4-mini |
0.524 | 0.157 |
deepseek/deepseek-r1 |
0.507 | 0.082 |
google/gemini-2.5-flash-lite |
0.489 | 0.083 |
openai/o3 |
0.486 | 0.166 |
openai/gpt-3.5-turbo |
0.444 | 0.000 |
meta-llama/llama-4-scout |
0.432 | 0.133 |
deepseek/deepseek-r1-0528 |
0.417 | 0.107 |
deepseek/deepseek-v3.2 |
0.396 | 0.120 |
cohere/command-r-plus-08-2024 |
0.384 | 0.154 |
deepseek/deepseek-v4-pro |
0.381 | 0.241 |
claude-haiku-4-5-20251001 |
0.378 | 0.020 |
claude-opus-4-7 |
0.378 | 0.119 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.364 | 0.250 |
cohere/command-a |
0.356 | 0.122 |
qwen/qwen3-235b-a22b-2507 |
0.308 | 0.106 |
deepseek/deepseek-r1-distill-llama-70b |
0.228 | 0.012 |
meta-llama/llama-4-maverick |
0.228 | 0.012 |
microsoft/phi-4 |
0.144 | 0.221 |
meta-llama/llama-3.3-70b-instruct |
0.129 | 0.118 |
nvidia/nemotron-nano-9b-v2 |
0.124 | 0.124 |
qwen/qwen3-14b |
0.114 | 0.256 |
meta-llama/llama-3.1-8b-instruct |
0.084 | 0.116 |
openai/o4-mini |
0.067 | 0.149 |
mistralai/mistral-7b-instruct-v0.1 |
0.000 | 0.000 |
qwen/qwen3-8b |
0.000 | 0.000 |
ep-drink-champs-30c9a2d49f13: Episode 501 w/ Warren Sapp
Section titled “ep-drink-champs-30c9a2d49f13: Episode 501 w/ Warren Sapp”- Podcast: drink-champs
- Duration: 258.6 min
- Truth ads: 9
| Model | F1 | F1 stdev |
|---|---|---|
claude-haiku-4-5-20251001 |
1.000 | 0.000 |
x-ai/grok-4.3 |
0.946 | 0.065 |
claude-sonnet-4-6 |
0.938 | 0.021 |
claude-opus-4-8 |
0.916 | 0.037 |
qwen/qwen3.6-plus |
0.867 | 0.025 |
google/gemini-2.5-flash |
0.857 | 0.000 |
qwen/qwen3.5-plus-02-15 |
0.842 | 0.000 |
google/gemini-2.5-pro |
0.821 | 0.030 |
qwen/qwen3.6-flash |
0.804 | 0.092 |
google/gemini-3.1-flash-lite |
0.803 | 0.024 |
openai/o3 |
0.789 | 0.133 |
openai/gpt-5.5 |
0.766 | 0.149 |
google/gemma-4-31b-it |
0.723 | 0.144 |
minimax/minimax-m3 |
0.705 | 0.094 |
google/gemini-2.5-flash-lite |
0.698 | 0.086 |
deepseek/deepseek-r1 |
0.679 | 0.086 |
openai/gpt-5.4 |
0.676 | 0.106 |
qwen/qwen3.5-27b |
0.675 | 0.102 |
openai/gpt-5.4-mini |
0.595 | 0.087 |
mistralai/mistral-large-2512 |
0.574 | 0.090 |
google/gemini-3.5-flash |
0.562 | 0.015 |
mistralai/mistral-medium-3.1 |
0.550 | 0.064 |
deepseek/deepseek-v4-flash |
0.532 | 0.102 |
deepseek/deepseek-v4-pro |
0.420 | 0.039 |
claude-opus-4-7 |
0.393 | 0.050 |
mistralai/codestral-2508 |
0.343 | 0.119 |
cohere/command-r-plus-08-2024 |
0.330 | 0.191 |
meta-llama/llama-4-maverick |
0.316 | 0.000 |
deepseek/deepseek-v3.2 |
0.301 | 0.056 |
deepseek/deepseek-r1-0528 |
0.260 | 0.104 |
openai/gpt-oss-120b |
0.247 | 0.086 |
meta-llama/llama-3.1-8b-instruct |
0.224 | 0.056 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.208 | 0.093 |
qwen/qwen3-235b-a22b-2507 |
0.185 | 0.131 |
nvidia/nemotron-nano-9b-v2 |
0.156 | 0.026 |
meta-llama/llama-4-scout |
0.147 | 0.048 |
microsoft/phi-4 |
0.059 | 0.081 |
moonshotai/kimi-k2.6 |
0.054 | 0.075 |
qwen/qwen3-14b |
0.047 | 0.065 |
openai/gpt-3.5-turbo |
0.040 | 0.037 |
openai/o4-mini |
0.040 | 0.089 |
cohere/command-a |
0.034 | 0.047 |
meta-llama/llama-3.3-70b-instruct |
0.024 | 0.053 |
deepseek/deepseek-r1-distill-llama-70b |
0.000 | 0.000 |
mistralai/mistral-7b-instruct-v0.1 |
0.000 | 0.000 |
qwen/qwen3-8b |
0.000 | 0.000 |
ep-glt1412515089-373d5ba5007b: #2496 - Julia Mossbridge
Section titled “ep-glt1412515089-373d5ba5007b: #2496 - Julia Mossbridge”- Podcast: glt1412515089
- Duration: 165.3 min
- Truth ads: 4
| Model | F1 | F1 stdev |
|---|---|---|
openai/gpt-oss-120b |
1.000 | 0.000 |
google/gemini-2.5-pro |
0.956 | 0.061 |
google/gemma-4-31b-it |
0.950 | 0.112 |
google/gemini-3.5-flash |
0.943 | 0.078 |
deepseek/deepseek-r1 |
0.911 | 0.050 |
deepseek/deepseek-v4-flash |
0.901 | 0.112 |
minimax/minimax-m3 |
0.892 | 0.062 |
google/gemini-2.5-flash |
0.889 | 0.000 |
openai/gpt-5.5 |
0.886 | 0.186 |
qwen/qwen3.5-plus-02-15 |
0.886 | 0.064 |
mistralai/mistral-medium-3.1 |
0.883 | 0.089 |
x-ai/grok-4.3 |
0.864 | 0.196 |
claude-opus-4-7 |
0.857 | 0.000 |
claude-opus-4-8 |
0.857 | 0.000 |
qwen/qwen3.6-plus |
0.857 | 0.000 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.810 | 0.143 |
meta-llama/llama-3.3-70b-instruct |
0.771 | 0.048 |
google/gemini-3.1-flash-lite |
0.771 | 0.040 |
qwen/qwen3.5-27b |
0.757 | 0.117 |
cohere/command-a |
0.744 | 0.057 |
openai/o3 |
0.743 | 0.104 |
claude-haiku-4-5-20251001 |
0.727 | 0.000 |
meta-llama/llama-4-maverick |
0.703 | 0.033 |
qwen/qwen3.6-flash |
0.700 | 0.046 |
qwen/qwen3-235b-a22b-2507 |
0.689 | 0.101 |
meta-llama/llama-4-scout |
0.679 | 0.202 |
openai/gpt-5.4-mini |
0.645 | 0.052 |
openai/gpt-5.4 |
0.641 | 0.070 |
google/gemini-2.5-flash-lite |
0.599 | 0.042 |
deepseek/deepseek-v3.2 |
0.584 | 0.088 |
claude-sonnet-4-6 |
0.571 | 0.000 |
deepseek/deepseek-r1-0528 |
0.558 | 0.044 |
moonshotai/kimi-k2.6 |
0.532 | 0.031 |
qwen/qwen3-14b |
0.478 | 0.179 |
deepseek/deepseek-v4-pro |
0.477 | 0.164 |
mistralai/mistral-large-2512 |
0.368 | 0.097 |
deepseek/deepseek-r1-distill-llama-70b |
0.333 | 0.039 |
mistralai/codestral-2508 |
0.303 | 0.142 |
openai/gpt-3.5-turbo |
0.291 | 0.008 |
meta-llama/llama-3.1-8b-instruct |
0.286 | 0.202 |
nvidia/nemotron-nano-9b-v2 |
0.212 | 0.160 |
openai/o4-mini |
0.080 | 0.179 |
cohere/command-r-plus-08-2024 |
0.000 | 0.000 |
microsoft/phi-4 |
0.000 | 0.000 |
mistralai/mistral-7b-instruct-v0.1 |
0.000 | 0.000 |
qwen/qwen3-8b |
0.000 | 0.000 |
ep-it-s-a-thing-e339179dfad6: SOUP shots - It’s a Thing 418
Section titled “ep-it-s-a-thing-e339179dfad6: SOUP shots - It’s a Thing 418”- Podcast: it-s-a-thing
- Duration: 26.7 min
- Truth ads: 1
| Model | F1 | F1 stdev |
|---|---|---|
meta-llama/llama-4-scout |
0.800 | 0.183 |
deepseek/deepseek-v4-flash |
0.733 | 0.149 |
claude-haiku-4-5-20251001 |
0.667 | 0.000 |
claude-opus-4-7 |
0.667 | 0.000 |
claude-opus-4-8 |
0.667 | 0.000 |
claude-sonnet-4-6 |
0.667 | 0.000 |
google/gemini-2.5-pro |
0.667 | 0.000 |
google/gemini-3.5-flash |
0.667 | 0.000 |
google/gemma-4-31b-it |
0.667 | 0.000 |
minimax/minimax-m3 |
0.667 | 0.000 |
mistralai/mistral-medium-3.1 |
0.667 | 0.000 |
openai/gpt-5.5 |
0.667 | 0.000 |
qwen/qwen3.5-plus-02-15 |
0.667 | 0.000 |
qwen/qwen3.6-flash |
0.667 | 0.000 |
qwen/qwen3.6-plus |
0.667 | 0.000 |
x-ai/grok-4.3 |
0.667 | 0.000 |
openai/gpt-5.4 |
0.613 | 0.119 |
qwen/qwen3.5-27b |
0.600 | 0.365 |
google/gemini-3.1-flash-lite |
0.567 | 0.091 |
mistralai/mistral-large-2512 |
0.513 | 0.152 |
openai/gpt-5.4-mini |
0.500 | 0.289 |
deepseek/deepseek-r1 |
0.467 | 0.274 |
openai/gpt-oss-120b |
0.440 | 0.055 |
mistralai/codestral-2508 |
0.420 | 0.045 |
deepseek/deepseek-r1-0528 |
0.404 | 0.281 |
cohere/command-a |
0.400 | 0.000 |
deepseek/deepseek-v3.2 |
0.400 | 0.548 |
google/gemini-2.5-flash |
0.400 | 0.000 |
meta-llama/llama-3.1-8b-instruct |
0.400 | 0.548 |
openai/o3 |
0.333 | 0.471 |
nvidia/nemotron-nano-9b-v2 |
0.313 | 0.301 |
deepseek/deepseek-v4-pro |
0.267 | 0.365 |
meta-llama/llama-3.3-70b-instruct |
0.267 | 0.365 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.267 | 0.365 |
google/gemini-2.5-flash-lite |
0.261 | 0.153 |
cohere/command-r-plus-08-2024 |
0.200 | 0.447 |
moonshotai/kimi-k2.6 |
0.200 | 0.274 |
deepseek/deepseek-r1-distill-llama-70b |
0.000 | 0.000 |
meta-llama/llama-4-maverick |
0.000 | 0.000 |
microsoft/phi-4 |
0.000 | 0.000 |
mistralai/mistral-7b-instruct-v0.1 |
0.000 | 0.000 |
openai/gpt-3.5-turbo |
0.000 | 0.000 |
openai/o4-mini |
0.000 | 0.000 |
qwen/qwen3-14b |
0.000 | 0.000 |
qwen/qwen3-235b-a22b-2507 |
0.000 | 0.000 |
qwen/qwen3-8b |
0.000 | 0.000 |
ep-on-air-with-dan-and-alex2-574e4f303730: Ryanair Wants Alcohol Bans, Emirates’ $6.8B Record Profit & Buying Spirit Airlines?!
Section titled “ep-on-air-with-dan-and-alex2-574e4f303730: Ryanair Wants Alcohol Bans, Emirates’ $6.8B Record Profit & Buying Spirit Airlines?!”- Podcast: on-air-with-dan-and-alex2
- Duration: 58.1 min
- Truth ads: 2
| Model | F1 | F1 stdev |
|---|---|---|
claude-haiku-4-5-20251001 |
1.000 | 0.000 |
google/gemma-4-31b-it |
1.000 | 0.000 |
mistralai/mistral-medium-3.1 |
1.000 | 0.000 |
qwen/qwen3.6-plus |
0.960 | 0.089 |
openai/gpt-5.4 |
0.920 | 0.110 |
meta-llama/llama-4-scout |
0.880 | 0.110 |
qwen/qwen3.6-flash |
0.880 | 0.110 |
moonshotai/kimi-k2.6 |
0.867 | 0.183 |
x-ai/grok-4.3 |
0.840 | 0.089 |
claude-opus-4-7 |
0.800 | 0.000 |
claude-opus-4-8 |
0.800 | 0.000 |
claude-sonnet-4-6 |
0.800 | 0.000 |
google/gemini-2.5-flash |
0.800 | 0.000 |
google/gemini-2.5-flash-lite |
0.800 | 0.000 |
google/gemini-3.1-flash-lite |
0.800 | 0.000 |
google/gemini-3.5-flash |
0.800 | 0.000 |
meta-llama/llama-4-maverick |
0.800 | 0.000 |
minimax/minimax-m3 |
0.800 | 0.000 |
mistralai/mistral-large-2512 |
0.800 | 0.000 |
openai/gpt-5.4-mini |
0.800 | 0.000 |
openai/gpt-5.5 |
0.800 | 0.000 |
qwen/qwen3.5-plus-02-15 |
0.800 | 0.000 |
deepseek/deepseek-r1 |
0.787 | 0.137 |
deepseek/deepseek-v4-flash |
0.773 | 0.060 |
openai/o3 |
0.760 | 0.146 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.753 | 0.185 |
qwen/qwen3.5-27b |
0.740 | 0.134 |
google/gemini-2.5-pro |
0.720 | 0.073 |
openai/gpt-oss-120b |
0.720 | 0.073 |
qwen/qwen3-235b-a22b-2507 |
0.701 | 0.098 |
deepseek/deepseek-r1-0528 |
0.693 | 0.174 |
mistralai/codestral-2508 |
0.693 | 0.060 |
cohere/command-a |
0.674 | 0.081 |
openai/gpt-3.5-turbo |
0.500 | 0.000 |
nvidia/nemotron-nano-9b-v2 |
0.440 | 0.055 |
deepseek/deepseek-v3.2 |
0.400 | 0.365 |
microsoft/phi-4 |
0.400 | 0.365 |
deepseek/deepseek-r1-distill-llama-70b |
0.397 | 0.076 |
meta-llama/llama-3.1-8b-instruct |
0.367 | 0.217 |
qwen/qwen3-14b |
0.360 | 0.239 |
deepseek/deepseek-v4-pro |
0.280 | 0.438 |
meta-llama/llama-3.3-70b-instruct |
0.133 | 0.298 |
openai/o4-mini |
0.133 | 0.298 |
cohere/command-r-plus-08-2024 |
0.000 | 0.000 |
mistralai/mistral-7b-instruct-v0.1 |
0.000 | 0.000 |
qwen/qwen3-8b |
0.000 | 0.000 |
ep-oxide-and-friends-ce789ff5b62e: Mechanical Engineering at Oxide [chapter images]
Section titled “ep-oxide-and-friends-ce789ff5b62e: Mechanical Engineering at Oxide [chapter images]”- Podcast: oxide-and-friends
- Duration: 84.5 min
- Truth: no-ads episode
| Model | Result | FP count |
|---|---|---|
claude-haiku-4-5-20251001 |
PASS | 0 |
claude-opus-4-7 |
PASS | 0 |
claude-opus-4-8 |
PASS | 0 |
claude-sonnet-4-6 |
PASS | 0 |
cohere/command-a |
PASS | 0 |
cohere/command-r-plus-08-2024 |
PASS | 0 |
deepseek/deepseek-v4-flash |
PASS | 0 |
deepseek/deepseek-v4-pro |
PASS | 0 |
google/gemini-2.5-flash |
PASS | 0 |
google/gemini-2.5-flash-lite |
PASS | 0 |
google/gemini-3.1-flash-lite |
PASS | 0 |
google/gemini-3.5-flash |
PASS | 0 |
google/gemma-4-31b-it |
PASS | 0 |
meta-llama/llama-3.1-8b-instruct |
PASS | 0 |
meta-llama/llama-3.3-70b-instruct |
PASS | 0 |
meta-llama/llama-4-maverick |
PASS | 0 |
meta-llama/llama-4-scout |
PASS | 0 |
minimax/minimax-m3 |
PASS | 0 |
mistralai/codestral-2508 |
PASS | 0 |
mistralai/mistral-7b-instruct-v0.1 |
PASS | 0 |
mistralai/mistral-large-2512 |
PASS | 0 |
mistralai/mistral-medium-3.1 |
PASS | 0 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
PASS | 0 |
nvidia/nemotron-nano-9b-v2 |
PASS | 0 |
openai/gpt-5.5 |
PASS | 0 |
openai/gpt-oss-120b |
PASS | 0 |
openai/o3 |
PASS | 0 |
openai/o4-mini |
PASS | 0 |
qwen/qwen3-8b |
PASS | 0 |
qwen/qwen3.5-27b |
PASS | 0 |
qwen/qwen3.5-plus-02-15 |
PASS | 0 |
qwen/qwen3.6-flash |
PASS | 0 |
qwen/qwen3.6-plus |
PASS | 0 |
x-ai/grok-4.3 |
PASS | 0 |
deepseek/deepseek-r1 |
FAIL | 1 |
google/gemini-2.5-pro |
FAIL | 1 |
openai/gpt-5.4 |
FAIL | 1 |
openai/gpt-5.4-mini |
FAIL | 1 |
qwen/qwen3-14b |
FAIL | 1 |
deepseek/deepseek-v3.2 |
FAIL | 2 |
moonshotai/kimi-k2.6 |
FAIL | 4 |
qwen/qwen3-235b-a22b-2507 |
FAIL | 6 |
deepseek/deepseek-r1-distill-llama-70b |
FAIL | 10 |
openai/gpt-3.5-turbo |
FAIL | 10 |
deepseek/deepseek-r1-0528 |
FAIL | 12 |
microsoft/phi-4 |
FAIL | 15 |
ep-security-now-audio-2850b24903b2: SN 1077: A Browser AI API? - End of Bug Bounties?
Section titled “ep-security-now-audio-2850b24903b2: SN 1077: A Browser AI API? - End of Bug Bounties?”- Podcast: security-now-audio
- Duration: 156.2 min
- Truth ads: 6
| Model | F1 | F1 stdev |
|---|---|---|
claude-haiku-4-5-20251001 |
0.857 | 0.000 |
claude-opus-4-8 |
0.796 | 0.092 |
claude-opus-4-7 |
0.771 | 0.078 |
qwen/qwen3.6-flash |
0.771 | 0.078 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.749 | 0.046 |
meta-llama/llama-3.3-70b-instruct |
0.728 | 0.056 |
mistralai/mistral-medium-3.1 |
0.718 | 0.140 |
claude-sonnet-4-6 |
0.714 | 0.000 |
google/gemini-3.5-flash |
0.714 | 0.000 |
qwen/qwen3.5-plus-02-15 |
0.714 | 0.000 |
qwen/qwen3.6-plus |
0.714 | 0.000 |
x-ai/grok-4.3 |
0.714 | 0.000 |
openai/o3 |
0.714 | 0.118 |
openai/gpt-5.5 |
0.708 | 0.056 |
deepseek/deepseek-v4-flash |
0.695 | 0.067 |
cohere/command-r-plus-08-2024 |
0.687 | 0.055 |
minimax/minimax-m3 |
0.676 | 0.021 |
openai/gpt-oss-120b |
0.669 | 0.045 |
openai/gpt-5.4 |
0.668 | 0.032 |
meta-llama/llama-4-scout |
0.667 | 0.090 |
google/gemini-2.5-flash |
0.667 | 0.000 |
google/gemma-4-31b-it |
0.667 | 0.000 |
deepseek/deepseek-r1 |
0.661 | 0.074 |
meta-llama/llama-4-maverick |
0.660 | 0.037 |
google/gemini-2.5-pro |
0.650 | 0.023 |
openai/gpt-5.4-mini |
0.643 | 0.035 |
deepseek/deepseek-v4-pro |
0.634 | 0.150 |
google/gemini-3.1-flash-lite |
0.582 | 0.015 |
deepseek/deepseek-v3.2 |
0.553 | 0.070 |
qwen/qwen3-235b-a22b-2507 |
0.503 | 0.286 |
mistralai/codestral-2508 |
0.501 | 0.047 |
qwen/qwen3.5-27b |
0.488 | 0.090 |
cohere/command-a |
0.456 | 0.030 |
deepseek/deepseek-r1-0528 |
0.421 | 0.105 |
google/gemini-2.5-flash-lite |
0.411 | 0.072 |
mistralai/mistral-large-2512 |
0.367 | 0.054 |
qwen/qwen3-14b |
0.351 | 0.257 |
nvidia/nemotron-nano-9b-v2 |
0.333 | 0.183 |
deepseek/deepseek-r1-distill-llama-70b |
0.317 | 0.022 |
openai/gpt-3.5-turbo |
0.275 | 0.006 |
moonshotai/kimi-k2.6 |
0.196 | 0.245 |
meta-llama/llama-3.1-8b-instruct |
0.141 | 0.096 |
openai/o4-mini |
0.114 | 0.156 |
microsoft/phi-4 |
0.076 | 0.105 |
mistralai/mistral-7b-instruct-v0.1 |
0.000 | 0.000 |
qwen/qwen3-8b |
0.000 | 0.000 |
ep-the-brilliant-idiots-0bb9bf634c8e: Class Rank
Section titled “ep-the-brilliant-idiots-0bb9bf634c8e: Class Rank”- Podcast: the-brilliant-idiots
- Duration: 119.9 min
- Truth ads: 3
| Model | F1 | F1 stdev |
|---|---|---|
google/gemini-3.5-flash |
1.000 | 0.000 |
claude-sonnet-4-6 |
0.971 | 0.064 |
qwen/qwen3.6-flash |
0.933 | 0.149 |
qwen/qwen3.6-plus |
0.921 | 0.114 |
x-ai/grok-4.3 |
0.914 | 0.078 |
openai/gpt-5.5 |
0.903 | 0.092 |
qwen/qwen3.5-plus-02-15 |
0.886 | 0.064 |
claude-haiku-4-5-20251001 |
0.857 | 0.000 |
openai/gpt-oss-120b |
0.857 | 0.000 |
claude-opus-4-7 |
0.836 | 0.048 |
claude-opus-4-8 |
0.821 | 0.110 |
openai/o3 |
0.740 | 0.279 |
deepseek/deepseek-v4-flash |
0.717 | 0.046 |
qwen/qwen3.5-27b |
0.716 | 0.236 |
google/gemma-4-31b-it |
0.700 | 0.046 |
meta-llama/llama-4-scout |
0.681 | 0.074 |
mistralai/mistral-medium-3.1 |
0.679 | 0.098 |
google/gemini-2.5-flash |
0.667 | 0.000 |
google/gemini-2.5-pro |
0.653 | 0.030 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.613 | 0.119 |
moonshotai/kimi-k2.6 |
0.598 | 0.234 |
google/gemini-2.5-flash-lite |
0.580 | 0.045 |
openai/gpt-5.4 |
0.568 | 0.125 |
meta-llama/llama-3.3-70b-instruct |
0.557 | 0.032 |
mistralai/codestral-2508 |
0.542 | 0.099 |
minimax/minimax-m3 |
0.528 | 0.099 |
google/gemini-3.1-flash-lite |
0.520 | 0.038 |
meta-llama/llama-4-maverick |
0.492 | 0.160 |
deepseek/deepseek-r1 |
0.487 | 0.043 |
qwen/qwen3-235b-a22b-2507 |
0.392 | 0.096 |
qwen/qwen3-14b |
0.390 | 0.102 |
nvidia/nemotron-nano-9b-v2 |
0.386 | 0.232 |
openai/gpt-5.4-mini |
0.375 | 0.141 |
deepseek/deepseek-r1-0528 |
0.338 | 0.045 |
mistralai/mistral-large-2512 |
0.310 | 0.018 |
cohere/command-a |
0.304 | 0.020 |
deepseek/deepseek-r1-distill-llama-70b |
0.301 | 0.127 |
openai/gpt-3.5-turbo |
0.233 | 0.006 |
deepseek/deepseek-v4-pro |
0.180 | 0.249 |
openai/o4-mini |
0.180 | 0.249 |
microsoft/phi-4 |
0.174 | 0.105 |
deepseek/deepseek-v3.2 |
0.100 | 0.224 |
cohere/command-r-plus-08-2024 |
0.000 | 0.000 |
meta-llama/llama-3.1-8b-instruct |
0.000 | 0.000 |
mistralai/mistral-7b-instruct-v0.1 |
0.000 | 0.000 |
qwen/qwen3-8b |
0.000 | 0.000 |
ep-the-tim-dillon-show-f62bd5fa1cfe: 495 - Hantavirus Cruise & iPad Babies
Section titled “ep-the-tim-dillon-show-f62bd5fa1cfe: 495 - Hantavirus Cruise & iPad Babies”- Podcast: the-tim-dillon-show
- Duration: 80.1 min
- Truth ads: 6
| Model | F1 | F1 stdev |
|---|---|---|
claude-haiku-4-5-20251001 |
0.833 | 0.000 |
google/gemini-2.5-flash |
0.833 | 0.000 |
qwen/qwen3.5-plus-02-15 |
0.800 | 0.000 |
qwen/qwen3.6-plus |
0.800 | 0.000 |
google/gemma-4-31b-it |
0.799 | 0.077 |
deepseek/deepseek-v4-flash |
0.791 | 0.058 |
x-ai/grok-4.3 |
0.781 | 0.120 |
claude-opus-4-7 |
0.760 | 0.089 |
google/gemini-3.5-flash |
0.760 | 0.089 |
mistralai/mistral-medium-3.1 |
0.745 | 0.062 |
qwen/qwen3.6-flash |
0.744 | 0.057 |
openai/gpt-5.4 |
0.735 | 0.110 |
deepseek/deepseek-r1 |
0.730 | 0.084 |
google/gemini-3.1-flash-lite |
0.727 | 0.000 |
google/gemini-2.5-pro |
0.720 | 0.110 |
openai/gpt-oss-120b |
0.695 | 0.071 |
deepseek/deepseek-v4-pro |
0.687 | 0.124 |
claude-opus-4-8 |
0.684 | 0.130 |
minimax/minimax-m3 |
0.680 | 0.110 |
openai/gpt-5.5 |
0.680 | 0.110 |
claude-sonnet-4-6 |
0.615 | 0.000 |
qwen/qwen3.5-27b |
0.607 | 0.157 |
qwen/qwen3-235b-a22b-2507 |
0.589 | 0.125 |
google/gemini-2.5-flash-lite |
0.579 | 0.064 |
deepseek/deepseek-r1-0528 |
0.545 | 0.210 |
mistralai/codestral-2508 |
0.535 | 0.036 |
meta-llama/llama-4-scout |
0.505 | 0.072 |
openai/gpt-5.4-mini |
0.443 | 0.130 |
mistralai/mistral-large-2512 |
0.409 | 0.059 |
meta-llama/llama-3.3-70b-instruct |
0.400 | 0.000 |
deepseek/deepseek-v3.2 |
0.389 | 0.147 |
openai/o3 |
0.381 | 0.087 |
microsoft/phi-4 |
0.312 | 0.084 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.290 | 0.254 |
cohere/command-a |
0.255 | 0.100 |
qwen/qwen3-14b |
0.244 | 0.177 |
meta-llama/llama-4-maverick |
0.222 | 0.000 |
meta-llama/llama-3.1-8b-instruct |
0.211 | 0.073 |
moonshotai/kimi-k2.6 |
0.189 | 0.107 |
nvidia/nemotron-nano-9b-v2 |
0.180 | 0.130 |
openai/gpt-3.5-turbo |
0.143 | 0.000 |
deepseek/deepseek-r1-distill-llama-70b |
0.126 | 0.138 |
cohere/command-r-plus-08-2024 |
0.057 | 0.128 |
qwen/qwen3-8b |
0.057 | 0.128 |
mistralai/mistral-7b-instruct-v0.1 |
0.000 | 0.000 |
openai/o4-mini |
0.000 | 0.000 |
ep-tosh-show-5f6894439bb6: My Mom - Emergency Pod
Section titled “ep-tosh-show-5f6894439bb6: My Mom - Emergency Pod”- Podcast: tosh-show
- Duration: 41.4 min
- Truth ads: 5
| Model | F1 | F1 stdev |
|---|---|---|
qwen/qwen3.5-plus-02-15 |
0.827 | 0.167 |
claude-opus-4-8 |
0.800 | 0.122 |
x-ai/grok-4.3 |
0.782 | 0.122 |
claude-haiku-4-5-20251001 |
0.727 | 0.000 |
claude-sonnet-4-6 |
0.727 | 0.000 |
google/gemini-3.1-flash-lite |
0.727 | 0.000 |
meta-llama/llama-4-scout |
0.727 | 0.000 |
mistralai/mistral-large-2512 |
0.727 | 0.000 |
qwen/qwen3.6-flash |
0.727 | 0.000 |
mistralai/codestral-2508 |
0.718 | 0.055 |
qwen/qwen3.6-plus |
0.716 | 0.158 |
deepseek/deepseek-r1-0528 |
0.708 | 0.159 |
qwen/qwen3.5-27b |
0.707 | 0.141 |
mistralai/mistral-medium-3.1 |
0.702 | 0.057 |
deepseek/deepseek-r1 |
0.681 | 0.094 |
openai/gpt-oss-120b |
0.678 | 0.139 |
google/gemini-2.5-flash-lite |
0.676 | 0.070 |
deepseek/deepseek-v4-flash |
0.669 | 0.174 |
google/gemini-2.5-flash |
0.667 | 0.000 |
openai/gpt-5.5 |
0.633 | 0.126 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0.633 | 0.226 |
claude-opus-4-7 |
0.622 | 0.186 |
openai/gpt-5.4 |
0.622 | 0.099 |
minimax/minimax-m3 |
0.609 | 0.080 |
google/gemini-2.5-pro |
0.609 | 0.096 |
openai/gpt-5.4-mini |
0.607 | 0.068 |
google/gemini-3.5-flash |
0.536 | 0.133 |
cohere/command-a |
0.533 | 0.122 |
meta-llama/llama-3.3-70b-instruct |
0.514 | 0.101 |
openai/o3 |
0.475 | 0.106 |
qwen/qwen3-235b-a22b-2507 |
0.462 | 0.116 |
meta-llama/llama-4-maverick |
0.444 | 0.000 |
qwen/qwen3-14b |
0.429 | 0.178 |
deepseek/deepseek-r1-distill-llama-70b |
0.357 | 0.139 |
nvidia/nemotron-nano-9b-v2 |
0.320 | 0.137 |
google/gemma-4-31b-it |
0.311 | 0.122 |
deepseek/deepseek-v4-pro |
0.305 | 0.312 |
cohere/command-r-plus-08-2024 |
0.289 | 0.087 |
moonshotai/kimi-k2.6 |
0.267 | 0.149 |
deepseek/deepseek-v3.2 |
0.257 | 0.251 |
openai/gpt-3.5-turbo |
0.209 | 0.012 |
meta-llama/llama-3.1-8b-instruct |
0.197 | 0.017 |
openai/o4-mini |
0.133 | 0.183 |
microsoft/phi-4 |
0.000 | 0.000 |
mistralai/mistral-7b-instruct-v0.1 |
0.000 | 0.000 |
qwen/qwen3-8b |
0.000 | 0.000 |
Parser stress test
Section titled “Parser stress test”How each model’s responses were actually parsed. Columns are extraction methods, ordered alphabetically; rows are models, sorted by parse-failure rate (cleanest at top). json_array_direct is the happy path: a bare JSON array we could json.loads and process immediately. markdown_code_block means we had to strip triple-backtick fences first; json_object_* means the model wrapped the array in an outer object and we had to find the array key; regex_* are last-resort recovery paths. A model that needs anything but json_array_direct for most calls is fragile. It works today, but a small prompt change can break the parser.
| Model | bracket_fallback | json_array_direct | json_object_ads_key | json_object_no_ads | json_object_segments_key | json_object_single_ad | json_object_single_ad_truncated | json_object_window_segments | markdown_code_block | parse_failure | regex_json_array |
|---|---|---|---|---|---|---|---|---|---|---|---|
claude-haiku-4-5-20251001 |
0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 855 | 0 | 0 |
claude-opus-4-7 |
0 | 850 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 5 |
claude-opus-4-8 |
0 | 836 | 0 | 0 | 0 | 0 | 3 | 0 | 0 | 0 | 16 |
claude-sonnet-4-6 |
0 | 783 | 0 | 0 | 0 | 0 | 0 | 0 | 57 | 0 | 15 |
cohere/command-a |
0 | 0 | 0 | 29 | 0 | 826 | 0 | 0 | 0 | 0 | 0 |
cohere/command-r-plus-08-2024 |
0 | 0 | 27 | 783 | 0 | 45 | 0 | 0 | 0 | 0 | 0 |
deepseek/deepseek-v3.2 |
0 | 501 | 16 | 3 | 0 | 335 | 0 | 0 | 0 | 0 | 0 |
google/gemini-2.5-flash |
0 | 855 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
google/gemini-3.1-flash-lite |
0 | 799 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 56 |
google/gemini-3.5-flash |
0 | 850 | 0 | 0 | 0 | 0 | 1 | 0 | 0 | 0 | 4 |
meta-llama/llama-4-maverick |
0 | 0 | 0 | 315 | 0 | 540 | 0 | 0 | 0 | 0 | 0 |
mistralai/codestral-2508 |
0 | 855 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
mistralai/mistral-large-2512 |
0 | 855 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
mistralai/mistral-medium-3.1 |
0 | 854 | 0 | 0 | 0 | 0 | 1 | 0 | 0 | 0 | 0 |
openai/gpt-5.4 |
0 | 0 | 0 | 326 | 0 | 529 | 0 | 0 | 0 | 0 | 0 |
openai/gpt-5.4-mini |
0 | 0 | 2 | 300 | 2 | 551 | 0 | 0 | 0 | 0 | 0 |
qwen/qwen3-235b-a22b-2507 |
0 | 173 | 1 | 94 | 0 | 587 | 0 | 0 | 0 | 0 | 0 |
qwen/qwen3.6-flash |
0 | 855 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
qwen/qwen3.6-plus |
0 | 855 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
google/gemma-4-31b-it |
1 | 0 | 455 | 216 | 0 | 180 | 2 | 0 | 0 | 1 | 0 |
meta-llama/llama-3.1-8b-instruct |
0 | 371 | 0 | 66 | 0 | 417 | 0 | 0 | 0 | 1 | 0 |
openai/gpt-5.5 |
0 | 0 | 0 | 494 | 0 | 360 | 0 | 0 | 0 | 1 | 0 |
x-ai/grok-4.3 |
0 | 854 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 1 | 0 |
qwen/qwen3.5-plus-02-15 |
0 | 851 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 1 | 0 |
openai/gpt-3.5-turbo |
0 | 0 | 0 | 50 | 0 | 800 | 0 | 0 | 0 | 5 | 0 |
openai/o3 |
0 | 0 | 34 | 621 | 12 | 183 | 0 | 0 | 0 | 5 | 0 |
deepseek/deepseek-r1 |
0 | 760 | 2 | 17 | 7 | 44 | 0 | 0 | 17 | 6 | 2 |
meta-llama/llama-4-scout |
37 | 5 | 644 | 92 | 0 | 62 | 0 | 0 | 0 | 9 | 6 |
microsoft/phi-4 |
0 | 421 | 31 | 27 | 20 | 335 | 0 | 2 | 0 | 9 | 10 |
google/gemini-2.5-pro |
0 | 818 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 12 | 25 |
minimax/minimax-m3 |
0 | 625 | 0 | 0 | 0 | 0 | 1 | 0 | 215 | 14 | 0 |
deepseek/deepseek-r1-distill-llama-70b |
0 | 20 | 68 | 104 | 0 | 642 | 5 | 0 | 0 | 15 | 1 |
deepseek/deepseek-v4-flash |
0 | 102 | 435 | 21 | 7 | 272 | 0 | 0 | 0 | 17 | 1 |
google/gemini-2.5-flash-lite |
0 | 793 | 0 | 0 | 0 | 0 | 43 | 0 | 0 | 19 | 0 |
deepseek/deepseek-v4-pro |
0 | 229 | 63 | 131 | 314 | 86 | 2 | 0 | 5 | 23 | 2 |
nvidia/nemotron-nano-9b-v2 |
0 | 770 | 0 | 0 | 0 | 0 | 15 | 0 | 0 | 56 | 14 |
deepseek/deepseek-r1-0528 |
0 | 700 | 34 | 3 | 0 | 30 | 3 | 0 | 2 | 83 | 0 |
qwen/qwen3.5-27b |
0 | 633 | 0 | 89 | 0 | 12 | 0 | 0 | 0 | 121 | 0 |
nvidia/llama-3.3-nemotron-super-49b-v1.5 |
0 | 441 | 0 | 0 | 0 | 0 | 3 | 0 | 257 | 124 | 30 |
openai/gpt-oss-120b |
0 | 68 | 235 | 186 | 0 | 188 | 6 | 0 | 0 | 149 | 23 |
moonshotai/kimi-k2.6 |
0 | 68 | 35 | 109 | 2 | 397 | 0 | 0 | 5 | 239 | 0 |
meta-llama/llama-3.3-70b-instruct |
0 | 143 | 1 | 144 | 0 | 264 | 0 | 0 | 0 | 300 | 3 |
mistralai/mistral-7b-instruct-v0.1 |
1 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 509 | 345 |
qwen/qwen3-14b |
0 | 0 | 0 | 1 | 0 | 338 | 0 | 0 | 0 | 516 | 0 |
openai/o4-mini |
0 | 0 | 0 | 19 | 0 | 33 | 0 | 0 | 0 | 803 | 0 |
qwen/qwen3-8b |
18 | 4 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 833 | 0 |
Methodology
Section titled “Methodology”Reproducibility settings used for this run. The benchmark sends the same prompts MinusPod sends in production (same system prompt, same sponsor list, same windowing) so the F1 numbers here are directly relevant to production accuracy decisions. Cost is recomputed at report time from token counts against the active pricing snapshot, so all rows compare at the same prices regardless of when the actual call ran.
- Trials per (model, episode): 5, temperature 0.0
- max_tokens: 4096 (matches MinusPod production)
- response_format: json_object (with prompt-injection fallback when provider rejects native)
- Window size: 10 min, overlap: 3 min (imported from MinusPod’s create_windows)
- Pricing snapshot: 2026-06-02T23:38:06.275985Z
- Corpus episodes: 14
Transcript source
Section titled “Transcript source”segments.json for every corpus episode is pulled byte-exact from the source MinusPod instance’s original-segments endpoint. The transcript itself was generated by faster-whisper inside that instance, not by the benchmark. Model choice and decoding params affect what gets transcribed, which sets an upper bound on what every benchmarked LLM can find.
Whisper config:
| Setting | Value |
|---|---|
| Model | large-v3 |
| Backend | local (faster-whisper, CUDA GPU) |
| Compute type | auto (resolves to float16 on CUDA) |
| Language | en (forced English, not auto-detect) |
| VAD gap detection | on (start 3.0s / mid 8.0s / tail 3.0s) |
model.transcribe() invocation (from src/transcriber.py):
WhisperModel(model_size="large-v3", device="cuda", compute_type="auto")model.transcribe( audio, language="en", initial_prompt=<podcast name + SEED_SPONSORS vocabulary>, beam_size=5, batch_size=<adaptive: 16/12/8/4 by episode length>, word_timestamps=True, vad_filter=True, vad_parameters={"min_silence_duration_ms": 1000, "speech_pad_ms": 600, "threshold": 0.3},)The initial_prompt carries a sponsor vocabulary so Whisper produces consistent spellings (Athletic Greens rather than AG1, ExpressVPN rather than express vpn). This biases what shows up in the transcript and therefore what every benchmarked LLM is scored against.
Sponsor vocabulary (254 canonical sponsors, 44 of them with explicit alias spellings totaling 48 aliases; from src/utils/constants.py SEED_SPONSORS). Laid out in two side-by-side groups, read top-to-bottom in each group.
| Sponsor | Aliases | Category | Sponsor | Aliases | Category |
|---|---|---|---|---|---|
| 1Password | One Password |
tech | MacPaw | CleanMyMac |
tech |
| Acorns | - | finance | Magic Mind | - | beverage |
| ADT | - | home | Magic Spoon | - | food |
| Affirm | - | finance_fintech | Mailchimp | - | tech_software_saas |
| Airbnb | - | travel_hospitality | Manscaped | - | personal |
| Airtable | - | tech_software_saas | MasterClass | Master Class |
education |
| Alani Nu | - | food_beverage_nutrition | McDonald’s | - | food_beverage_nutrition |
| Allbirds | - | ecommerce_retail_dtc | Mercury | - | finance_fintech |
| Alo Yoga | - | ecommerce_retail_dtc | Meter | - | b2b_startup |
| Amazon | - | retail | Midjourney | - | tech_software_saas |
| Anthropic | - | tech_software_saas | Mint Mobile | MintMobile |
telecom |
| Apple TV+ | - | media_streaming | Miro | - | tech |
| Asana | - | tech_software_saas | Momentous | - | mental_health_wellness |
| AT&T | - | telecom | Monarch Money | - | finance |
| Athletic Brewing | - | beverage | Monday.com | Monday |
tech |
| Athletic Greens | AG1, AG One |
health | Native | - | personal |
| Audible | - | entertainment | NerdWallet | - | finance_fintech |
| Aura | - | tech | Netflix | - | media_streaming |
| Babbel | - | education | NetSuite | Net Suite |
tech |
| BetMGM | Bet MGM |
gambling | Noom | - | mental_health_wellness |
| BetterHelp | Better Help |
health | NordVPN | Nord VPN |
vpn |
| Betterment | - | finance | Notion | - | tech |
| Bill.com | - | finance_fintech | Nutrafol | - | health |
| Birchbox | - | ecommerce_retail_dtc | Okta | - | tech_software_saas |
| Bitwarden | Bit Warden |
tech | OLIPOP | - | food_beverage_nutrition |
| Blinkist | - | education | OneSkin | One Skin |
personal |
| Bloom Nutrition | - | food_beverage_nutrition | OpenAI | - | tech_software_saas |
| Blue Apron | - | food | Outdoor Voices | - | ecommerce_retail_dtc |
| Bombas | - | apparel | OutSystems | - | tech |
| Booking.com | - | travel_hospitality | PagerDuty | - | b2b_startup |
| Bose | - | electronics | Paramount+ | - | media_streaming |
| Brex | - | finance_fintech | Patreon | - | tech_software_saas |
| Brilliant | - | tech_software_saas | Perplexity | - | tech_software_saas |
| Brooklinen | - | home | Plaid | - | finance_fintech |
| Butcher Box | ButcherBox |
food | PolicyGenius | Policy Genius |
finance |
| CacheFly | - | tech | Poppi | - | food_beverage_nutrition |
| Caesars Sportsbook | - | gaming_sports_betting | Poshmark | - | ecommerce_retail_dtc |
| Calm | - | health | Progressive | - | finance |
| Canva | - | tech | Public.com | - | finance_fintech |
| Capital One | - | finance | Pura | - | home_security |
| Care/of | Care of, Careof |
health | Purple | - | home |
| CarMax | Car Max |
auto | QuickBooks | - | finance_fintech |
| Carvana | - | auto | Quince | - | apparel |
| Casper | - | home | Quip | - | personal |
| Cerebral | - | mental_health_wellness | Ramp | - | finance_fintech |
| Chime | - | finance_fintech | Raycon | - | electronics |
| ClickUp | - | tech_software_saas | Retool | - | tech_software_saas |
| Cloudflare | - | tech_software_saas | Ring | - | home |
| Coinbase | - | finance_fintech | Rippling | - | b2b_startup |
| Comcast | - | telecom | Ritual | - | health |
| Cozy Earth | - | home | Ro | - | mental_health_wellness |
| Credit Karma | - | finance | Robinhood | - | finance_fintech |
| CrowdStrike | - | tech_software_saas | Rocket Lawyer | - | insurance_legal |
| Cursor | - | tech_software_saas | Rocket Money | RocketMoney, Truebill |
finance |
| Databricks | - | tech_software_saas | Roman | - | health |
| Datadog | - | tech_software_saas | Rosetta Stone | - | education |
| Deel | - | business | Rothy’s | - | ecommerce_retail_dtc |
| DeleteMe | Delete Me |
tech | Saatva | - | ecommerce_retail_dtc |
| Disney+ | - | media_streaming | Salesforce | - | tech_software_saas |
| DocuSign | - | tech_software_saas | SeatGeek | - | gaming_sports_betting |
| Dollar Shave Club | DSC |
personal | Seed | - | health |
| DoorDash | Door Dash |
food | SendGrid | - | tech_software_saas |
| DraftKings | Draft Kings |
gambling | ServiceNow | - | tech_software_saas |
| Duolingo | - | tech_software_saas | Shein | - | ecommerce_retail_dtc |
| eBay Motors | - | auto | Shopify | - | tech |
| Eight Sleep | - | mental_health_wellness | SimpliSafe | Simpli Safe |
home |
| ElevenLabs | - | tech_software_saas | SiriusXM | - | media_streaming |
| ESPN Bet | - | gaming_sports_betting | Skillshare | - | tech_software_saas |
| Everlane | - | ecommerce_retail_dtc | SKIMS | - | ecommerce_retail_dtc |
| EveryPlate | - | food_beverage_nutrition | Skyscanner | - | travel_hospitality |
| Expedia | - | travel_hospitality | Slack | - | tech_software_saas |
| ExpressVPN | Express VPN |
vpn | Snowflake | - | tech_software_saas |
| FabFitFun | - | ecommerce_retail_dtc | SoFi | - | finance |
| Factor | - | food | Spaceship | - | tech |
| FanDuel | Fan Duel |
gambling | Splunk | - | b2b_startup |
| Figma | - | tech_software_saas | Spotify | - | media_streaming |
| Ford | - | auto | Squarespace | Square Space |
tech |
| Framer | - | tech | Stamps.com | Stamps |
business |
| FreshBooks | - | finance_fintech | Starbucks | - | food_beverage_nutrition |
| Function Health | - | mental_health_wellness | State Farm | - | finance |
| Function of Beauty | - | personal | Stitch Fix | - | ecommerce_retail_dtc |
| Gametime | Game Time |
entertainment | StockX | - | ecommerce_retail_dtc |
| Geico | - | finance | Stripe | - | finance_fintech |
| GitHub | - | tech_software_saas | StubHub | - | gaming_sports_betting |
| GitHub Copilot | - | tech_software_saas | Substack | - | tech_software_saas |
| GOAT | - | ecommerce_retail_dtc | T-Mobile | TMobile |
telecom |
| GoodRx | Good Rx |
health | Talkspace | - | mental_health_wellness |
| Gopuff | - | ecommerce_retail_dtc | Temu | - | ecommerce_retail_dtc |
| Grammarly | - | tech | Ten Thousand | - | ecommerce_retail_dtc |
| Green Chef | GreenChef |
food | Thinkst Canary | - | tech |
| Grubhub | Grub Hub |
food | Thorne | - | mental_health_wellness |
| Gusto | - | b2b_startup | ThreatLocker | - | tech |
| Harry’s | Harrys |
personal | ThredUp | - | ecommerce_retail_dtc |
| HBO Max | - | media_streaming | Thrive Market | - | food |
| Headspace | Head Space |
health | Toyota | - | auto |
| Helix Sleep | Helix |
home | Transparent Labs | - | food_beverage_nutrition |
| HelloFresh | Hello Fresh |
food | Turo | - | automotive_transport |
| Hers | - | health | Twilio | - | tech_software_saas |
| Hims | - | health | Uber | - | automotive_transport |
| Honeylove | Honey Love |
apparel | Uber Eats | UberEats |
food |
| Hopper | - | travel_hospitality | UnitedHealth Group | - | finance_fintech |
| HubSpot | Hub Spot |
tech | Vanta | - | tech |
| Huel | - | food_beverage_nutrition | Veeam | - | tech |
| Hyundai | - | auto | Vercel | - | tech_software_saas |
| iHeartRadio | - | media_streaming | Verizon | - | telecom |
| Imperfect Foods | - | food_beverage_nutrition | Visible | - | telecom |
| Incogni | - | tech | Vrbo | - | travel_hospitality |
| Indeed | - | jobs | Vuori | - | ecommerce_retail_dtc |
| Inside Tracker | - | mental_health_wellness | Warby Parker | - | ecommerce_retail_dtc |
| Instacart | - | food | Wayfair | - | ecommerce_retail_dtc |
| Intuit | - | finance_fintech | Waymo | - | automotive_transport |
| Joovv | - | mental_health_wellness | Wealthfront | - | finance |
| Kayak | - | travel_hospitality | WebBank | - | finance_fintech |
| Klarna | - | finance_fintech | Webflow | - | b2b_startup |
| Klaviyo | - | tech_software_saas | - | tech | |
| LegalZoom | - | insurance_legal | WHOOP | - | mental_health_wellness |
| Lemonade | - | finance | Workday | - | tech_software_saas |
| Levels | - | mental_health_wellness | Xero | - | finance_fintech |
| Liberty Mutual | - | finance | YouTube | - | media_streaming |
| Lime | - | automotive_transport | YouTube TV | - | media_streaming |
| Linear | - | tech_software_saas | Zapier | - | tech |
LinkedIn Jobs |
jobs | Zendesk | - | tech_software_saas | |
| Liquid IV | Liquid I.V. |
health | ZipRecruiter | Zip Recruiter |
jobs |
| LMNT | Element |
health | ZocDoc | Zoc Doc |
health |
| Loom | - | tech_software_saas | Zoom | - | tech_software_saas |
| Lululemon | - | ecommerce_retail_dtc | Zscaler | - | tech |
| Lyft | - | automotive_transport | Zyn | ZYN, Zinn |
tobacco_nicotine |
Mishearing corrections (174 entries, from src/utils/constants.py SPONSOR_ALIASES). Applied post-transcription to normalize Whisper output toward the canonical sponsor name. Distinct from the aliases column above, which lists intentional alternative spellings (e.g. AG1 vs Athletic Greens); the entries below are mostly Whisper mishearings (e.g. a firm -> Affirm, xerox -> Xero). Laid out in three side-by-side groups, read top-to-bottom in each group.
| Heard as | Normalized to | Heard as | Normalized to | Heard as | Normalized to |
|---|---|---|---|---|---|
1 password |
1Password | good-rx |
GoodRx | patron |
Patreon |
8 sleep |
Eight Sleep | green chef |
Green Chef | pay tree on |
Patreon |
8-sleep |
Eight Sleep | green-chef |
Green Chef | perplexity ai |
Perplexity |
a firm |
Affirm | greenchef |
Green Chef | perplexity-ai |
Perplexity |
a g one |
Athletic Greens | grub hub |
Grubhub | policy genius |
PolicyGenius |
ag 1 |
Athletic Greens | grub-hub |
Grubhub | policy-genius |
PolicyGenius |
ag one |
Athletic Greens | harrys |
Harry’s | pyura |
Pura |
ag1 |
Athletic Greens | head space |
Headspace | ray con |
Raycon |
athlean x |
Athlean-X | head-space |
Headspace | ray-con |
Raycon |
athlean-x |
Athlean-X | hello fresh |
HelloFresh | re tool |
Retool |
athletic greens one |
Athletic Greens | hello-fresh |
HelloFresh | ro gain |
Rogaine |
athleticgreens |
Athletic Greens | him's |
Hims | ro-gaine |
Rogaine |
bet mgm |
BetMGM | hims & hers |
Hims & Hers | rocket money |
Rocket Money |
bet-mgm |
BetMGM | hims and hers |
Hims & Hers | rocket-money |
Rocket Money |
better help |
BetterHelp | honey love |
Honeylove | rocketlawyer |
Rocket Lawyer |
better-help |
BetterHelp | honey-love |
Honeylove | rocketmoney |
Rocket Money |
birch box |
Birchbox | honeylove |
Honeylove | rocketmortgage |
Rocket Mortgage |
birch-box |
Birchbox | hub spot |
HubSpot | seat geek |
SeatGeek |
bit warden |
Bitwarden | hub-spot |
HubSpot | seat-geek |
SeatGeek |
bit-warden |
Bitwarden | hubs pot |
HubSpot | shop a fly |
Shopify |
blueapron |
Blue Apron | imperfect foods |
Imperfect Foods | shop fly |
Shopify |
brecks |
Brex | imperfectfoods |
Imperfect Foods | shop ify |
Shopify |
butcher box |
Butcher Box | insta cart |
Instacart | simpli safe |
SimpliSafe |
butcher-box |
Butcher Box | insta-cart |
Instacart | simpli-safe |
SimpliSafe |
butcherbox |
Butcher Box | l m n t |
LMNT | simply safe |
SimpliSafe |
car max |
CarMax | legal zoom |
LegalZoom | sky scanner |
Skyscanner |
car-max |
CarMax | legal-zoom |
LegalZoom | sky-scanner |
Skyscanner |
cloud flare |
Cloudflare | legalzoom |
LegalZoom | so fi |
SoFi |
cloud-flare |
Cloudflare | liquid i v |
Liquid IV | so-fi |
SoFi |
co pilot |
GitHub Copilot | liquid i.v. |
Liquid IV | square space |
Squarespace |
co-pilot |
GitHub Copilot | liquid iv |
Liquid IV | square-space |
Squarespace |
copilot |
GitHub Copilot | liquidiv |
Liquid IV | stamp dot com |
Stamps.com |
creditkarma |
Credit Karma | magic mind |
Magic Mind | stitch fix |
Stitch Fix |
delete me |
DeleteMe | magic spoon |
Magic Spoon | stitch-fix |
Stitch Fix |
delete-me |
DeleteMe | magicmind |
Magic Mind | stitchfix |
Stitch Fix |
dollarshaveclub |
Dollar Shave Club | magicspoon |
Magic Spoon | stub hub |
StubHub |
door dash |
DoorDash | master class |
MasterClass | stub-hub |
StubHub |
door-dash |
DoorDash | master-class |
MasterClass | sub stack |
Substack |
draft kings |
DraftKings | mercury bank |
Mercury | sub-stack |
Substack |
draft-kings |
DraftKings | mercury-bank |
Mercury | thrive market |
Thrive Market |
eight-sleep |
Eight Sleep | mint mobile |
Mint Mobile | thrivemarket |
Thrive Market |
eightsleep |
Eight Sleep | mint-mobile |
Mint Mobile | transparent labs |
Transparent Labs |
element |
LMNT | mintmobile |
Mint Mobile | transparentlabs |
Transparent Labs |
every plate |
EveryPlate | monarch money |
Monarch Money | uber eats |
Uber Eats |
every-plate |
EveryPlate | monarch-money |
Monarch Money | uber-eats |
Uber Eats |
express vpn |
ExpressVPN | monarchmoney |
Monarch Money | ubereats |
Uber Eats |
express-vpn |
ExpressVPN | my protein |
Myprotein | ver cell |
Vercel |
fab fit fun |
FabFitFun | my ro |
Miro | ver sel |
Vercel |
fab-fit-fun |
FabFitFun | myprotein |
Myprotein | wealth front |
Wealthfront |
fan duel |
FanDuel | net suite |
NetSuite | wealth-front |
Wealthfront |
fan-duel |
FanDuel | net-suite |
NetSuite | woop |
Whoop |
game time |
Gametime | nord vpn |
NordVPN | xerox |
Xero |
game-time |
Gametime | nord-vpn |
NordVPN | zero |
Xero |
gametime |
Gametime | one password |
1Password | zip recruiter |
ZipRecruiter |
github-copilot |
GitHub Copilot | one skin |
OneSkin | zip-recruiter |
ZipRecruiter |
go puff |
Gopuff | one-password |
1Password | zoc doc |
ZocDoc |
go-puff |
Gopuff | one-skin |
OneSkin | zoc-doc |
ZocDoc |
good rx |
GoodRx | p ninety x |
P90X | zock doc |
ZocDoc |
Run Metadata
Section titled “Run Metadata”- Report generated: 2026-07-12T11:18:23Z
- Unique work units (current state, last-write-wins after retries): 39330
- Raw rows in calls.jsonl: 39961 (631 superseded by later retries; kept for audit)
- Successful: 39327
- Failed: 3
- Lifetime actual spend (sum of at-runtime costs, includes superseded rows): $340.6741
- Active pricing snapshot: 2026-06-02T23:38:06.275985Z
- System prompt: live (sha256:cade17f4)